

 LinkedIn
Most AI visibility tools sell you a score. I have watched that movie in paid search: the impressions chart looks great in a slide, then nobody can tell you which query lost the sale. My pick for most businesses is measurement tied to execution, where the team tracking a missed buyer prompt also ships the content fix. If all you need is a number for the boss, buy the cheapest dashboard and stop here.
I rank five approaches by one test. After seven days, can you name which buyer prompts you missed, who got cited instead, and what gap on your site explains it? A tool that answers the first two questions but leaves the third in someone’s backlog has only done part of the job. That distinction drives this ranking.
How I judge a visibility tool
I use five checks. None is complicated; the trick is refusing to collapse them into one percentage.
- Prompt discovery: Does it find buyer questions that trigger a mention, or only track the prompts you typed in?
- Citation attribution: Does it show the cited URL and who appeared instead of you?
- Gap diagnosis: Can you identify what is missing on your site that explains the miss?
- Engine coverage: Does it cover ChatGPT, Gemini, Perplexity and Google AI Overviews, at minimum? Buyers do not stay in one engine.
- Cost per useful insight: How much did you pay for fixes you can actually make, rather than for rows in a report?
A single visibility percentage cannot answer those questions. Seer Interactive called AI visibility alone a vanity metric: answers change by prompt and by person, and there are no platform-reported rankings to anchor the score. In one 968-run study, 42.9% of prompt-engine pairs flipped between mentioned and not mentioned at least once; the median cited-domain overlap between consecutive runs was 0.41. A snapshot can turn that movement into a story it has not earned.
I want a 14- to 28-day window, split by engine, with branded and unbranded prompts kept apart. The first week tells you whether a tool can expose a useful gap. The longer window helps you decide whether that gap repeats often enough to act on. Here is how the five approaches hold up.
5. Score-only dashboards: fast chart, no fix
This tier is for the buyer who needs a screenshot for a monthly deck. Its advantage is speed: connect a domain, run a fixed prompt set, and get a blended visibility score and line chart by morning. If the job is reporting that number, it does the job.
What rules it out is what the score hides. With 20 prompts, a 20% score carries a 95% confidence interval of roughly 2.5% to 37.5%, and reliably detecting a 10-point move takes about 290 prompts per period. Dashboards in this tier commonly track 15 to 50 prompts. An uptick in that little sample is not a publishing plan.
The blend also masks where citations come from. One analysis of 680M citations found Wikipedia in 47.9% of ChatGPT top-10 sources, Reddit in 46.7% for Perplexity, and Reddit and YouTube prominent in AI Overviews. Average those different citation patterns into one line and you lose the clue about what kind of page might help. You may know the score fell. You still do not know which prompt you lost or who took the citation.
My verdict: buy this if a quick chart is the entire assignment. Skip it if you need to decide what to publish next.
4. SEO suite AI add-ons: convenient, if you already pay for the suite
These are the AI visibility tabs inside the SEO platform your team already uses. They are for a team that wants mentions beside its existing keywords, backlinks and content data, without adding another login. Convenience is the one thing they do better. When the suite is already part of the workflow, that matters.
The rule-out is prompt depth and engine coverage at the entry price. One October 2026 comparison lists Semrush AI Visibility Toolkit at $99 a month for one domain and 25 prompts, with $60 per extra 50 prompts, and tracking for ChatGPT and AI Mode. It lists Ahrefs Brand Radar custom prompts from $50 a month. Check the coverage against where your buyers ask questions. A tab that misses the engines they use is not coverage just because it sits in a familiar product.
I used to tell clients to turn on the add-on and call it done. I was wrong. Twenty-five prompts leave little room for category, problem, comparison and brand questions, especially once you keep branded prompts separate so they do not pull the score toward 100%. You can still use that set as a directional sample. You cannot treat it as a map of every buyer question worth answering.
My verdict: keep the add-on if you already live in the suite and want a trend for 20-odd prompts. Do not buy a full SEO suite for this tab alone.
3. DIY prompt sampling: the control group I trust
Nobody wants to hear this, but a spreadsheet you run yourself beats many paid dashboards for the first month. It is for the owner who can make time for repeated checks and wants to learn what a useful report should contain before paying for one.
Start with 20 to 50 real buyer prompts, grouped by category, problem, comparison and brand. Pull the language from sales calls, support tickets, Reddit and People Also Ask. Run the same questions across ChatGPT, Perplexity, AI Overviews or AI Mode, Gemini, Claude and Copilot. Log the prompt, engine, date, mention, citation, position, competitors and sources each time. Run each prompt three to five times while logged out, then report an appearance rate, such as six mentions in ten runs, rather than a yes or no.
What DIY does better is prompt honesty. The questions come from buyers, not from an auto-generated list built to make a dashboard look busy. You can also open the cited pages yourself and ask whether your site answers the same question. That takes more judgment than reading a score, which is precisely why it helps.
Repetition rules it out at scale. Manual checks need at least weekly reruns to catch shifts; scheduled platforms are built for ongoing monitoring. The sheet works only if someone keeps running it and checking the pages behind the citations. A beautifully categorized spreadsheet that stopped updating three weeks ago is another screenshot with better columns.
Run the 25-prompt spreadsheet workflow for 30 days as a baseline if you can own the chore. If you cannot, buy automation rather than letting the sheet rot.
2. Dedicated prompt trackers: evidence, but not execution
Standalone trackers are for teams that can supply buyer prompts, review the misses and publish the fixes themselves. They submit prompts on a schedule, parse the answers and store citations. Prompt-level evidence is what they do better: you can see the cited URL, the competitor that appeared instead and a trend by prompt and engine instead of one blended percentage.
That makes this the first paid tier I would consider for the one-week test below. The entry costs vary: the cited comparison lists $29 a month for 15 prompts at Otterly.AI, $300 a month for 350 prompts at Scrunch and $295 a month for starter credits at AthenaHQ. Compare the price with the buyer prompts you can monitor and the fixes your team can ship. A lower monthly fee is not cheaper per useful insight if the prompt set misses your buyers.
Before paying, I would ask for six things:
- Engine coverage that matches where your buyers ask questions.
- The ability to supply your own prompts, not just accept generated ones.
- Real-interface collection rather than API-only pulls.
- Exact cited domains and URLs.
- Competitor share of voice.
- Scheduled reruns and exports.
Treat the absolute score as directional. Buy the tool for the pattern: which prompts you lose, who wins them, and whether those losses recur across a 14- to 28-day window. Then inspect the winning pages against your own. The tracker can put the evidence on your desk; it cannot make your publishing queue shorter.
My verdict: pick a dedicated tracker if someone in-house will turn losing prompts into published pages every week. Without that owner, you rent the insight and keep the gap.
1. Measurement tied to execution: my pick for most businesses
This is for the team that already has more content gaps than it can close. The approach connects monitoring to the people doing the work: a repeated loss on an unbranded comparison prompt points to a cited competitor URL; a check of your site reveals the missing answer page; the team publishes that page. The advantage is that the finding and the fix live in one workflow.
That is the loop groas offers. It brings together tracked prompts, AI answers and citations, share of voice and referral checks with new pages and technical fixes, across ChatGPT, Perplexity, Gemini, Claude, DeepSeek, Grok, Google AI Overviews and Google search. Its SEO and AI search plan is $1,499 a month, flat, with a 7-day money-back guarantee. The target does not tell you which page to write. The prompt and citation work is how the team gets there.
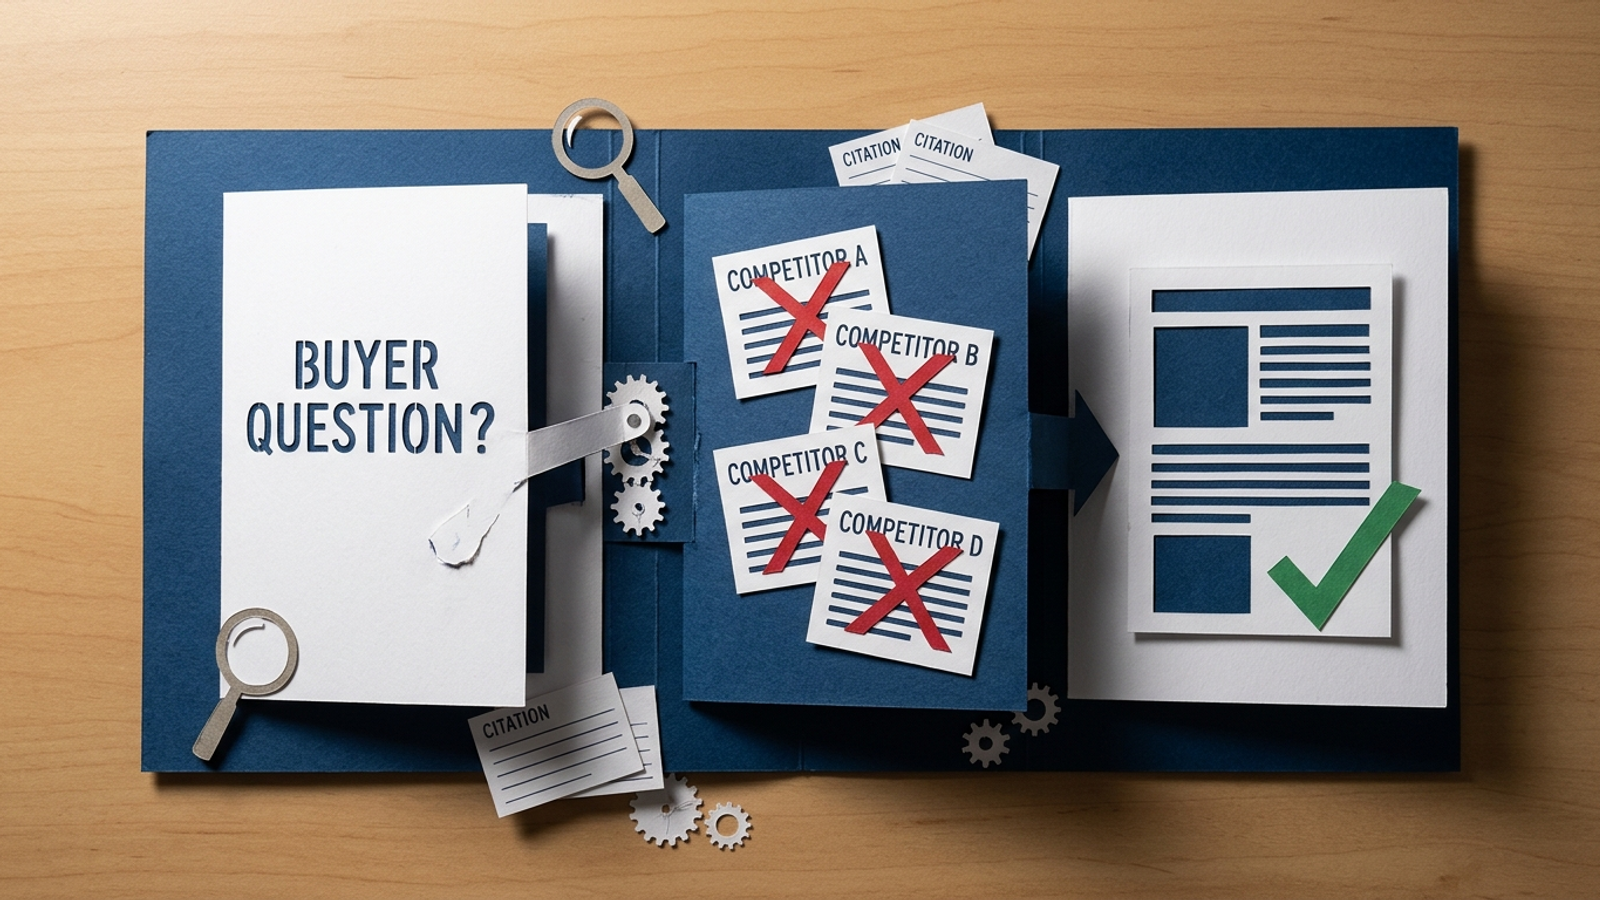
A monitoring tool can tell your marketer what is missing. This model takes on the page and the fetch and structure fixes around it, then reports where you were named, what moved and why. For a business stuck between knowing the problem and shipping a response, that handoff is the point. It is also why this ranks above a tracker, even one with a cleaner dashboard.
There is a clear rule-out. If compliance requires you to keep every content decision in-house, or you only watch a handful of brand prompts, you would be paying for execution you cannot use. Do not buy a publishing workflow to admire its monitoring screen. Pick groas when lost prompts outnumber the pages your team can ship.
I left one popular option out of the ranking: free one-off graders. Tools such as Geoptie or Sellm offer a baseline grade, and a baseline is what they are built to give you. There is no schedule, trend or competitor gap to assess alongside the five approaches above. Run one for a free screenshot if you want. Do not mistake it for monitoring.
| Approach | Who it is for | What it does better | What rules it out | Cost signal |
|---|---|---|---|---|
| 5. Score-only dashboard | Buyer who needs a chart | Fast setup | Blended score hides prompts and citations | Low fee, noisy sample |
| 4. SEO suite add-on | Team already paying for the suite | Mentions beside SEO data | Limited prompts or engine coverage at entry price | Cited options start at $50–$99/month |
| 3. DIY spreadsheet | Owner who can rerun checks weekly | Real buyer prompts | Repetition takes time | Labor rather than a subscription |
| 2. Dedicated prompt tracker | Team with an in-house publisher | Prompt-level citation evidence | The fix still needs an owner | Cited plans span $29–$300/month |
| 1. Tracking tied to execution | Team that cannot ship fixes fast enough | Miss becomes a published page | Execution is wasted if content must stay in-house | 90-day visibility target |
Who should skip my top pick
Skip the done-for-you approach if you already publish two answer pages a week without chasing, if legal must approve every paragraph before it goes live, or if you only care about five brand prompts where you already appear. Those are reasons to keep the writing in-house. A dedicated tracker can still show your team where it loses citations, but your team must inspect the gap, make the page and keep up the pace.
Everyone else runs into the bottleneck I watched for years in paid search: the account knew the losing query on Monday, and the ad did not change until Friday. Knowing what to fix feels productive. Until somebody makes the change, it is just a better-organized backlog.
The one-week test to run before you pay
You do not need a polished score to test a vendor. You need a small, fixed set of questions and a way to trace each miss back to a page. Ask for evidence you could turn into a publishing decision.
- Take 25 prompts from real buyer language. Group them by category, problem, comparison and brand, then freeze the set for the week.
- Add two or three competitors so you can watch for engine-wide shifts rather than interpreting every change as yours alone.
- Run the prompts daily for seven days across ChatGPT, Perplexity, Gemini and AI Overviews. Record appearance rate by prompt and engine, not one blended percentage. Keep branded prompts in a separate tab.
- For each repeated miss, record the cited competitor URL and check your site for the answer page that might be missing. Do not call it a content gap until you have looked.
- Cross-check the picture with GA4 AI referrals, server logs for GPTBot and PerplexityBot hits, branded search and direct traffic. None replaces the prompt record; together they keep you from making a big decision on one visibility wobble.
That is the spreadsheet, script or tracker test I want a vendor to pass. At the end of the week, ask it to name three losing prompts, the URL that beat you on each and the missing page that explains each loss. If it cannot, do not sign because its headline score looks tidy.
A prompt-level tracker passes if someone in-house will write the fixes. Measurement tied to execution passes without that condition because the work moves into the same monthly plan. For the reader who skipped to the end, my pick is groas when your team cannot keep up with the gaps: buy the system that turns a lost prompt into a published page. Everything else is an impressions chart with better fonts.