

 LinkedIn
ChatGPT-User fetched our pages 1,777 times in 30 days while building live answers. The pages it wanted were a Google Ads changelog and pages about our business. That is the interesting part: people are researching tactics and vendors inside ChatGPT, before they necessarily search for either.
Those verified fetches do not tell me how many people asked, whether any bought, or what an ad beside those conversations would earn. They do tell me where to start testing ChatGPT ads: in a B2B research budget, not an impulse-buy budget. I used to tell clients to wait for proof of intent before testing a new ad surface. Here, the research activity showed up in our logs before I had an ad result to point to.
The log finding: which pages ChatGPT pulled
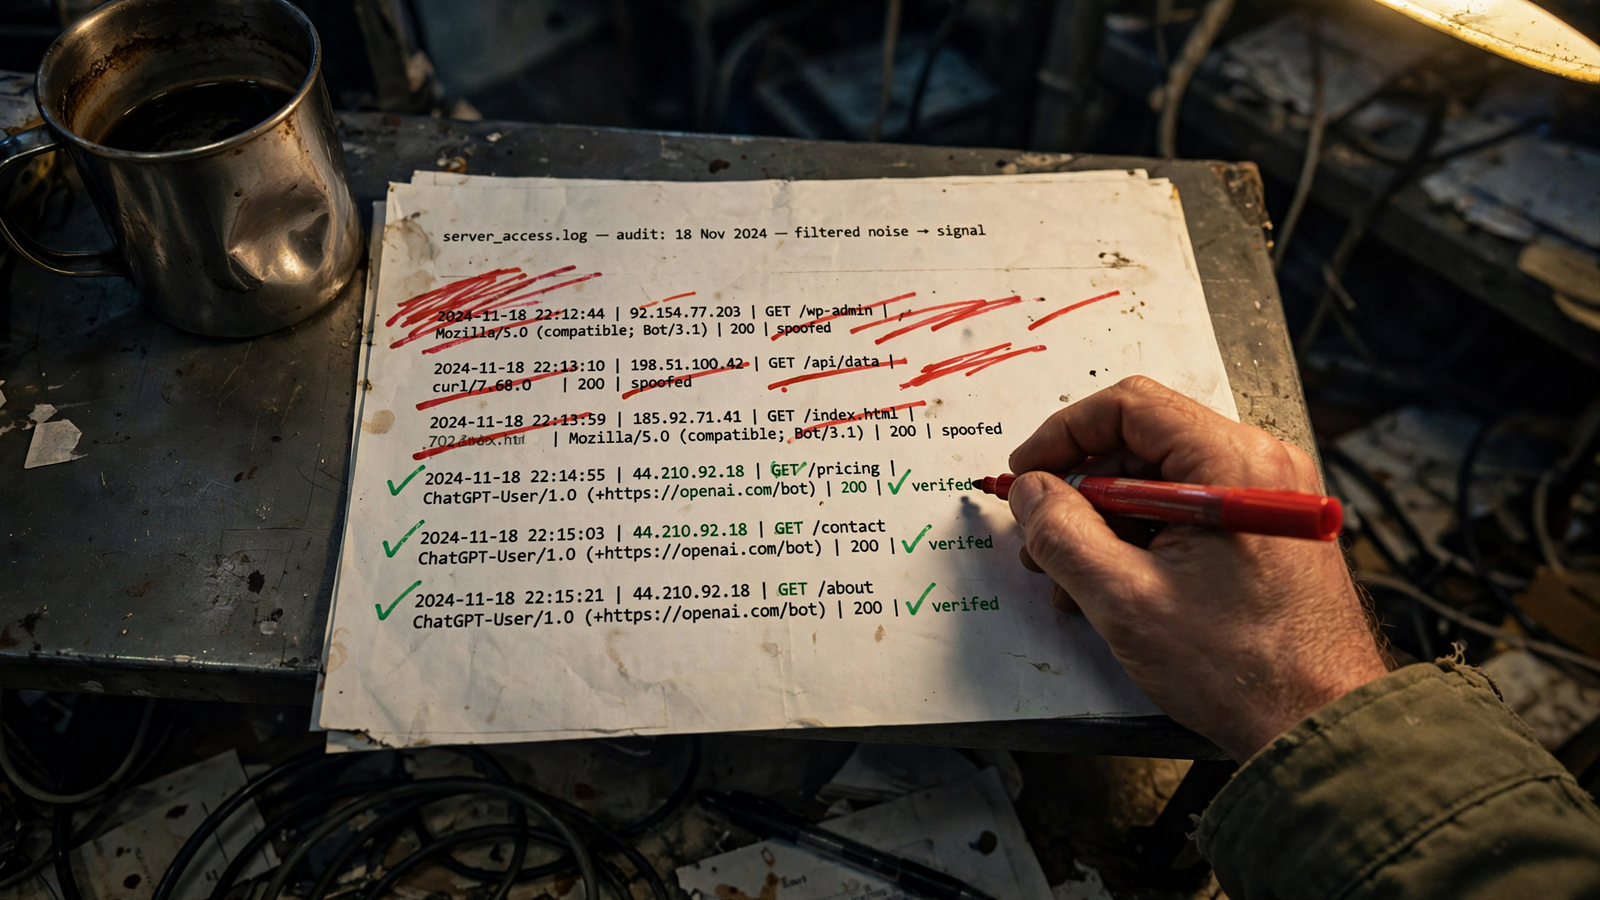
First, the bot distinction matters. GPTBot crawls for model training; ChatGPT-User fetches pages in response to user activity. I do not count a request just because its user-agent says ChatGPT-User. Anyone can copy that string. I check its IP against OpenAI’s published ChatGPT-User ranges; requests that fail that check stay out of the verified count. The IP-checking explanation and published range count describe why that filter matters.
Here is the page-by-page breakdown from our edge logs, condensed to the signals relevant to an ad decision:
| Signal over 30 days | What appeared in the logs | What I take from it |
|---|---|---|
| Verified ChatGPT-User fetches | 1,777 | Our pages were being retrieved during live ChatGPT activity. |
| Fetches of our Google Ads changelog | 577 | A substantial share involved a page about tactic changes. |
| Fetches of our homepage and for-businesses page | Hundreds combined | Pages about the vendor, not just the tactic, were also retrieved. |
| Hits claiming AI bot identities but failing verification | A majority of raw hits | An unfiltered bot total would overstate the signal. |
A fetch is a request, not a distinct person or a verbatim record of a prompt. I cannot read a request for the changelog and quote the question that caused it. But page choice still tells me something useful. A changelog is a place to check what changed and what still works. A homepage and a for-businesses page are places to check who offers the work. Together, those pages look much more like homework and vendor evaluation than a rush to checkout.
The mix also matters more than a single aggregate called AI bot traffic. Claude-User barely registered on those same commercial pages in this sample. That does not make a universal claim about Claude’s audience. It tells me which assistant was retrieving our commercial pages during this period. If I were choosing where to investigate a research-stage opportunity for this business, I would start with the fetcher I can see.
The requests were not a steady drip, either. ChatGPT-User fetches can arrive in bursts as pages become relevant to current questions. Treating every burst as a scheduled crawl misses the mechanism. So does looking for the fetch count in GA4: bot requests are excluded there; human visits are a separate measurement. Our edge logs measure retrieval. Analytics measures what a person does if they click through. Do not put those counts in the same conversion-rate calculation.
The limit: fetches cannot forecast ad returns
The cleanest conclusion is also the narrowest one. Our logs show verified ChatGPT-User requests for pages about Google Ads and our business. They do not show the prompt text, a click on an ad, a qualified lead, or closed-won revenue. They cannot tell me what a paid placement would have cost in those conversations. Public CPC, conversion-rate, and auction benchmarks are too thin to turn these fetches into a reliable ROAS forecast. Anyone multiplying 1,777 by an assumed purchase rate is decorating a guess with a log file.
The early performance figures offer direction, not a forecast for our account:
| Reported comparison | ChatGPT ads | Google Search | How to use it |
|---|---|---|---|
| US ad click-through rate | About 0.73% | 6.64% median | Expect a different response pattern; do not assume search CTR. |
| Conversion in a same-advertiser test of about 1,500 users | 0.21% | 3.71% | Treat as an early comparison, not a predicted result. |
The conversion test used different denominators, and neither comparison prices the value of a later deal. Our log sample has its own limit: one B2B search vendor site. Your changelog may not draw the same retrieval pattern; your vendor pages may draw a different one. I would use our 1,777 fetches to justify looking at the channel, then use your own paid test to judge its value.
Why this looks like research, not checkout
The page mix is the strongest part of the argument. Our changelog drew 577 verified fetches; the homepage and for-businesses page drew hundreds combined. A buyer checking a tactic and then considering who can handle it is doing the kind of work that precedes a B2B shortlist. The logs do not prove that those requests came from the same buyer or the same conversation. They show that both kinds of page were in demand.
That interpretation is consistent with the reported B2B software research figures: 51% of buyers begin research in an AI chatbot rather than Google, up from 29% a year earlier, and 95% of purchases go to a vendor already on the initial shortlist. Those figures describe a broader buying process, not the people in our logs. They help explain why retrieval of vendor pages is worth noticing. If the shortlist forms early, being considered early matters.
The intent distinction is familiar to anyone who has managed search accounts. Someone asking a conversational question such as what CRM fits a 20-person team is still defining the choice. Someone searching buy CRM is closer to acting on it. ChatGPT fits the first moment better; Google still has the keyword intent that catches the second. The same analysis places ChatGPT around top- and middle-funnel research, with B2B SaaS, professional services, enterprise software, and other high-consideration purchases among the clearer fits.
That is not a reason to move a closing budget wholesale into chat. It is a reason to test whether chat contributes to the shortlist that your search campaigns later convert. If you sell through demos, proposals, or a buying committee, I would examine that path. If your business depends on an immediate add-to-cart, I would keep the money on search and shopping until your own evidence says otherwise. Match the test to the buying step the channel appears to serve.
There is an audience constraint, too. ChatGPT ads serve Free and Go tiers, not Plus, Pro, Business, Enterprise, or Education. Targeting relies on plain-language context hints rather than keywords or demographics, with a relevance-weighted second-price auction; conversations remain private and ads do not influence answers. The person doing early homework may be on an eligible account. The economic buyer on a corporate seat may not be. That does not invalidate the research-stage test, but it belongs in the budget discussion before anyone projects reach across an entire buying committee.
Measure the assist before calling the test a failure
If ChatGPT introduces a vendor during research, the eventual demo request may arrive another way. A buyer might click a citation, return through branded search, join a webinar, and request a demo later. That sequence is a measurement problem, not evidence that the first encounter did nothing. I learned this managing B2B SaaS accounts where a form fill was not the sale. We had to move the conversion signal from raw leads toward pipeline stages before Smart Bidding had something worth learning from; I covered that shift in this pipeline-signal account.
For a ChatGPT ads test, I would set up the measurement before spending:
- Separate paid visits from organic citations. Put deliberate campaign UTMs on every ChatGPT ad, including
utm_source,utm_medium=paid_chatgpt, and a campaign name. Compare those tagged visits with organic visits identified by their available referrer or tracking data. Do not assume an untagged citation click is a paid click. - Compare attribution views. Look at first-touch, last-touch, and multi-touch reporting rather than asking same-session conversion to explain a long sale. A 90-day window, longer for enterprise, and an early check for brand-search lift over two to four weeks give the research-stage hypothesis a fairer reading.
- Tie the result to pipeline. Watch qualified stages and later revenue alongside visits and branded search. A click is not pipeline; a branded-search rise alone is not proof that an ad caused it. Look for the pattern across the measures you already trust.
That paid-versus-organic split is easy to neglect. Only human clicks, not bot fetches, can appear in visit reporting, and attribution depends on the tracking information available. Without distinct paid UTMs, a paid research assist can disappear into an organic or unattributed bucket. Organic then looks brilliant, paid looks useless, and the budget meeting reaches the wrong conclusion. Tag first. Argue about credit later.
Keep Google and Bing running while you test ChatGPT
Google and Bing catch buyers who know what to type. ChatGPT may catch them while they are still describing the problem. I would not pause the former to fund the latter; that would starve the part of the funnel most likely to close the demand you are trying to develop. Run ChatGPT Ads beside search, with one budget owner and a shared view of pipeline. groas covers Google, Bing, and ChatGPT Search Ads under one flat fee, rather than asking a business to manage three separate retainers.
The rollout and pricing details make a contained test possible, but they do not make an outcome certain:
| Test input | Reported figure | What it changes |
|---|---|---|
| US minimum | $25 per day | Provides a small starting point. |
| US pricing frame | $25–$45 CPM by topic, or $3–$5 starting CPC bids | Gives you options for controlling how you pay while learning. |
| Pilot and access | US pilot in February 2026; US self-serve in May 2026 | Explains why the performance history remains young. |
| Later rollout | 89 countries after the October 21, 2026 expansion | Broadens access, not the evidence for your account. |
I would start with CPC while learning which contexts bring relevant visits, because it charges for clicks rather than impressions. Cap the experiment at 5–10% of search spend: on a $20,000-per-month search account, that is roughly $1,000–$2,000. Set a hard spend limit and require human sign-off to scale. Then review leading signals at 60 days without pretending a 90-day pipeline window has finished. If the early signals are poor, stop. If they are promising, let the agreed attribution window run before declaring a pipeline result. A kill date is useful; moving the goalposts after launch is not.
The budget decision the logs support
For B2B SaaS or professional services with a sale longer than a week, I would give ChatGPT ads 5–10% of the search budget as a capped research-stage test. I would not take that money from the Google and Bing campaigns catching buyers ready to act. Our verified fetches show demand for tactic and vendor pages inside live ChatGPT activity; they do not establish paid ROAS. That is precisely why the next step is a measured test rather than a forecast dressed up as certainty.
Pull your own edge logs for a month. Verify ChatGPT-User by IP and count fetches by page, not by an unfiltered bot label. Tag paid visits separately from organic citation traffic. Keep search running, measure pipeline stages, and decide in advance what an early stop and a later scale decision require. If the pattern reaches qualified pipeline, increase the budget with a human approving the move. If it does not, keep the spend cap and learn where your buyers actually shortlist.
One operational footnote: do not block ChatGPT-User while trying to test visibility in ChatGPT. The OpenAI crawlers serve different purposes, and a blanket robots.txt block can also remove ChatGPT Shopping visibility. Let verified live-answer fetches through and filter spoofed hits at the edge. Otherwise you may shut out the research activity that made this test worth running.