

 LinkedIn
Most advice about which AI engine to fix first is a guess dressed up as a priority list. I wrote an earlier starting point in ChatGPT vs Perplexity vs Google AI Overviews: Which Citation Path Should You Fix First?. We are taking a second look because the right starting point depends on how each engine already treats your site, and that varies from one business to the next.
This time, run a test. Ask the same buyer questions in three engines on a schedule, record the answers and check them against your own server logs. Make one fix, then ask again. After 30 days, the priority should come from your numbers rather than my ranking.
Question: which engine shows you, cites you or fetches you?
For a fixed set of buyer prompts, how often does your brand appear in ChatGPT, Perplexity and Google AI Overviews? When does your page appear as a source, and which engines fetch pages from your site?
Keep the events separate. A mention is not a citation, and a citation is not necessarily a clickable link. A mention puts your name in the answer. A citation identifies your page as a source. A link gives the reader a route to it. Your log files answer a different question: whether a bot requested a page. A fetch alone does not tell you that the page appeared in an answer.
My expectation is that your results will not line up neatly across the three engines. One may fetch pages it rarely cites; another may show your brand on prompts where its bot barely appears in your logs. That mismatch is useful. It tells you whether to investigate access, the pages being selected or the answer the buyer actually sees. It also makes a general ranking a poor substitute for a baseline.
The limit matters, too. This is a controlled sample, not a count of your total AI exposure. Engines do not give you full impression data, and Google Search Console and GA4 cannot isolate AI Overview traffic in the way this test needs. Your sheet will measure the prompts you chose under the conditions you kept steady. Do not sell it to yourself as every answer every buyer saw.
Setup: write 20 prompts a buyer might actually use
Start with 20 questions from sales call notes, support tickets and Search Console queries. Do not turn category-page headlines into questions and call that buyer research. I used to write these from what I thought buyers should ask. I was wrong. Use the language someone types when they need a price, a comparison, a local option or a fix for a specific problem.
Split the set into three rough groups so you can interpret the answers later:
- Category questions: Which type of product or service fits a stated need?
- Comparison questions: How does one option stack up against another for that need?
- Problem questions: What is going wrong, what might fix it and what might it cost?
Practitioners using a manual citation-tracking method work with 20 to 50 buyer questions, run them weekly and log whether an Overview triggered and who got cited. For this test, keep the core 20 unchanged through the retest. If you quietly improve the prompts in week four, you have changed the instrument along with the site.
Set the controls before your first run. Use fresh temporary chats, stay logged out where you can, keep location and language settings fixed, and use the same prompt wording on the same day across ChatGPT with browsing on, Perplexity and Google. For Google, record an absent AI Overview as an absent Overview. Do not swap in a different question until one appears.
Why repeat the prompts? Identical questions do not reliably produce identical answers. In one check, repeated ChatGPT prompts shared only about 23% of businesses named. Another teardown found that the same short prompt, run minutes apart, shared zero exact retrieval queries; it retrieved 14 URLs on one run and 40 on another. One screenshot is an observation, not your visibility score.
Make the sheet one row per prompt, per engine, per run. Include:
- Prompt, prompt group, date, engine and repeat number.
- Whether the answer mentions your brand, cites your page or links to it.
- The exact URL shown, every competitor cited and the total citations shown.
- A screenshot or saved answer so you can check the row later.
- For Google, whether an AI Overview triggered at all.
Keep mentions, citations and links in separate columns. If a result looks odd next month, you should be able to reopen the evidence rather than debate what someone remembers seeing. Above all, log the URL. A tick beside ‘cited’ will not tell you which page needs work.
Measure 1: record the answer, not the screenshot you liked
Run each of the 20 prompts five times per engine in fresh sessions. Log every answer, including the ones where you are absent. That gives you 100 attempts per engine in a testing round, although Google will not necessarily show an Overview on all 100. Do not compare its Overview-only citations with 100 ChatGPT answers without naming the different denominators.
For each engine, calculate mention rate as answers naming you divided by answers tested. Track citation rate separately using answers that cite your page divided by answers tested. For Google, also calculate citations among the answers where an Overview actually triggered. Put both numbers beside the trigger count; otherwise a respectable citation rate inside four Overviews can hide the fact that most of your tested queries never produced one.
Then read the URLs, not just the percentages. A homepage citation on a brand question does not tell you whether a relevant page appears on a comparison question. Your sheet might show the same guides repeatedly while another page never appears. That pattern gives you a place to investigate during the change window. Rewriting the whole site would give you less information.
Expect movement between repeats. In the retrieval teardown, 34 of 40 pages fetched in one run were not cited. Retrieval and citation are different decisions. If your brand appears once in five runs for a prompt, note it, but do not build a month of work around it. If it appears four or five times under the same controls, you have a pattern worth testing again.
Measure 2: check which pages the bots request
Answers show what you observed as a reader. Server or CDN logs show requests to your site. Pull the 30 days before you start and filter for ChatGPT-User, OAI-SearchBot, GPTBot, PerplexityBot and Perplexity-User. Save the period and the filter you used so the later pull is comparable. Sort by bot and URL before you decide which page to edit.
Do not lump those user agents together. OpenAI documents separate controls for its bots: OAI-SearchBot is for surfacing sites in ChatGPT search, GPTBot is for training, and ChatGPT-User handles user-triggered fetches. Search access and training access are different choices. Perplexity also distinguishes PerplexityBot, which surfaces and links sites in results, from Perplexity-User, which fetches for a user question and generally ignores robots.txt.
Check your robots.txt rules against the bot relevant to the path you are testing. Blocking GPTBot does not, by itself, tell you what you allowed OAI-SearchBot to do. Equally, a bot request does not prove that your page was used in a visible answer. Treat the logs as evidence of requests, then compare them with your answer rows. A page requested often but never cited calls for a different investigation from a page the relevant bot does not request at all.
For the post-change comparison, use matching windows and report the window beside the count. If your baseline is a full 30 days and your retest is one week, raw fetch totals will mainly tell you that one period lasted longer. Keep the earlier 30-day pull for context; use comparable slices to judge the change.
Measure 3: treat AI Overviews as their own condition
You cannot isolate an AI Overview with a separate fetcher count in these logs, so measure that part of the test from the answer side. For every Google run, record whether an Overview appears. When it does, expand it, capture every cited source and save the expanded screenshot. Keep region and language fixed. Use an incognito window and clear cookies between queries.
The manual logging approach separates ‘AI Triggered’, ‘Our Brand Cited’, ‘Competitor Cited’ and ‘Total Citations’. Do the same. Count link cards in the citation column, not plain-text brand mentions. A text mention may be worth recording, but it is not the same event as a source the reader can inspect.
Read trigger rate alongside citation rate. Suppose four of your 20 prompts trigger an Overview and you appear in one. That is one citation among four triggered prompts, but only one across the full prompt set. Neither number is wrong; each answers a different question. Preserve both before you choose a fix.
The 30-day schedule: baseline, one change, retest
A protocol is only useful if you can tell what changed. Put these dates in the sheet before anyone edits a page.
- Week 1 — baseline. Run all 20 prompts in all three engines, five repeats each. Pull and save the preceding 30 days of bot logs. Record your settings and take your screenshots. Make no site changes during the answer-side baseline.
- Weeks 2 and 3 — one fix. Pick a single change that follows from the baseline. If the relevant search bot is blocked, review that rule. If a fetched page is repeatedly passed over, consider a concise answer passage with the date and number the question needs, or update stale specifications. Record the page, the exact change and the date it went live. Do not also publish a batch of new pages and rewrite every comparison page.
- Week 4 — retest. Run the same prompts, in the same engines, with the same repeat count and controls. Pull the new logs. Compare answer rates from the two testing rounds, then compare bot requests over matched log windows. Note if the change was not live for all of a log window rather than treating every request in it as post-fix.
You will still have uncertainty. Engines vary, buyers vary and a month is short. But one documented change beats five simultaneous ‘optimizations’ when the point is to learn which action moved an observable number.
Read the result without turning variance into a victory
Small samples lie with confidence. One appearance in five runs is a 20% rate for that prompt, but it is also one appearance. I treat one of five as a reason to keep watching, two or three as an emerging pattern, and four or five as something to retest. Across the full set, show the counts behind every percentage. That is more honest than the single-run scores in the sort of visibility reports I have pushed back on before.
The same restraint applies after your fix. If citation rate moves from 10% to 15% on the same prompts, do not declare a win; look at the individual rows and repeat next month. A move from 10% to 45% deserves attention, but first check that the settings, trigger counts and scoring rules stayed the same. Your control sheet should make that check boring. Boring is good here.
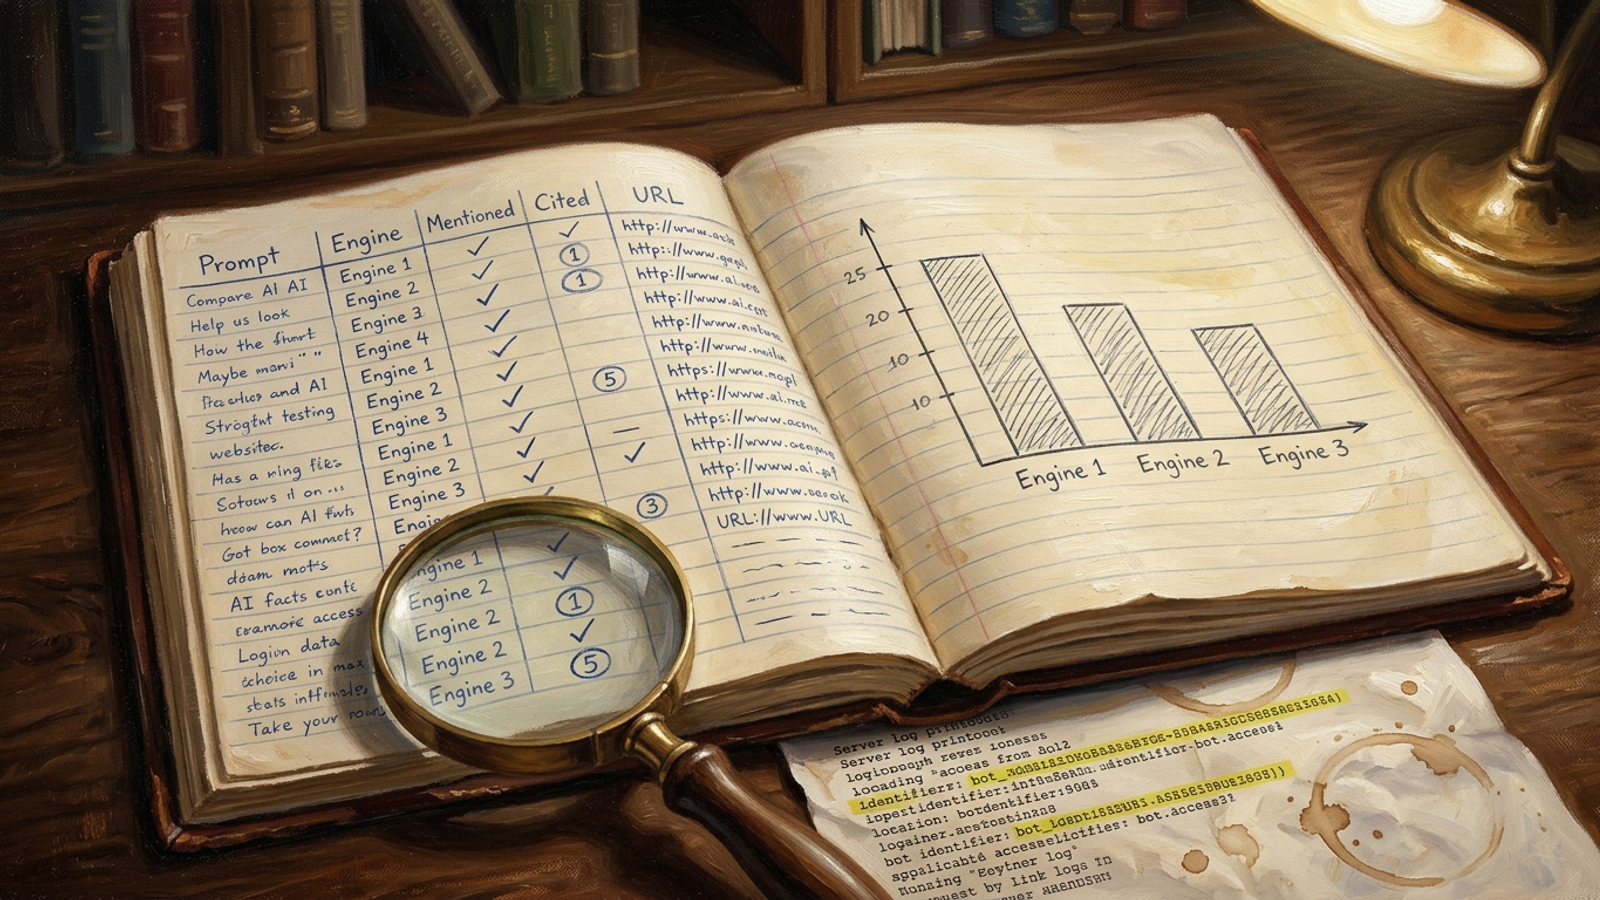
Read answer and log results as a pair. If requests rise while citations stay flat, the bot reached the site but your page still did not appear as a source in this sample. Inspect the questions and pages being selected before changing access rules again. If citations appear while requests in your chosen window stay flat, do not claim a fresh fetch caused them. Record the mismatch and keep measuring.
For a simple engine-level score, count the prompts that cite you in at least three of five repeats and divide by 20. Keep the underlying answer-level rate beside it: the prompt score shows breadth; the answer-level rate shows how often citations appeared. For Overviews, you can also report AI Share of Voice as brand citations divided by Overviews triggered, using the same counting rule each month. Label every denominator. ‘25%’ without one belongs on a sales slide, not in this notebook.
Choose the next fix from the evidence
Now choose a priority rather than inheriting one. Start where your baseline shows a plausible opening and your sheet names a specific obstacle: a relevant page gets requested but not cited, a comparison prompt repeatedly names competitors instead of you, or a search bot cannot reach the page you intend it to use. An engine with no mentions and almost no relevant requests may need an access check, but do not spend the next month polishing its copy on instinct alone.
That is a more useful decision than ‘work on ChatGPT first’ or ‘AI Overviews first’. Once you have picked the engine, the engine-by-engine comparison can help you decide where to work. Use the part that fits your observed problem. One engine, one fix, one retest.
Repeat monthly, or admit the result did not hold
Keep the same 20 core prompts and controls next month. Add dated rows rather than replacing your old results, so you can see whether a change lasts. If buyers start asking something new, add those prompts to a separate set; do not quietly fold them into the original score. Retire a core prompt only with a note explaining why. Otherwise your trend will measure your editing habits as much as your visibility.
If citations rise and hold for two cycles, you have a stronger reason to keep working on that engine. If requests rise but citations do not, access may have improved while selection has not. If neither moves, reconsider the fix or the priority. A flat result is still a result: it tells you not to pay for more of the same work just because a report calls it progress.
That is what this 30-day test changes. It will not reveal every AI answer about your business. It will tell you what happened on questions your buyers ask, whether the relevant bots requested your pages, and whether one focused fix changed the answers in front of you. groas runs answer-side and log-side checks continuously for clients; the sheet version gives you the same discipline by hand. Measure first. Fix second. See if it held.