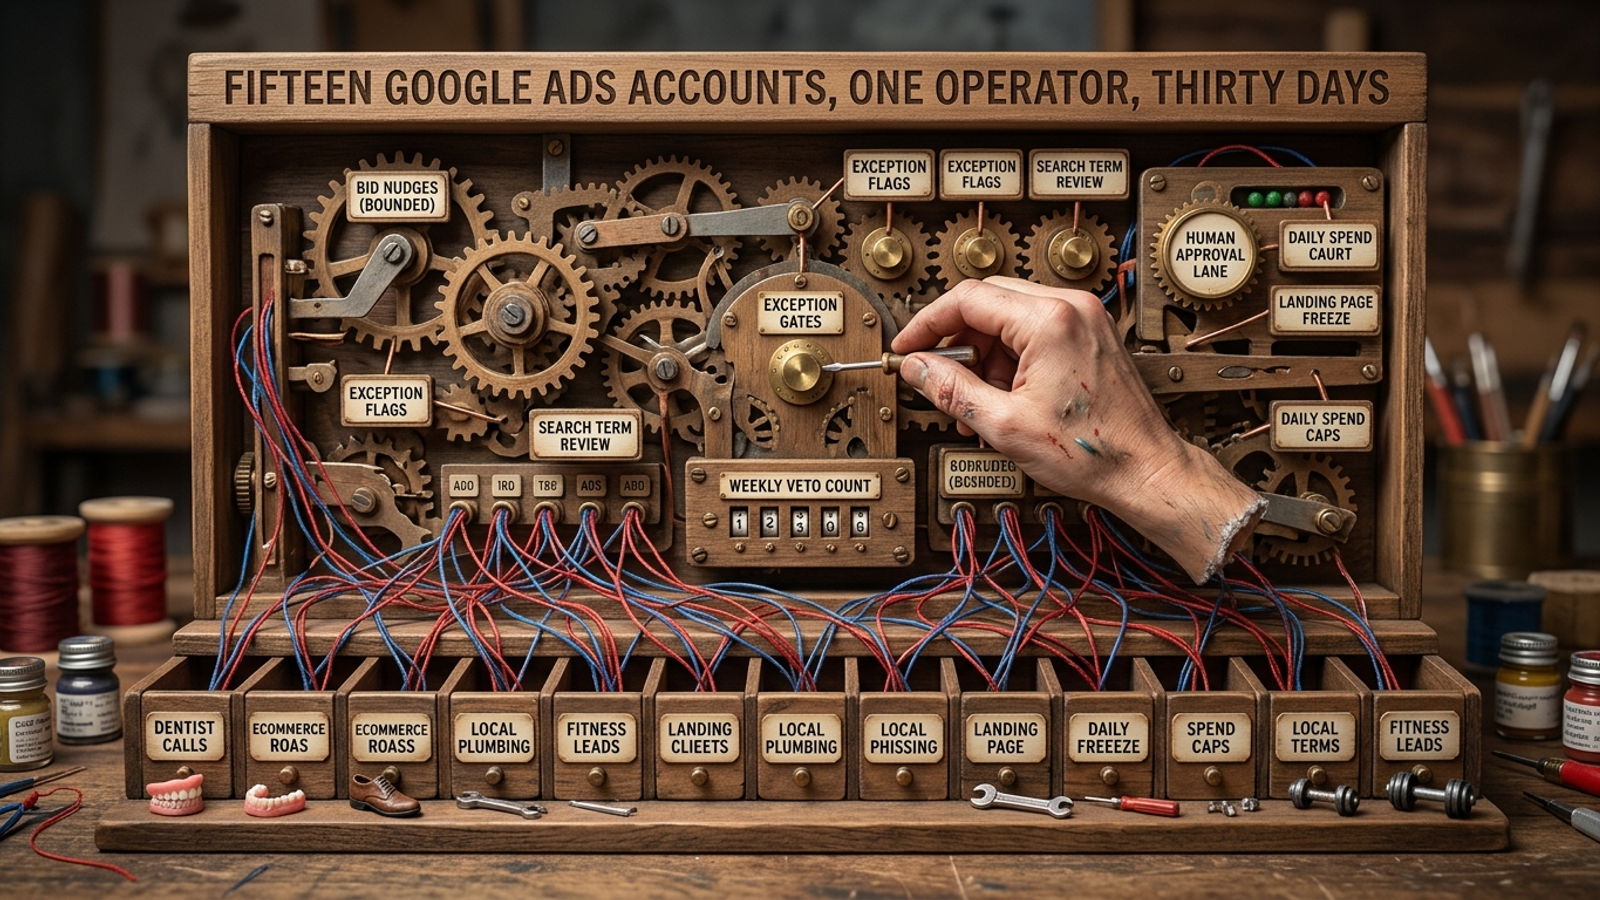
One operator, fifteen client accounts, thirty days, zero new hires. The constraint is the plan: hand off mechanical Google Ads work first, keep judgment calls behind an approval gate, and widen that gate only when the change log shows the machine has done nothing you would have vetoed.
Most agencies trying to scale across 10+ clients do it backwards. They buy a tool, connect every account on day one, then spend the next month explaining why CPA moved. I used to tell clients tighter account control meant better performance. I was wrong. Control was never the bottleneck. Attention was. The answer is not another junior media buyer or a faster way to open fifteen tabs. It is a handoff you can inspect, stop, and defend to a client.
1. Week 1: spend eight hours buying a baseline
Cost: roughly 30 minutes per account, or about eight hours across fifteen. What it buys: a written account of performance before automation touches anything. I pull the last 90 days of change history, current CPA or ROAS by campaign, and one sentence per client on what “good” means in their words. One dentist wants emergency calls under $85. One ecommerce brand wants 3.2 ROAS after returns. Those are different instructions, even if both clients ask for “better performance.”
Put the baseline somewhere you can open while a client is on the phone. A number buried in an export is not much use when someone asks whether the new setup caused last week’s dip. Record what each account optimizes toward, which campaigns carry the result, and what changed recently enough to complicate a comparison. Do not turn this into a strategy workshop. Thirty minutes is enough to write down the starting line; it is not enough to redesign the account, and that is the point.
This week cuts bid changes, budget shifts, and new negatives. You are documenting, not optimizing. At fifteen accounts, the temptation is to fix an obvious nuisance while you are already looking at it. Resist it. If you change the account while building its baseline, you make the next comparison harder to read. Log the nuisance for week 2 instead.
The baseline also gives each client a definition of success you can use later. A lower CPA does not settle much if the client needed qualified calls and the extra conversions were weak forms. Nor does a better blended ROAS explain which campaign did the work. Save the starting numbers and the client’s actual goal before you give automation a job. Skip this week and every later improvement looks like noise; every dip looks like your fault.
2. Week 2: give the machine repeatable work, not discretion
Cost: about 20 minutes per account to set up, followed by exception review rather than routine account browsing. What it buys: time back from the work that repeats whether or not anything interesting happened. Start with search term review, budget pacing, and small bid maintenance inside existing targets. I use exception reports from the MCC manager account so one login can surface problems across the fifteen clients while each client keeps ownership.
The view should tell you where to look: an active campaign with no spend, spend with zero conversions, or CPA swinging 30% week over week. That beats opening fifteen accounts to discover that thirteen need no decision. The machine does the repetitive checking. You handle the exception and its context. A flag is not permission to change the account.
Search terms are the clearest test of that boundary. Do not let automation add every apparently irrelevant query as a negative. A word that looks wasteful alone can belong to a valuable longer query; automatic negative creation can do damage. Have the machine surface candidates, approve them in bulk, and sync only the approved list. You get the review time back without letting a quick pattern match block demand you wanted.
Give bids a narrow lane too. Allow nudges inside a written band, say 10 to 15%, while target changes stay locked. Keep larger budget moves out of the lane: moves above 10–20% can force Smart Bidding to restabilize. The band is not a promise that every nudge is wise. It is a limit on how much can happen before you inspect the log and decide whether the rule deserves to stay.
This week cuts ad copy rewrites, landing page changes, and cross-campaign budget moves. Those decisions need context you have not handed over. The order matters: first prove that repetitive checks and bounded maintenance work as intended; then consider anything that changes the offer, the destination, or the client’s spending plan. If a task repeats weekly and has a clear threshold, hand it off now. If it needs an explanation of why the client changed the offer, it waits.
Checklist: clear these gates before live execution
Run this audit alongside each live account through the first 30 days. Only approved, bounded tasks execute in week 2; the rest stay in review. Allow about 15 minutes per account if week 1 is done. For the account-access setup, I use the multiple-account MCC playbook.
- Primary conversion action matches money: booked call, purchase, or qualified form. Keep secondary actions observe-only.
- Change history and 90-day CPA or ROAS baseline are saved where you can find them in 30 seconds. Do not trust memory.
- MCC admin access is confirmed, the client retains ownership, and billing is flagged per client.
- Brand terms, competitor terms, and negative lists are documented as allow or block for each client. This is where automatic negatives hurt.
- Daily spend caps and bid adjustment bands are written down: 10 to 15% maximum without approval.
- Offer, landing page, and tracking freeze are confirmed with the client for 14 days. No silent page swaps.
- Rollback rule names who pauses automation and when: for example, CPA up 30% for three days. Skip this most often-skipped item and a fluctuation can become a week of overspend with no agreed stop.
3. Week 3: put judgment behind an approval lane
Cost: about an hour a day across all fifteen accounts. What it buys: a check on the changes that can lose a client while the mechanical work continues. Keep offer changes, landing page swaps, and changes to a client’s spending allocation with a human approver. The machine can report what moved. It cannot infer every reason a client suddenly values a different lead or changed what the page promises.
I learned that distinction the unpleasant way when a home services client swapped a landing page without telling me. Quality Score fell for a week while Smart Bidding chased the wrong signal. The cause was human; the effect looked algorithmic. Full automation would have had the same bad information, plus permission to act on it. A change log helps only if you have decided which changes should never reach the log without approval.
So I use an approval lane, not a vague instruction to “use judgment.” Automation proposes; a human disposes of anything that changes what is sold, where traffic lands, or how much a client can spend in a week. Put the proposal next to the client’s baseline and current instruction. If you cannot explain the change against both, do not approve it because a dashboard made it look tidy.
This is also how one operator avoids becoming the bottleneck again. If every bid nudge needs your signature, you have rebuilt manual management with extra notifications. If no consequential change needs your signature, you have stopped managing the account. Decide what needs expert judgment and what can run on thresholds. A mid-level US PPC hire can carry a loaded annual cost of $94,000 to $140,000. Do not hire someone to approve work you could have bounded clearly.
This week cuts automatic approvals for offer, page, and spending-plan changes. Everything already cleared for bounded execution can keep running. If a change needs client context to judge, it waits for you. That is a smaller job than reviewing everything and a more useful one than approving nothing.
4. Week 4: widen the leash only when the log earns it
Cost: about 30 to 60 minutes per client for the week. What it buys: a decision you can defend, account by account, about how much autonomy comes next. Read the action log and ask one question: did it do anything I would have vetoed? Count actions taken and actions you would have reversed, then compare CPA or ROAS with the week 1 baseline. Do not average fifteen accounts into one reassuring answer. The log belongs to each client.
If an account has two straight weeks without a veto-worthy action, widen its band. Bid nudges can move from 15% to 25%; budget pacing can receive overnight permission. If you find even one action you would have stopped, leave the leash short and fix the rule that permitted it. You are not punishing the machine for being a machine. You are checking whether the instruction you gave it matches the decision you would have made.
There is a useful difference between a quiet log and a good one. A quiet log might mean nothing happened. A good log shows what acted, why it acted, and how the result compares with the goal the client gave you. That is why I track the veto count alongside CPA or ROAS. Performance tells me what happened; the veto count tells me whether I am comfortable letting the same rules act again tomorrow. Neither number replaces the other.
The client report can be shorter than most agency reports: one page on what changed, why, what happened to CPA or ROAS, and what happens next. No screenshots of CTR to fill space. On the agency side, groas logs bid, budget, and keyword moves with their reasoning and provides a weekly report under your brand. That supports the operating model here: the engine works inside guardrails while you remain responsible for the client-facing decision. Do not widen access because the account feels calm. Widen it because you checked the actions and found nothing you would have vetoed.
What you cut when a week goes wrong
Skip week 1 and week 4 becomes an argument without a starting number. The client says CPA worsened after automation. You think it stayed flat while ROAS improved on core campaigns. Neither account of events settles the question if you failed to save the baseline. I saw an early version of this in my own account work when a client changed an offer mid-month and blamed the bid changes. Their change caused the problem; my report carried the effect. Without a baseline sheet, I had little to point to. You save about eight hours up front and can spend far more time rebuilding trust afterward.
Skip the week 2 order and hand off judgment before mechanics, and you create the failure everyone will blame on AI. Ad copy can chase search terms the account was not meant to buy. Budget can move toward a campaign without the exclusions or client context that should have constrained it. You have not proved the small, repeatable decisions, yet you have delegated the consequential ones.
Skip week 3 gating and offer changes or page swaps can reach live bidding without an approval lane. If you also skipped the checklist’s rollback rule, there is no agreed threshold for stopping the damage. One loud failure can make you pull automation off the other accounts to fight fires. That is not a scaling plan; it is fifteen places to look when something breaks. Keep the sequence even when an account appears easy.
Day 30: scale the accounts you can prove
Rank the fifteen accounts by evidence. Tier one has clean tracking, stable volume, and two veto-free weeks in the log. Keep those accounts autonomous within their guardrails and send the weekly one-pager. Tier two is stable but thin, with under 20 conversions a month; keep tight bands and review targets monthly. Tier three has broken tracking or a client who changes offers without warning. Do not scale it until the client agrees to a freeze rule and the signal is usable.
Say ten accounts land in tier one, four in tier two, and one in tier three. That is not a verdict on the clients. It tells you where your attention still buys something and where routine checking no longer needs to consume it. It also stops one difficult account from dictating how you manage the other fourteen. The point of the thirty days is not to declare every account autonomous. It is to know which ones have earned more room and which ones still need a hand on the gate.
When the constraint lifts on day 31, do not reflexively hire a junior media buyer to resume the weekly checking you just handed off. Add the next five clients to the same sequence, or sell the capacity you freed as a service line under your own name. I run tier-one delivery through groas for agencies, with the engine inside my guardrails and a weekly log I can forward. The order does not change: mechanical work first, judgment gated, leash widened by proof. Scale the ten you can prove before you touch the five you cannot.