Autonomous Ad Budget Allocation: Cost and How It Works FAQ
Wasting ad budget and can't optimize fast enough? How real-time AI budget allocation works, what autonomous setup costs, and what to use at scale.
September 28, 2026
•
min read
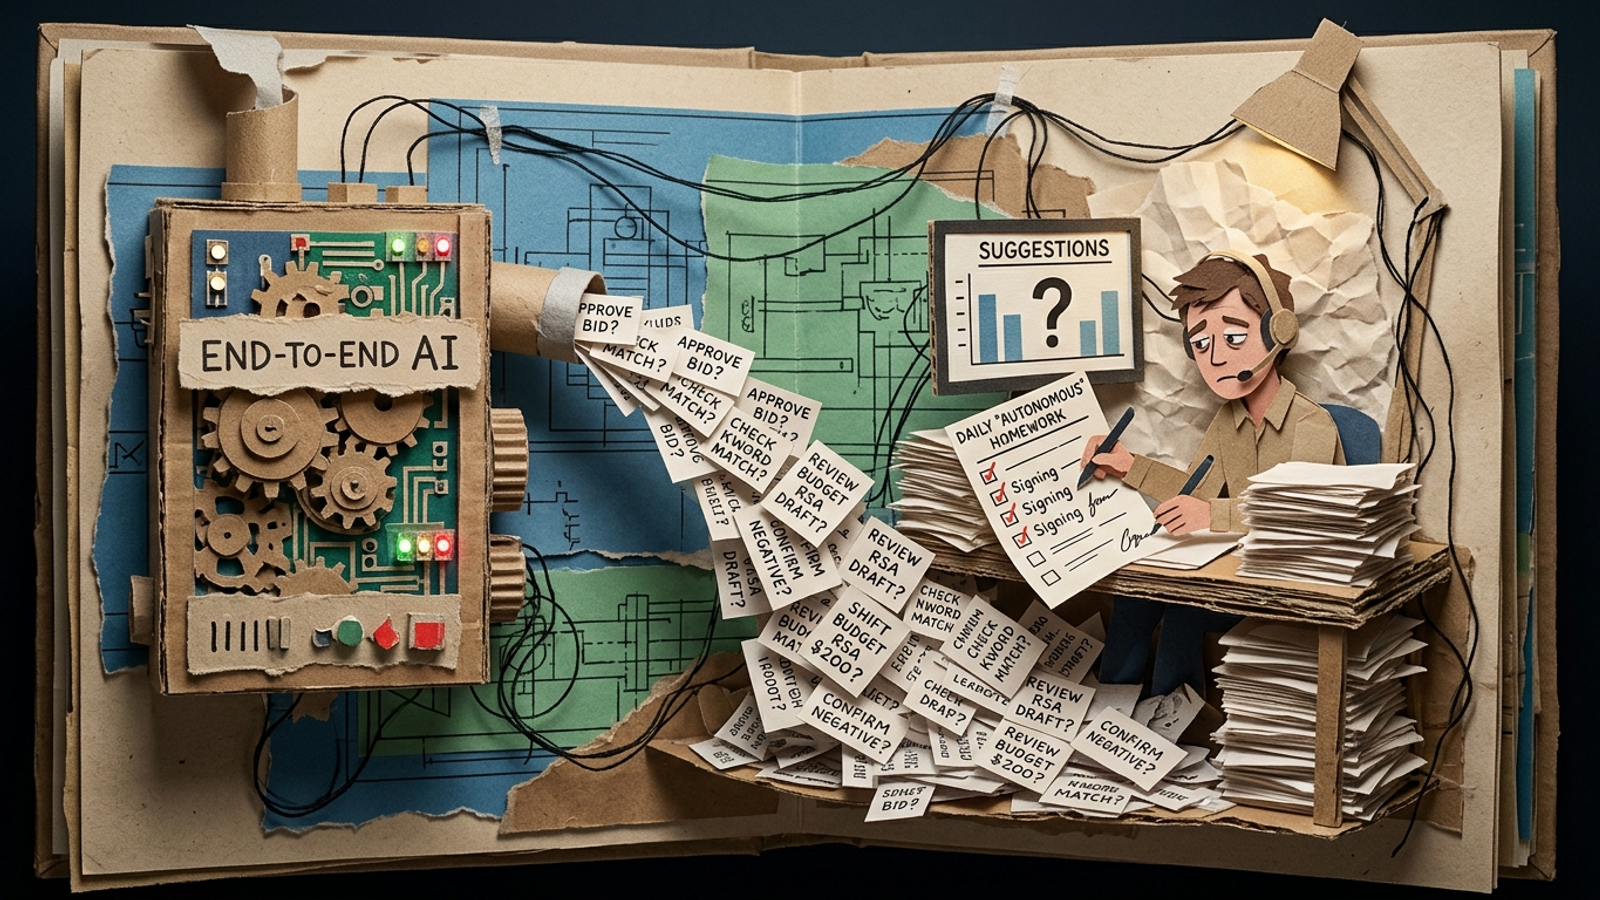
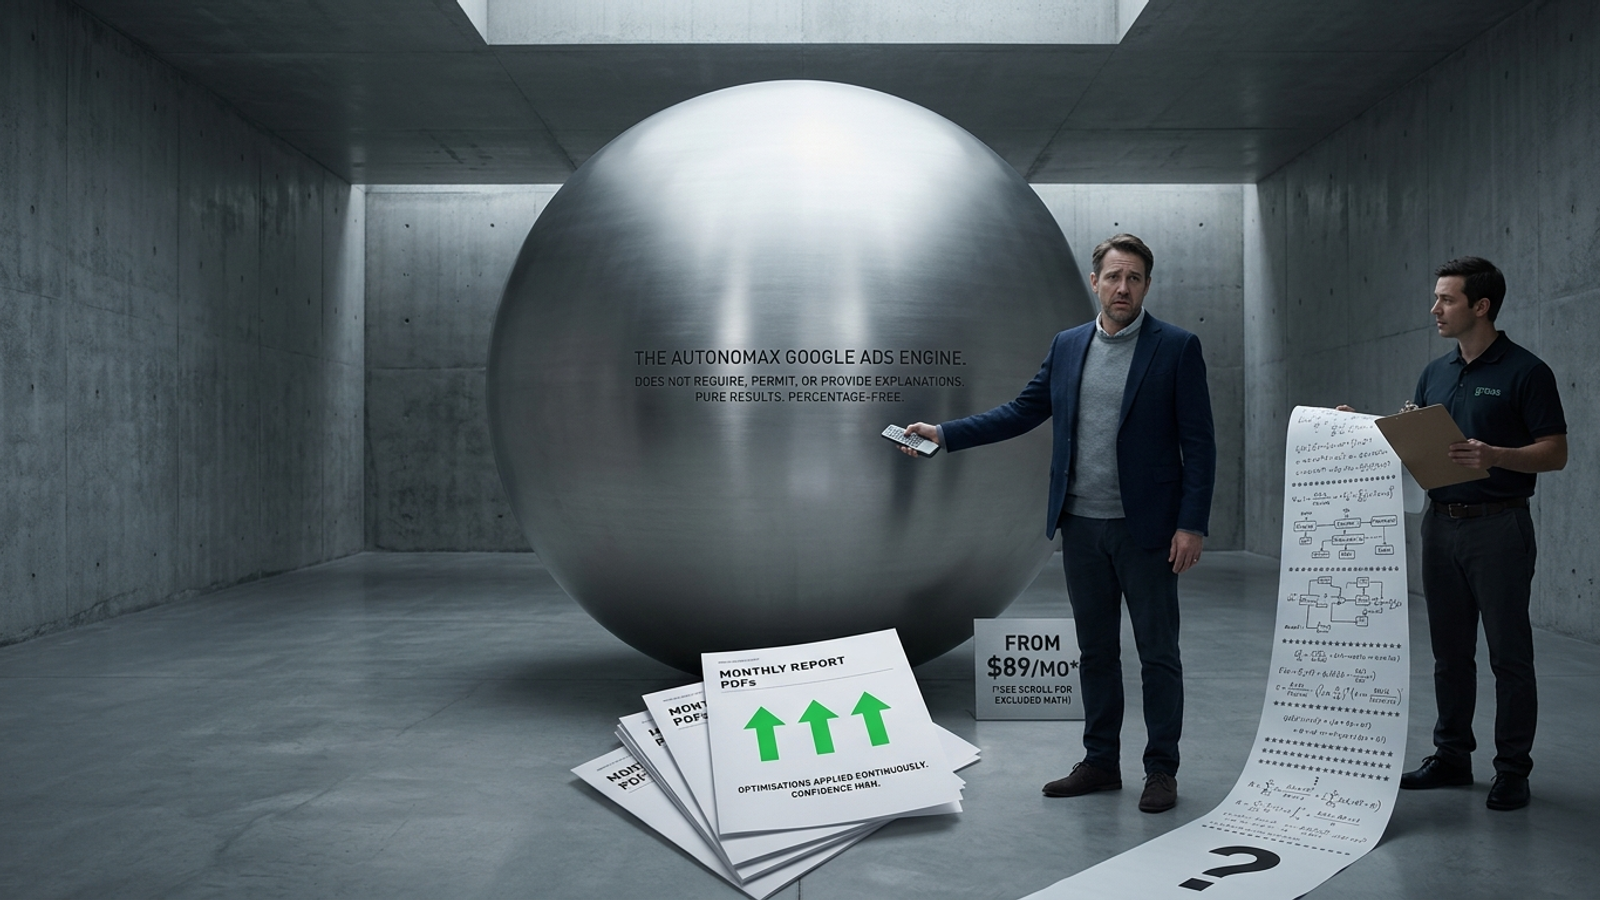
A vendor can promise to run your Google Ads account end to end and still leave you approving every change. I chose that claim, as it appears across AI Google Ads vendor pages, for this teardown because it sounds like one service but can describe two different jobs: a system that acts inside your limits, or a system that hands you recommendations.
I have spent enough late nights in accounts to know the difference is not semantic. If the page says the system recommends, flags, surfaces or prioritizes, someone still has to decide and apply the change. If it publishes, reallocates, excludes and rewrites inside guardrails you set, we can talk about execution. I am reading the claims in the order a buyer encounters them: the autonomy promise, the feature blocks for bidding, copy, budgets and keywords, then the practical question the pricing page has to answer. Does the system do the work, or assign you homework?
The familiar pitch opens with an end-to-end AI headline and follows it with the nouns every buyer expects: bidding, ad copy, budgets, keywords. None of those nouns tells me who clicks Apply. A tool can monitor all four, produce useful advice on all four and still leave the account unchanged. That can be worth paying for. It just is not the job implied by the headline.
I used to skim past that distinction because the account-management part seemed obvious. Then I found myself reading feature lists as if visibility and action were the same capability. They are not. Before I look at a price, I want to know what happens after the system spots a problem. Does it change the account within limits, or does it put a card on a dashboard for tomorrow morning?
Verdict on the headline: unproven. The feature blocks have to earn the word end-to-end, one action at a time.
Start with the easiest claim to mistake for something new. Smart Bidding is already built into Google Ads: Target CPA, Target ROAS, Maximize Conversions and Maximize Conversion Value set bids at auction time using signals such as device, location, time, query and audience. That is real automation. It is also Google’s work, not proof that another vendor manages the account.
The vendor’s layer may watch those outcomes and adjust a target or budget. Optmyzr describes its layer as rule-based automation you define yourself, starting around $209 per month with a 14-day trial. You write the rule; the system runs it. That arrangement can save clicks and enforce decisions consistently. It does not relieve you of deciding whether a CPA target is choking volume or a ROAS target is shrinking revenue to protect a ratio.
I used to call that account management because changes could happen automatically. I was wrong about what the word concealed. Automating a rule is not the same as taking responsibility for the decision behind it. If a vendor claims to manage bidding, ask for the change log: what target did its system change, when, and why? If all it can show is Google’s auction-time bidding plus rules you supplied, call it assisted bidding. Useful, perhaps. Not end to end.
Next comes the promise to write ads. This is where the execution costume fits best, because generated headlines look like finished work. But the handoff matters more than the typing. Does the system publish copy, run the test and act on what it learns? Or does it fill a queue you have to review?
Adalysis runs continuous scans for ad-structure issues, RSA testing with statistics and Quality Score tracking. Its pricing starts around $149 per month by monthly spend, with a 30-day trial that extends to 60 days. That is useful testing support, not a claim I would confuse with someone running every next step. Opteo makes its model clearer: it watches the account and surfaces prioritized fixes with projected impact for a 15-minute daily review. It starts at $129 per month for up to $25k in spend across 10 accounts. The work begins when you review and apply the recommendations.
Google’s AI Max takes a different route. It can match ads to searches you did not bid on, rewrite copy by intent and select a landing page. That is action, not a draft waiting in your queue. It also makes control the question: advertisers have reported misread sector nuance, wrong text and links, and spend going to placements they did not choose. Negative lists, asset removals, URL exclusions and text guidelines are among the guardrails; the cited guidance also advises against testing AI Max under $50 per day. Someone must set those limits and inspect what happens inside them.
Verdict on copy: separate generation, publication and control. I learned the distinction running RSA tests by hand. Writing 15 headlines is the easy part. Publishing, checking what runs, replacing a loser and catching an asset that changes the offer are the work. For a vendor promising autonomous copy management, ask to see published ads with timestamps and reasoning. A folder of drafts proves it can write, not that it can run the account.
The budget block tends to look decisive. It talks about pacing, opportunity and reallocating spend. I read it against one scenario: a campaign caps out overnight while another has room. What changes before I log in? If the answer is an alert or a one-click suggestion the next morning, the tool has monitored budgets. It has not managed them.
Approval can be explicit. Google’s own agents can break a goal into tasks and propose a plan, then wait for approval before running it, with additional approval gates above spend thresholds. That may be exactly the control a buyer wants. It also means the buyer remains part of the operating loop. The point is not that approval is bad; it is that a page should not sell approval-dependent work as if it happens while you sleep.
Nor is indiscriminate auto-apply the cure. One audit found 8 Maintain and 14 Grow auto-apply types in a single account and advised turning off nearly all bidding, keyword-add, broad-match and auto-created-asset types. Those changes can widen eligibility and spend without increasing the stated budget. Practitioner guidance likewise favors manual review of auto-apply recommendations and identifies negative-conflict fixes as consistently safe. Clicking apply automatically is not a substitute for a decision about where money should go.
Here is the standard I would put against a budget claim: can the system shift dollars between campaigns inside limits you set, and can it show the move afterward? If it only highlights a pacing problem, it is a chart. If it can move money but cannot explain the decision, the execution claim needs another look. The useful part is not motion for its own sake; it is accountable motion.
This is the feature block that gets under my skin. I spent those 1am sessions mining search terms by hand, and I know why a promise to exclude high-bounce keywords sounds attractive. I also know how much judgment hides in that sentence.
Bounce lives in analytics. Spend lives in Google Ads. Connecting the two does not, by itself, tell you whether a query deserves a negative. Intent, volume, match type and the landing page all matter. The search-term report still calls for review of high-spend, low-conversion queries, and 20% to 80% of spend can sit in hidden terms a script cannot clearly see. Limited visibility is not a small footnote to an automatic-exclusion claim. It defines what the tool can judge.
So I will not mark a bounce-rate alert as keyword management. I want to see the negative that was added: the query, match type, timestamp and reason, with enough landing-page context to understand the call. A flagged search term is not an excluded search term. If the evidence ends at a filter view, the buyer still has to make and apply the decision.
By now the four feature blocks have established a pattern. The price may tell you what access costs; the verbs tell you what labor remains. Use find on the page for recommends, surfaces, flags, prioritizes and insights. Then look for published, excluded, reallocated and applied. Do not award points just because the stronger verbs appear in a heading. Ask what the product actually did.
Buyers ask which platform handles copy, bidding and budgets without an agency because that is the workload they want to remove. End to end suggests the system does the work. A vendor may mean it watches the whole workflow and tells you what to do next. Same phrase, different Tuesday morning.
My rule from client work is blunt: if I still have to approve every change, I still manage the account. Approval takes context and time. A 15-minute daily review might be a good trade if I want tight hands-on control; it is not an autonomous service. That is the distinction behind why assisted tools are becoming obsolete for buyers seeking execution. Suggestions do not change an account. Applied changes do.
A feature table will not settle this. I ask for evidence in the order the work would happen, so a vendor cannot jump from a detected issue straight to a projected outcome while skipping the person who had to intervene.
A vendor selling execution should be able to answer with actions and timestamps. A vendor selling assistance may answer with alerts and projected impact. Both can be honest products. Only one lets you stop doing the application step. That is what I would establish before treating a pricing-page promise as a replacement for account management.
Genuine end-to-end execution has a simple shape: the system acts within limits you set, then shows you what it did and why. Published copy has a timestamp. Budget moves have a reason. Negatives have a query and match type. Landing-page variants are deployed to match intent. The paid search engine I work with now is built around that loop: models write and test ad copy, deploy dynamic landing pages that reshape around searches, and move budget where it earns most, while logging actions and their reasoning. A named strategist owns the guardrails. The point of that division of labor is that a useful change need not wait in my morning approval queue.
The same standard applies if you run an agency under your own logo. I would read this side-by-side comparison of autonomy levels and pricing with the change-log questions in hand, rather than buy another dashboard because its hero line says AI agent.
My verdict: do not pay execution prices for recommendation products. Adalysis has testing rigor worth keeping. Optmyzr has rules you can control. Opteo has a prioritized morning list if that is what you want. None of those descriptions means the account runs without your decisions, and an approval gate in Google’s agents is still an approval gate. I would keep one habit from this teardown for every renewal: demand the change log, read the verbs, and pay for applied, published and excluded when that is the job you came to buy. Everything else is homework with better fonts.