

 LinkedIn
Your AI visibility dashboard can tell you whether your brand appeared in 20 test prompts. It cannot tell you which of your pages an assistant fetched when someone else asked a question. For that, I want the server logs.
We published 30 Days of AI Bot Logs: Thousands of Hits, Zero Answers for Category Pages as one site’s result. But someone else’s logs cannot tell you what assistants do with your pages. This second look gives you the test to run on your own site. The question is narrow: which URLs receive verified live-answer fetches, and how many does each receive? That count is the most reliable AI visibility metric you can measure directly. It records retrieval tied to a live-answer request, not a vendor’s estimate of whether you might get mentioned.
Question: what did an assistant fetch, not what did a prompt tool say?
Prompt tracking asks whether your brand appears when you submit a chosen set of questions. Your logs ask which URLs an assistant requested during live-answer activity over a period. Those are different observations. A prompt result can show you a mention or citation for the questions you tested. A verified fetch can show that an assistant retrieved one of your pages. A fetch is not, by itself, proof that the answer cited your page. Keep that limit in view while you count.
I used to treat bot hits as a rough visibility proxy. That was a mistake: I was combining several jobs under one tidy label. OpenAI runs separate agents for training, search indexing and on-demand fetches. Perplexity distinguishes indexing from user-triggered fetches, and Anthropic distinguishes training, search-index quality and user-directed retrieval. A training crawler visiting a page and an assistant fetching it in response to a person are not the same outcome. Put them in separate columns before you decide anything about content.
Setup: fix the window and the counting rules
Start with 30 days of raw access or CDN edge logs containing a user-agent and IP for each request. Use a spreadsheet or SQL, whichever lets you filter without losing the raw rows. A week can leave you reacting to a thin slice of activity; a month gives you a more useful first comparison across pages. If your site is small, the longer-window option comes later.
Before you look at the winners, write down the rules you will use for every URL:
- Set one date range. Use the same 30-day window for every page. Do not compare a month’s homepage traffic with a week’s article traffic and call the difference a content insight.
- Keep the URL attached to each request. The page is the unit of this test. A site-wide AI bot total hides the difference between a useful answer page and a category index that gets crawled but not fetched for live answers.
- Separate claimed identity from verified identity. A user-agent is a claim. Check its IP before treating it as a vendor request.
- Separate crawler jobs from live-answer fetches. A verified indexing request still belongs in the crawler column, not the live-answer column.
- Keep the rules unchanged when you rerun the test. Otherwise a change in your filtering can masquerade as a change in visibility.
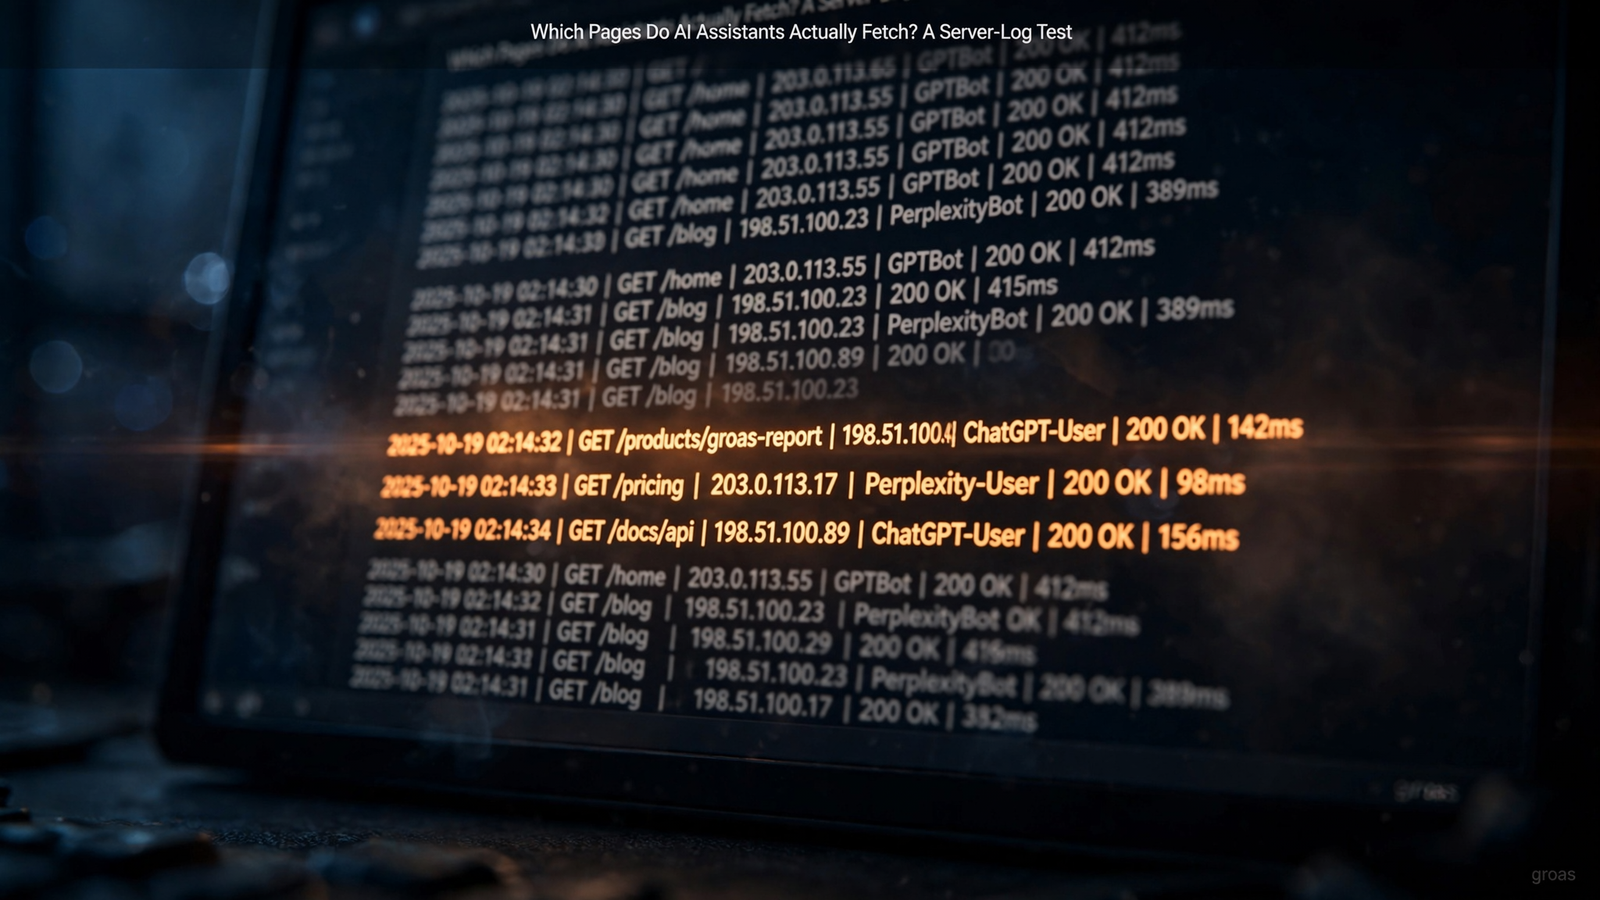
Now pull requests claiming an AI identity and assign them to buckets. For live-answer fetchers, look for ChatGPT-User, Claude-User and Perplexity-User. For index and training crawlers, keep GPTBot, OAI-SearchBot, ClaudeBot and PerplexityBot apart from that group. Both groups matter; only one answers this test’s central question.
Verification: make the bot prove it belongs in the bucket
Any script can call itself ChatGPT-User. Match the IP behind each claimed request against the vendor’s published information, then exclude claims that do not pass. OpenAI publishes separate IP files per agent. Perplexity publishes perplexitybot.json and perplexity-user.json. Anthropic publishes a bots.json list. Refresh your check as those lists change; a lookup you ran once is not a permanent control.
This is not pedantry for people who enjoy spreadsheets too much. In a two-week analysis of 16 AI crawlers, 5.7% of traffic claiming an AI identity was spoofed. ChatGPT-User was the most abused, at about one in six fakes; Perplexity-User was cleaner, at roughly one in 88. Those are that analysis’s results, not a discount you should automatically apply to your own totals. Check your own IPs. If a request fails, it does not get to vote on which page won.
Measurement: three counts for every URL
Build a table with one row per URL and three counts. Do not collapse them into an AI traffic number:
- Claimed hits: requests whose user-agents say they belong to the AI agents you are tracking.
- Verified hits: claimed requests that pass the vendor-IP check, including crawler activity.
- Verified live-answer fetches: verified requests from
ChatGPT-User,Claude-UserorPerplexity-User.
Our homepage, for example, logged 11,441 claimed hits in 30 days; 2,187 survived verification. That gap is why I would not start a content meeting with a user-agent chart. It tells you how much of the apparent activity made it past one necessary check, not how often the homepage helped form a live answer. The third column is the one to rank when the question is live retrieval.
Track robots.txt requests separately, too. They can tell you about permission checks on the retrieval path, and they can spike around Claude-User and ChatGPT-User activity. They are not page fetches or citations. Let them explain an access question; do not add them to a URL’s live-answer count.
Controls: stop a noisy URL from winning by accident
Before you interpret the ranking, inspect the table for three easy ways to fool yourself. First, check whether the apparent winner has mostly claimed hits rather than verified ones. Second, check whether its verified activity comes from crawlers rather than live-answer agents. Third, keep image paths and other non-page requests visible instead of letting them disappear into a page total. One image path in our logs showed 2,355 claimed hits but only 250 verified. A busy path is not necessarily an answer page.
The same restraint applies to a manual prompt check. You can note which URL an answer cites, but do not assume a log row and a citation belong to the same individual exchange simply because they happened on the same day. Logs give you a strong page-level retrieval measure across the window. Your prompt sheet gives you a separate look at selected answers. Compare the patterns, not imaginary one-to-one matches.
Readout: concentration, empty volume or noise
Once the controls hold, sort URLs by verified live-answer fetches. I would look for three patterns, in this order.
- Concentration on answer pages. In our logs, 920 live ChatGPT fetches went to two dated Google Ads update posts, while the rest of the site split the remainder. If your own top five URLs account for 80% of verified live fetches, inspect their structure. You have a template worth testing elsewhere, not proof that every page on that topic needs a twin. Copy the way a page answers; do not copy the topic blindly.
- Crawler volume without live retrieval. Category pages in our test each drew more than 3,000 claimed bot hits and received zero live-answer fetches. More crawls would not, on their own, close that gap. Check whether those pages actually answer a narrow question before making them longer.
- Identity noise. If the claimed total towers over the verified total, investigate verification before treating a spike as progress. In our logs, homepage verification was roughly one hit in five. A dashboard can make costume traffic look like a trend. The IP check decides whether it belongs in your readout.
These patterns lead to different work: build on a useful answer structure, rethink pages that attract crawlers but no live fetches, or fix a noisy measurement line. Do not prescribe new content to all three.
Cross-check: put your 20 money prompts beside the logs
Choose 20 questions a buyer might actually type, rather than accepting a tool’s suggested list. Run each manually in ChatGPT and Perplexity on the same day, in clean sessions, and record every cited URL. Keep a brand mention without a link separate from a cited page; a mention is not evidence that the assistant fetched your site.
Now place that prompt sheet beside your log table. Expect disagreement, and do not try to erase it with one blended score. In a cross-platform test of 118,000 answers, 11% of domains overlapped between ChatGPT and Perplexity for the same queries, while 71% of cited sources appeared on only one platform. Perplexity averaged 21.87 sources per answer against ChatGPT’s 7.92. That test describes its own answers; the reason to check yours is that platform and prompt choices can produce different views.
Prompt tools simulate sessions and standardize messy outputs. That makes them useful for a repeatable set of questions, but directional as a measure of everything assistants retrieve. If your logs show verified live fetches for a page no prompt tool reports, the logs still show retrieval happened. If a tool reports a mention and your logs show no corresponding live fetches, treat the mention as a content lead, not proof of retrieval. Keep both observations. Let neither claim to measure the other’s job.
Boundary: use a different check for Google’s AI surfaces
This log test does not give you an equivalent Gemini live-fetch column. There is no GeminiBot crawler to filter the way you filter ChatGPT-User. Gemini uses the Google Search index built by Googlebot, while Google-Extended is a robots.txt token rather than a separate crawler. You cannot turn that token into a log count of Gemini live-answer fetches.
For Google’s side, look in Search Console: AI Overviews and AI Mode activity sits within the main Performance report under Web search type, without a separate AI filter. One practical cut is to isolate long, prompt-like queries with a regex such as ^(\S+\s+){9,}\S+$, as described in this Search Console analysis. Pair that view with manual citation checks on your money prompts. It is a different readout, with different limits. Do not stretch a ChatGPT, Claude and Perplexity log test into a claim about Google.
Next run: change the page, or fix access first
If live fetches cluster on a few pages, take your top three and examine their structure. The pattern I look for is plain: a specific question in the H1, a dated update line that reflects real maintenance, a direct answer in the first 80 words, then numbers, definitions or steps a model can use. Build the next two pages on that skeleton. Give each one a question, a date you will actually maintain, and a table or list that carries the answer. If a category index gets crawled but not fetched, do not turn it into a longer index and call that coverage. Pick a category with real demand and try three narrow answers instead.
Rerun the pull monthly with the same 30-day window, three counts and prompt cross-check. Keep a one-line record per URL: claimed, verified, live. If a page’s live fetches rise across two monthly checks, update it and test its structure on another page. If claimed hits rise by 2,000 while live fetches stay at zero, the page is louder, not demonstrably more useful for live retrieval. Rewrite its opening answer before adding word count.
I expect this test to embarrass some dashboards in a useful way. The mechanism is simple: vendors use different agents for different jobs, while a single AI bot traffic line counts them together. Splitting those jobs and checking IPs leaves you with a smaller, more actionable set of pages. If that set is empty, check access before buying more content: confirm robots.txt allows ChatGPT-User, Claude-User and Perplexity-User; confirm your top pages return 200 to verified IPs without a bot-wall challenge; then rerun for 30 days. Publishing more cannot repair a blocked retrieval path.
I would rather you skip this test than run it badly. If your host gives you only an aggregated bot report with no IP column, you cannot do the verification step. Cloudflare, CloudFront and most CDNs can export raw logs, but an export you cannot obtain does you no good. If your site gets under a few thousand visits a month, a 30-day slice may leave you with single-digit live fetches. Run 60 days instead, or pool pages by template, and resist treating one request as a trend. Refresh vendor IP lists quarterly. Lists change; a check you ran once in January is decoration by July.
If you run an ads account with real spend behind it, this work pairs with the part I do every day. At groas, we run SEO and AI search as continuous execution: pages that win live fetches get maintained, expanded and tied to pipeline instead of being left to decay after publication. Run the log test yourself first. If fetches cluster on two or three pages, you know which structure is worth scaling. If there are none, you know to check access and the pages themselves before paying anyone to produce more of them.
Run it once and the argument changes. You either see which URLs assistants fetched for live answers, or you see a blank column that sends you to access, verification and page structure in that order. Report that column next month, and the month after. Stop renting a score; start counting the fetches.