LinkedIn
Your first ChatGPT Ads test gets $1,000 in media, 30 days, and no blind budget increases. You are buying an answer, not scale: did real people reach your site, did any of them contact you, and do the numbers hold together well enough to justify another dollar?
That last question matters because agencies are reporting platform clicks that do not match their own tracking and conversions that arrive late. A dashboard can look promising or empty for reasons that have little to do with the people behind the clicks. I would rather spend a small, fixed amount learning which numbers describe the customer journey than spend more trying to outrun a measurement problem.
Here is the plan in order. Each step charges a defined amount against the $1,000 media cap and buys a specific piece of evidence. Anything that does not help make the final spending decision gets cut.
1. Set the assignment: one offer, one page, $1,000
Cost: $0 of the media cap. Buys: a test small enough to interpret. The $1,000 is a proposed ceiling, not a platform minimum or a promise of enough data. Self-serve ChatGPT Ads has a $25-per-day campaign minimum in the US, so you could technically spend less. I am proposing $1,000 over 30 days because a firm cap forces a choice: one offer, one landing page, one result worth counting.
At the $3 to $5 suggested starting CPCs now circulating, that cap might buy about 200 to 300 clicks. That is thin evidence for a scale decision. It is still enough to test whether your tracking works and whether the first inquiries resemble customers. A second offer would make the answer harder to read, not more persuasive. Cut it. Cut the second landing page, too.
Management sits outside the media cap, and I want both costs visible before anyone signs. With groas Search Ads at $1,499 a month for Google, Bing, and ChatGPT together, the month-one total for this plan is up to $2,499: $1,499 for management plus no more than $1,000 in media. The flat fee matters here. Nobody earns a larger management fee by burning the test budget faster.
Hand whoever runs the account the brief as written: no extra learning budget, no setup upsell, and no increase without your written approval. For this test, allocate $225 to days 1–7, $550 to days 8–21, and $225 to days 22–30. That adds to exactly $1,000. It is a ceiling for each phase, not an instruction to spend money that the evidence tells you to stop spending.
2. Before launch, define the journey you intend to measure
Cost: $0. Buys: a shared definition of a result before the reports start arguing. Ask the agency for three sentences in ordinary English:
- What does the customer see inside ChatGPT?
- Where does the customer land after clicking?
- What single action counts as a business result?
If the answer needs a diagram or the word synergy, send it back. I used to accept fuzzy conversion definitions because everyone seemed to know what we meant. I was wrong. Once the numbers disagree, a vague definition gives every report its own escape hatch.
Pick one outcome you can check in your own systems: an inquiry with a name and a real need, an appointment that appears on the calendar, or a sale with money attached. Choose the one that fits the offer and write it down. A page view is not an inquiry. A long chat is not a booked appointment. A newsletter signup does not become a qualified lead because week one looks quiet.
Confirm the audience before launch, too. Ads reach logged-in adult Free and Go users; Plus, Pro, Business, and Enterprise users do not see them. Then agree in writing that no bid, budget, or landing-page changes happen during this test without your approval. That rule prevents a well-meaning manager from changing the conditions while you are still trying to understand them.
Cut the extra goals. If the agency reports five different kinds of success, it becomes too easy to celebrate whichever column moved. One outcome makes the eventual stop-or-continue call uncomfortable, which is another way of saying useful.
3. Days 1–7: spend $225 checking whether clicks become visits
Cost: up to $225. Buys: evidence that the funnel is wired correctly. Do not optimize yet. ChatGPT Ads Manager counts clicks, your analytics records visits, and your inbox or backend records inquiries. Those are three views of a journey, not three interchangeable numbers. If you cannot connect them, a week-three argument about performance is mostly theater.
Ask for these numbers side by side each day:
- Platform clicks: the count in ChatGPT Ads Manager.
- Recorded visits: your own analytics, filtered to
utm_source=chatgptandutm_medium=cpc, with campaign and ad IDs. - Actual inquiries: form entries, booked calls, or orders you can inspect in your backend.
The middle line does the heavy lifting. An ad click appends an opaque oppref ID that the pixel stores in a first-party cookie for attribution. But oppref is not a GA4 source or medium; without your UTMs, paid clicks can appear as chatgpt.com referrals or Direct. Put the UTMs in the landing-page query parameter field. Tell whoever manages redirects not to strip oppref. If visits are landing in the wrong bucket, fix the route before treating the bucket as a performance report.
Expect some disagreement. Investigate the gaps rather than demanding identical columns: conversion tracking defaults to 30-day click plus 1-day view attribution, dates conversions to ad-interaction time, and processes them daily. Give conversions at least a day before judging them. Consent banners, ad blockers, and slow pages can create further differences between clicks and recorded visits.
The week-one question is not, “Did every click match?” It is, “Can we explain the ratio between platform clicks and recorded visits, and does that explanation keep holding?” If the answer is no, keep the cap in place and work on the measurement. Do not pay to scale a mystery.
4. Days 8–21: spend $550 without chasing yesterday’s dashboard
Cost: up to $550. Buys: a longer read on inquiries and protection from premature changes. The expensive mistake in this phase is treating an unfinished report as a verdict. I have watched buyers kill a decent test in week two because the dashboard looked empty. An empty ChatGPT Ads dashboard can reflect reporting delay; it cannot, by itself, tell you that nobody contacted the business.
One agency told Digiday that a UK lead-generation campaign produced form fills while Ads Manager still showed zero conversions two weeks later. In that account, it also saw about 100 platform clicks against about 20 in its own tracking, with OpenAI support unable to explain the gap at the time. Another agency reported conversions arriving 24 to 36 hours late compared with a few hours on Google, without demographic or prompt data attached. Late reporting creates the temptation to change bids before you know what the earlier spend bought. Resist it.
Keep the daily cap fixed. Cut new audiences, bid experiments, and budget shifts while you check the plumbing. The work in this phase is plain, not glamorous:
- Submit a test inquiry. Confirm that it reaches the inbox and CRM where a real inquiry would be handled.
- Compare backend inquiries or orders with pixel-reported conversions before trusting either number alone.
- Read the attribution rule with the agency. Everyone should know why a conversion can appear later while being dated to the earlier ad interaction.
- Check forms, consent banners, UTMs, redirects, and definitions when clicks and visits disagree.
That is not a claim that every ChatGPT Ads account has broken tracking. Other buyers in the same Digiday report, including AdRoll and Jellyfish, said they had not seen click gaps. The point is narrower and more useful: you cannot assume that somebody else’s clean or messy account describes yours.
If the numbers remain confusing, do not cure the confusion with a larger budget. Spend within the phase cap while investigating, or stop. If the numbers become readable, leave the test conditions alone long enough to see whether genuine inquiries follow. The cap buys time to distinguish a reporting delay from a weak offer. It does not buy permission to improvise a new campaign halfway through.
5. Days 22–30: spend $225 on a decision, not a nicer chart
Cost: up to $225, bringing maximum media spend to $1,000. Buys: a stop, repeat, or increase decision. By now you have seen how your own visits compare with platform clicks and how long your own outcomes take to appear. Give the last conversions time to arrive before making the call. Then choose one of three paths:
- Stop if you still cannot connect platform clicks to recorded visits well enough to understand the test, or if the inquiries you can verify fail basic qualification when you follow up.
- Repeat at the same cap if tracking is readable and the early inquiries look real, but there are too few to put a defensible price on the outcome.
- Increase only with written approval if you can defend the cost per business outcome using your own records. A lower CPC or a better-looking dashboard is not enough.
The larger buyers are showing the same restraint at different price points. One executive spending $10 million a month on Google keeps ChatGPT below $100,000 a month until measurement firms up; another agency says unanswered tracking questions keep clients from moving £10,000 to £20,000 tests up to £100,000. Those figures come from Digiday’s reporting on measurement gaps holding budgets at test level. You do not need their budgets to borrow their rule: evidence precedes expansion.
Cut the urge to dress up an inconclusive result as either triumph or disaster. A small independent test spent $477 across 19,154 impressions and 370 clicks and produced zero sales, although analytics confirmed the clicks were real. ChatGPT visitors stayed 37 seconds, against 443 seconds for organic referrals in that Barn2 test. Another $500 small-business test spent its budget in just over an hour at about $3.50 per click; roughly 13% of clicks verifiably reached the site, and it recorded zero leads in the Out of the Box Advisors test.
I read those as warnings about what a first test must resolve, not verdicts on every advertiser. If your own month ends with clean tracking and weak intent, the $1,000 did its job. It kept you from spending $10,000 to learn the same thing. If the tracking stays broken, that is also a decision: do not increase spend on a result you cannot verify.
6. Get the handover before the cap lifts
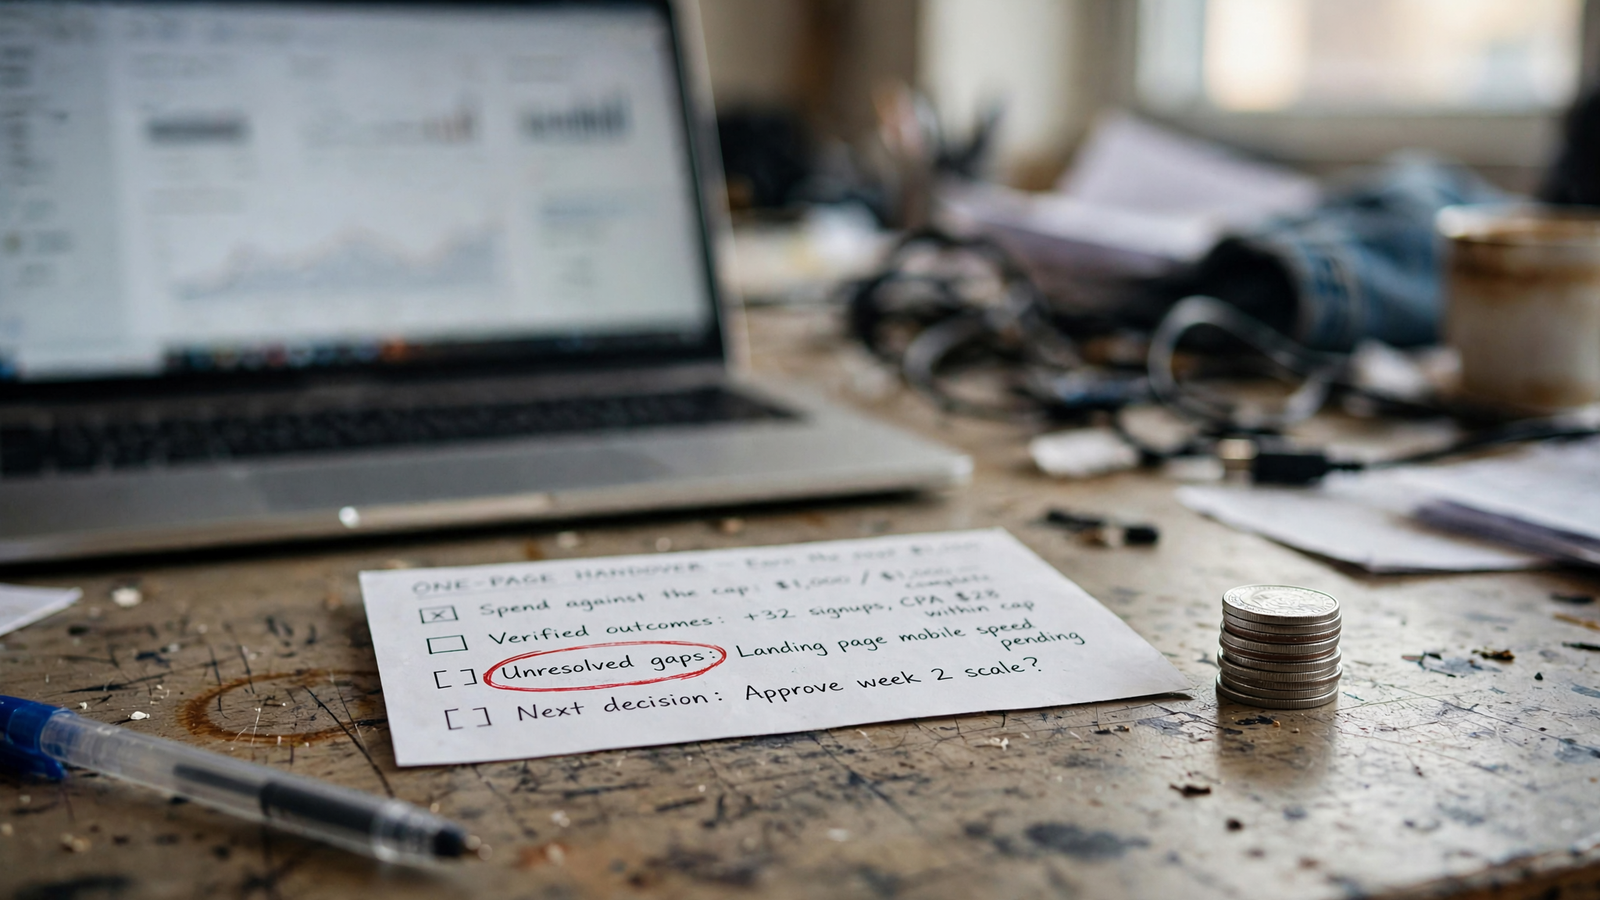
Cost: $0 of the media cap. Buys: a record you can use without the manager on the call. Demand one page before anyone proposes scaling. Cut the dashboard export with a highlight color on the good week. If the learning disappears when the account manager leaves the room, you did not buy learning.
The handover needs four lines:
- Spend: total media cost against the $1,000 cap, with dates and daily caps.
- Verified outcomes: UTM-tagged visits recorded in your analytics; inquiries or sales you can open in your inbox, CRM, or backend; and media cost per verified outcome.
- Unresolved gaps: clicks that did not resolve to recorded visits, conversions that arrived late, and UTMs or redirects that broke.
- Next decision: stop, repeat at the same cap, or request approval for an increase, with the reason in one sentence.
When the constraint lifts, it lifts on your terms. Do not double spend because week four looked lively. Repeat the cap until the ratio of platform clicks to your recorded visits holds steady for two straight weeks and late conversions stop rewriting the story. Then raise media in one step you can still afford to waste, keep the single offer, and keep the written-approval rule. I agree with the advice to establish independent measurement before testing rather than take platform metrics at face value. Your UTMs and backend come first, their dashboard second, more money last.
This is also where the management incentive matters. A percentage-of-spend manager earns more as the budget rises. That is the wrong incentive for a first test with delayed reporting. groas runs Search Ads across ChatGPT, Google, and Bing for a flat $1,499 a month with no cut of spend. Within your guardrails, you get continuous work on bids, targeting, and budgets, logged actions, and a named strategist who must defend the handover with you. For this test, the written-approval freeze still applies. If the evidence says stop, we stop. If it says repeat, we repeat.
Apply for the test, keep the $1,000 ceiling, and make the next budget increase something the numbers earned.