The Google Ads AI Glossary: What the Settings Say and What They Actually Control
October 2, 2026
•
11
min read
An AI agent will not rescue a Google Ads account whose owner cannot say what a good customer is. It will, however, do a lot of the work I used to do at 1am: mine search terms, block waste, shift budgets and rotate copy. Most of the fear and hype comes from treating the agent as either a black box that replaces judgment or Smart Bidding with a new label. Execution can be autonomous; commercial judgment still needs an owner.
The panic version goes like this: a rogue algorithm wakes up at 3am, misreads a broad-match query, dumps $15,000 into irrelevant clicks and leaves you arguing with a chatbot. I understand the fear. Anyone who has watched a sloppy Google Ads script run unchecked knows that faster execution is not automatically better execution.
But autonomy without guardrails is not a management plan. As practitioners discussing AI agent ad management architecture have noted, a system without a reliable way to evaluate its actions can do the wrong thing faster. Someone still has to define what the system may change, what deserves review and which business outcome counts as success. Those are not settings to forget after launch. If the offer changes or the account starts attracting a different kind of lead, someone has to decide whether the rules still fit.
That changes the human job rather than eliminating it. At groas, specialized models handle bidding, search-intent filtering and copy adjustments continuously. A named human strategist sets direction, defines guardrails and answers for performance in a dedicated Slack channel. I would rather have that division of labor than pay a person to push every button. I also would not mistake a list of automated actions for accountability. A log tells me what happened; a person has to answer whether it should have happened. The question is not whether a human clicks Save. It is who owns the result when the clicks stop working.
This one sounds sensible. Google already adjusts bids at auction time, so why pay another system to manage the account? If an agent did nothing beyond changing bid targets, I would ask the same question.
Smart Bidding handles auction-time bid decisions using signals such as device, time and location. It does not own the wider account-management job: deciding which search queries are irrelevant, whether an ad group matches the offer, which copy deserves another test or where a budget is better spent. The distinction matters because a clever bid on the wrong traffic is still a clever way to waste money. This breakdown of Google’s bidding systems gets at the gap between bid automation and account control.
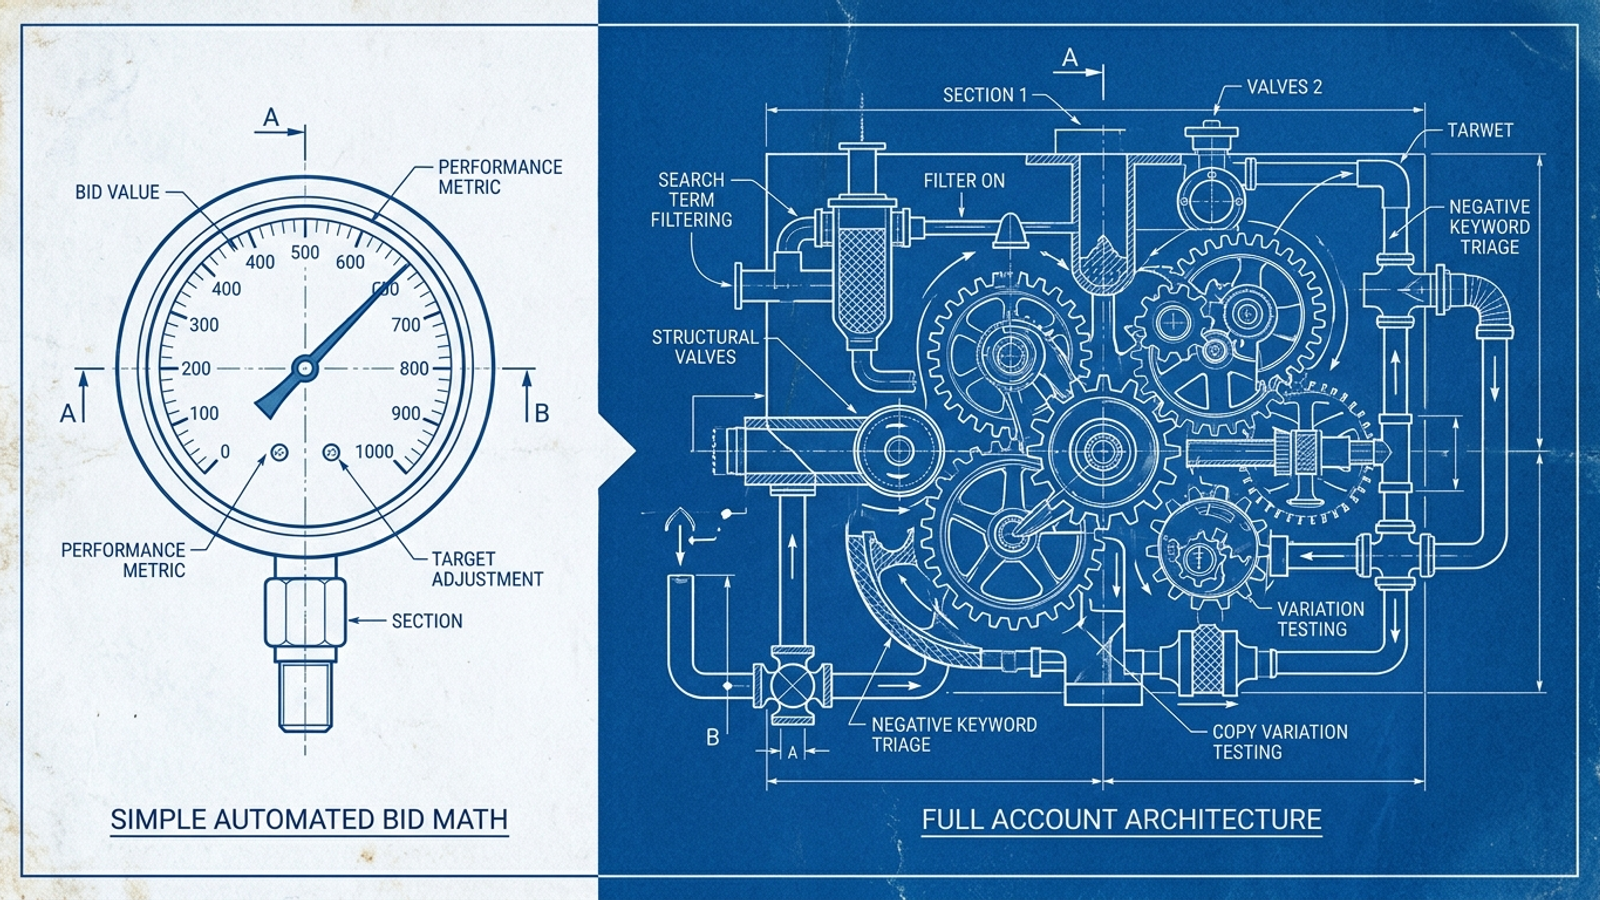
Say broad match brings in dozens of searches from people looking for something you do not sell. Auction-time bidding can respond to the conversion signals it has. It cannot supply the commercial judgment that those searches never belonged in the account. An autonomous management system can analyze the query language, add negatives, move budget away from poor-fit traffic and test different copy. groas’s paid-search management works on that broader set of decisions, not just the number entered into an auction.
That does not make every negative keyword or budget move automatically right. Someone must define the offer closely enough that the system can tell a poor-fit search from an unfamiliar but promising one. Otherwise, the account can get very efficient at excluding potential customers. Smart Bidding manages bids. An agent worth paying for manages what those bids are being asked to do.
I can see the appeal: connect the account, attach a card and receive a tidy PDF once a month. Agencies have encouraged that arrangement for years. A polished deck can make a quiet account look busy, especially when the client sees an impression curve but not the decisions behind it.
The problem is timing. A monthly report is an autopsy, not an operational control. If broad search terms start attracting job seekers instead of buyers, the account needs a response while that traffic is still arriving. Finding out weeks later may explain the bill, but it does not undo it. Nor does a chart of last month’s clicks tell you whether the response was to block the irrelevant searches or simply pay less for them.
Hands-off should mean you do not have to build negative-keyword lists or balance match types in a spreadsheet at midnight. It should not mean you have no idea what happened to your money. groas logs account actions, including blocked queries, bid adjustments and copy changes, with the reasoning behind them. A named strategist is available in a dedicated Slack channel. That gives an owner a way to inspect the work without becoming the account manager.
I would ask any provider to show me what changed, why it changed and who I can challenge about it. If the answer is a monthly slide deck, that is not much of an upgrade.
Some automation pitches make update frequency sound like the goal. They invite you to picture an agent nudging Target CPA every eleven minutes, as if the account were a trading desk. Activity makes a good demo. It does not necessarily make a good campaign.
Google’s bidding systems need room to respond to changes. Repeatedly moving budgets and targets can make it harder to tell whether a campaign is improving or merely adjusting to the latest instruction. Google Ads documentation and this discussion of learning periods are useful reminders that a setting change has consequences beyond the moment someone presses the button. A bot that constantly tinkers with core parameters can spend its day creating work for the bidding system. I have done enough manual tinkering to know that doing it faster is not a strategy.
Always-on should describe attention, not constant interference. Search queries can be reviewed, poor-fit terms flagged, creative assessed and broken tracking spotted without treating every new data point as a reason to reset a bid target. Larger changes deserve patience and enough conversion information to judge them. Reporting on Smart Bidding’s need for conversion data makes the same practical point: do not confuse a fast reaction with an informed one.
There is a useful difference between removing a plainly irrelevant search and deciding that a bid target is wrong. The first can follow from the words in the query and the offer on the page. The second asks you to interpret performance after the system has had time to respond. The machine earns its keep when it acts promptly on clear waste and leaves uncertain decisions alone long enough to learn something.
People hear machine learning and assume every useful action needs an ocean of conversions. There is a real distinction here: low conversion volume makes statistical bid optimization harder. It does not make every account-management task impossible.
An agent does not need 500 sales to notice that an ad group for custom enterprise software is matching against “free download open source code.” Query language, landing-page fit and negative keywords are questions of intent as well as data volume. That distinction also comes up in practitioner discussions of autonomous ad tech. You still need to know what the business sells before calling a query irrelevant. But you do not need to wait for a neat conversion sample to ask whether the search and the offer belong together.
On a smaller budget, waste can be especially painful. If you spend $3,000 a month and $600 goes to irrelevant broad-match searches, that is a fifth of the budget gone before you get to argue about sophisticated bid models. Do not mistake a thin conversion history for a reason to ignore obvious bad traffic. An agent may have less evidence for some decisions, but it can still do useful structural work. I would judge that work separately from any promise that it can settle every bidding question on limited data.
Buyers tend to expect one of two things: a $49-a-month widget that produces suggestions, or an agency selling “proprietary algorithms” while charging a percentage of spend and an onboarding fee. Neither price tells you how much useful work gets done.
The old agency model was built around human hours. Search-term reviews, copy rotation and routine budget checks took time, and somebody had to pay for that time. I know; I did the work. Automation changes the cost of execution, but it does not make sound strategy free. It makes the distinction between execution and judgment harder to hide behind a retainer. If the software only tells you which terms to review, you still need someone to review them. A cheap suggestion is not the same thing as completed account work.
A percentage-of-spend fee also rises when your budget rises, even if the management workload does not rise in the same proportion. That tension comes up repeatedly in discussions of flat fees versus spend-based pricing. Clutch’s PPC pricing figures offer another way to see what human-hour billing can cost. The point is not that every agency wastes its fees. It is that paying human-hour rates for automated triage deserves a closer look.
groas charges a flat monthly fee, with no setup fee and month-to-month terms. The value is not cheap software; it is continuous execution with a human responsible for the decisions that still require judgment. That is what I would compare against a spend-based fee, not the number of buttons a dashboard offers.
This is the hardest one to kill. A founder connects Google Ads, sees the word AI and expects the system to distinguish an enterprise buyer from a student downloading a PDF for homework. If the account only tells the system that both people completed a form, why would it know the difference?
Automation pursues the conversion event you give it. This analysis of PPC lead quality and this warning about automated bidding mistakes describe the familiar failure: optimize for raw form fills, get more raw form fills, then discover that sales does not want them. A low cost per lead can look excellent in a report while the CRM fills with people who will never buy. The system has not betrayed its instructions. It has followed them. More frequent adjustments will not repair a definition of success that was wrong to begin with.
The fix is not to tell the agent to be smarter in an open-ended prompt. It is to give it better business signals. Connect offline conversions and CRM stages; distinguish sales-qualified leads, booked demos and closed-won revenue from a generic form submission. This discussion of AI and human control in Google Ads makes the need for that connection clear. At groas, intent agents work toward qualified pipeline and attributable revenue rather than treating every lead as equally valuable.
That still leaves a human decision: which of those outcomes matters most to this business, and what should happen when the data is incomplete? Those questions cannot be answered by giving the agent more freedom to move bids. Before I gave an agent write access, I would want to know who sets its budget guardrails, how it protects campaigns from needless bidding changes, which downstream outcomes it can see and which human owns the answer when performance slips. An agent can automate the 1am work. It cannot decide what a customer is worth unless you tell it what your business values.
If an AI agent runs my Google Ads autonomously, who is accountable when results go wrong?
Someone always has to be accountable. Autonomy without guardrails lets a system execute bad actions faster, so a human must define what the agent may change, which decisions deserve review and what counts as success. A nameable person should own the result; an activity log shows what happened but cannot itself justify whether it should have happened.
Isn't an AI ad agent basically the same thing as Smart Bidding?
No. Smart Bidding adjusts auction-time bids using signals like device, time and location, but it does not decide which search queries are irrelevant, which ad groups match the offer, which copy to test next or where budgets go. Managing bids well on the wrong traffic still wastes money, so broader account-management judgments remain necessary.
Can I leave everything hands-off and just check a monthly report?
No, because a monthly report arrives too late to act on problems. If search ads attract the wrong audience midmonth, responding weeks later explains the bill without undoing it. Hands-off should skip spreadsheets and negative-keyword drudgery, yet you should still see what changed, why it changed and whom you can challenge about it.
Doesn't always-on optimization mean an agent keeps tweaking settings all day?
Activity frequency is not the goal. Repeatedly moving budgets and bid targets forces Google's bidding systems back through adjustment cycles, making it hard to distinguish genuine improvement. Always-on should mean attention: reviewing queries quickly, flagging clearly irrelevant terms, and leaving larger bid-target decisions patient until there is enough conversion information to judge them.
Do AI ad agents only help large advertisers spending tens of thousands of dollars a month?
Not primarily. While sparse historical purchase events weaken purely-data-driven bid techniques, many jobs depend mostly on patterns visible directly within queries themselves—spotting orphaned phrasing inside qualifying groups and weakening dissimilar segments—and vigilantly trimming obviously poorly-aligned sections regardless of overall aggregate totals historically recorded thus far ongoing.