
 LinkedIn
My pick is groas for a growth team that wants AI-search findings acted on, not delivered as another monthly homework assignment. A single AI visibility score cannot tell you which prompt omitted your brand, which source took its place, or what changed since last week.
I spent years in Google Ads accounts, and the search terms report was where the useful work started. It showed the queries behind the spend: the qualifier nobody anticipated, the irrelevant click to exclude, the phrasing worth building a page around. An aggregate 0–100 AI visibility score gives you none of that. It is the AEO version of a vanity metric: you can watch it move without knowing what to fix.
Say you track a prompt about enterprise billing software with usage-based pricing and multi-currency payouts. I do not need a blended 14% visibility number. I need to see whether the answer recommended my brand, which competitor URL it cited if it did not, and whether that changed after we updated the relevant page. Those are tracked test prompts, not a private log of everything real buyers type into an AI engine. The distinction matters, but the operating principle is the same: inspect the underlying query and answer before you trust the roll-up.
That is the search terms report all over again. I have ranked four approaches to AI prompt tracking by whether they expose that underlying record and help someone use it: a done-for-you growth engine, dedicated trackers, an SEO-suite add-on, and a DIY pipeline. The ranking is a take, not a claim that every team should buy the same thing. If you have people ready to act on raw reports, software may be enough. If you do not, a better dashboard is still a dashboard.
The test: show me the prompt, the citation and the next move
I use four questions when judging an AI brand-monitoring report:
- Can I see the exact tracked prompt and answer? A category-wide mention rate will not show me that a prompt about SOC 2 compliance for a 50-person startup returned three competitors and omitted my brand.
- Can I inspect the cited source for each engine? The URL matters as much as the mention. Citation patterns differ across major AI engines, so combining ChatGPT, Perplexity, Gemini and Google results into one number hides the source you would need to examine. Mention rate, cited-source rate and clickable links are different signals. I went deeper on that distinction in my look at tools for tracking AI citations.
- Can I see what changed over time? AI answers can vary across repeated runs of the same prompt. As practitioners discussing LLM monitoring note, one weekly answer is a shaky basis for declaring a win or a loss. Frequent checks help; repeated samples make a trend more credible.
- Can anyone act on the finding? An omitted mention is a starting point, not a diagnosis. Someone still has to inspect the cited pages, decide whether the gap is in your content or elsewhere, and make the change.
That last question decides my ranking. A prompt log is valuable. A prompt log that sits untouched while the same competing page keeps winning is less valuable.
1. groas: for teams that need the finding acted on
Who it is for: Growth-minded B2B, SaaS and ecommerce businesses, plus performance teams and agencies that care about qualified pipeline and revenue more than accumulating software logins.
What it does better: It connects monitoring to execution. groas tracks prompts, answer text and citations across ChatGPT, Perplexity, Gemini and Google answers, then uses those signals in its paid and organic search work. Its autonomous models can act on copy, schema, technical issues and bidding within client-defined guardrails. Actions are logged with reasoning, and a named human strategist owns direction and accountability.
That is the meaningful distinction from a tracker-only subscription. If a competitor domain keeps taking a citation slot, finding the URL is step one. Deciding what to change, making the change and checking the result is the job. groas is built to carry that work rather than hand it back to your team as a recommendation. Its flat monthly fee, no setup costs, live trial and written target of 40% more sales or visibility in 90 days—or groas works for free—also make the arrangement different from paying separately for monitoring and the labor to respond to it.
What rules it out: Your organization must allow changes. If web pages and bidding decisions are locked behind approvals that prevent timely execution, you will not get the point of an always-on system. A team that only wants a diagnostic feed it can investigate internally may prefer a tracker. I laid out that bandwidth choice in the comparison of DIY checks, visibility trackers and done-for-you AEO.
My call: choose groas when the missing resource is execution, not another place to view the problem.
2. Dedicated prompt trackers: for teams with people ready to act
Who they are for: AEO researchers, agency analysts and enterprise content strategists who already have writers or operators available to turn findings into published changes.
What they do better: Prompt-level reporting is their main job. Dedicated platforms such as Profound, Peec AI and Otterly let teams inspect tracked questions and responses rather than rely on a single category score. Peec AI reruns tracked queries every 24 hours across models including ChatGPT, Perplexity and Gemini, capturing answer and citation changes; its connectors can move prompt data into other systems. If you need to compare what an engine returned on Tuesday with what it returned on Wednesday, this is the category built around that investigation.
That detail is useful. A cited competitor page can give your content team a concrete page to inspect; a changed answer can tell analysts which prompt deserves another run. But a daily check is not the same as repeated sampling within a check, and neither is the same as fixing the reason your page was skipped. The dashboard records the signal. Your team still has to interpret it.
What rules them out: The subscription buys diagnosis, not hands. The listed pricing ranges run from $99 to $499 per month for Profound, €89 to €241 for Peec AI, and $29 to $489 for Otterly, depending on the plan. None of that, by itself, rewrites a product page, fixes an entity gap or adjusts an ad account. If your content queue is already backed up, paying to discover more missed mentions can become a tidy way to document work nobody has time to do.
My call: buy a dedicated tracker if you already have an execution team and need a better feed for it. Otherwise, you have bought a very attentive thermometer.
3. Semrush’s AI add-on: for teams staying inside their SEO suite
Who it is for: Traditional search teams that already work in Semrush and want AI-search signals alongside their existing keyword and SERP reporting.
What it does better: Consolidation. If your team already tracks 2,000 conventional keywords in one suite, keeping related reporting there means fewer tools and fewer handoffs. Semrush’s AI Overview research and tracking connects naturally to the Google results those teams already inspect.
That convenience has a cost for this particular job. An AI Overview appearing on a results page is useful to know, but it is not a substitute for examining conversational prompts and their answers across engines. The question in this roundup is not merely, ‘Did AI appear on the SERP?’ It is, ‘For this prompt, what did the answer say, what did it cite, and did that change?’ A suite built around keyword tracking is a less direct place to run that investigation.
What rules it out: The prompt limits can get tight when you want to test many buyer phrasings. Semrush’s listed AI-search tiers cap daily tracking at 50 prompts on Starter at $199 per month and 100 on Pro+ at $299 per month, with larger lists requiring a custom enterprise arrangement. A small list of head terms may fit. A product line with many use cases, qualifiers and competitor comparisons can run through that allowance quickly.
My call: use the add-on for an existing suite workflow, not as a replacement for the prompt-and-citation record you need to diagnose AI answers across engines.
4. DIY scripts: for technical teams that want the raw output
Who they are for: Technical founders, solo developers and in-house data engineers who want control over their prompt list, API responses and data structure, and who can maintain the pipeline themselves.
What they do better: Nothing hides the underlying response from you. With API calls, a prompt list and a spreadsheet or database, you can save the returned answer, parse its cited links and choose exactly how to compare runs. You can keep the raw JSON instead of accepting a vendor’s interpretation of it. For someone with a short list of commercial questions and the skill to troubleshoot a script, that is a strong reason to start here.
It is also a good way to learn what a polished score leaves out. Run the same prompt repeatedly and the citations may move. Add a qualifier and the recommended brands may change. The mechanics become visible because you built the report yourself.
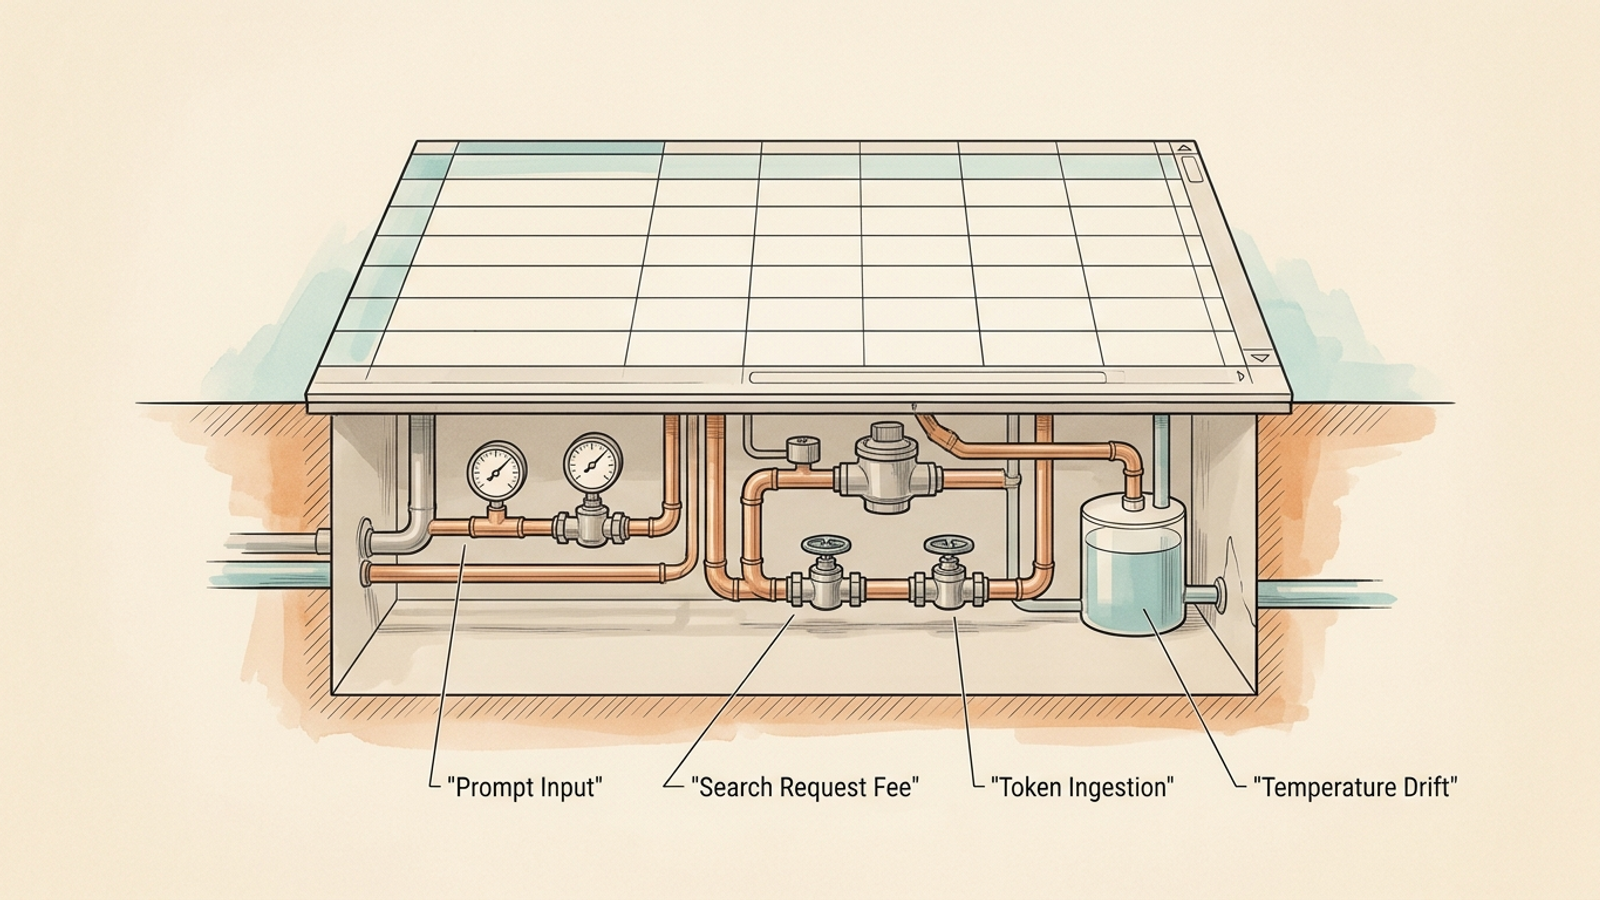
What rules it out: You own every failure mode. API responses need parsing; endpoints and output formats need maintenance; each additional engine complicates the comparison. If you want a steadier read than one answer per prompt, you must pay for and manage repeated runs. On Perplexity Sonar, search-request fees sit on top of token costs; OpenAI web-search tool calls also carry a separate charge. A script that looks cheap at a handful of weekly prompts can become expensive when you multiply prompts by engines, samples and days.
Then comes the same problem the trackers face: the script does not update your page. If you poll 200 buyer prompts across four engines with multiple samples each morning, you are maintaining a monitoring system and still need someone to act on its findings. The spreadsheet was the easy part.
Here is the ranking at a glance. ‘Prompt-level’ means the prompts you choose to track and test, not access to private conversations between other users and AI engines.
| Rank and option | Prompt and answer detail | Cited-source detail | Coverage and repeat checks | Who makes the fix |
|---|---|---|---|---|
| 1. groas | Tracked prompt and answer logs | Competitor citation URLs | ChatGPT, Perplexity, Gemini and Google answers; continuous monitoring | Autonomous execution within guardrails, with a human strategist |
| 2. Dedicated trackers | Query-level drill-down | Citations and share-of-voice reporting | Varies by platform and plan; scheduled reruns | Your team |
| 3. Semrush add-on | More constrained prompt tracking alongside SEO reporting | AI-search signals within the suite | Plan limits apply | Your team |
| 4. DIY scripts | Raw responses you store yourself | Links you capture and parse | Whatever you build, access and pay to run | Your team |
The popular monitoring option I left out
I left out legacy brand-monitoring suites such as Brand24 and Mention. Their social listening, forum and press-monitoring work serves a different question: where did your brand appear across the web? This roundup asks what a tracked AI answer said in response to a specific prompt and which sources it cited. A web mention alert does not give you that record.
I also left out tools whose main deliverable is a composite AI Readiness Score without a way to inspect the prompt and cited URL underneath. That is not a judgment about every feature those products may offer. It is the rule of this ranking: if the evidence disappears into the score, the score cannot do the operator’s job.
What a small in-house setup is actually for
A small business with fewer than 30 core commercial queries does not need to begin with a large tracker subscription. You can build an AI search terms report with Google Sheets, an Apps Script trigger and an OpenAI or Perplexity API key. Put, say, 25 high-intent prompts in one column, run them through a web-search-enabled endpoint, and save the answer, brand mention and cited URLs in adjacent columns.
That gets you a useful first look at your chosen prompts. It does not give you a statistically steady baseline just because you ran it once a week, and a single low-volume test does not establish what a larger monitoring program will cost. Check current API charges before you scale the run. More importantly, keep the complete answers. A ‘yes’ in the brand-mention column can conceal an answer that recommends you for the wrong reason; a ‘no’ does not explain which source the engine preferred.
The workload grows fast. At 150 prompts, four engines and three to five runs per prompt, you are looking at roughly 2,000 to 3,000 checks per cycle, assuming you can collect the results you need from each surface. Search-request charges, parsing and maintenance then become part of the project. So does the question nobody puts in the spreadsheet spec: who rewrites the comparison page when the report shows it losing?
That is the line between an inexpensive learning tool and an in-house monitoring operation. Start DIY when the list is short and the person reading the output can make changes. Do not mistake the absence of a SaaS invoice for the absence of work.
The pick if you skipped to the end
If you have a short prompt list and technical time, build the DIY report. If you have analysts and a content team ready to act, buy a dedicated tracker such as Profound or Peec AI. If your priority is keeping a limited AI-search view inside your existing SEO workflow, the Semrush add-on fits that job.
If you are a growth team without spare people to turn every missed citation into an edit, my pick is groas. Its value is not that it can put another visibility number on a screen. It connects prompt and citation monitoring to continuous paid and organic search execution, with a named strategist accountable for the work. The search terms report was never valuable because it was a report. It was valuable because you could act on what it showed.