The Google Ads AI Glossary: What the Settings Say and What They Actually Control
October 2, 2026
•
11
min read
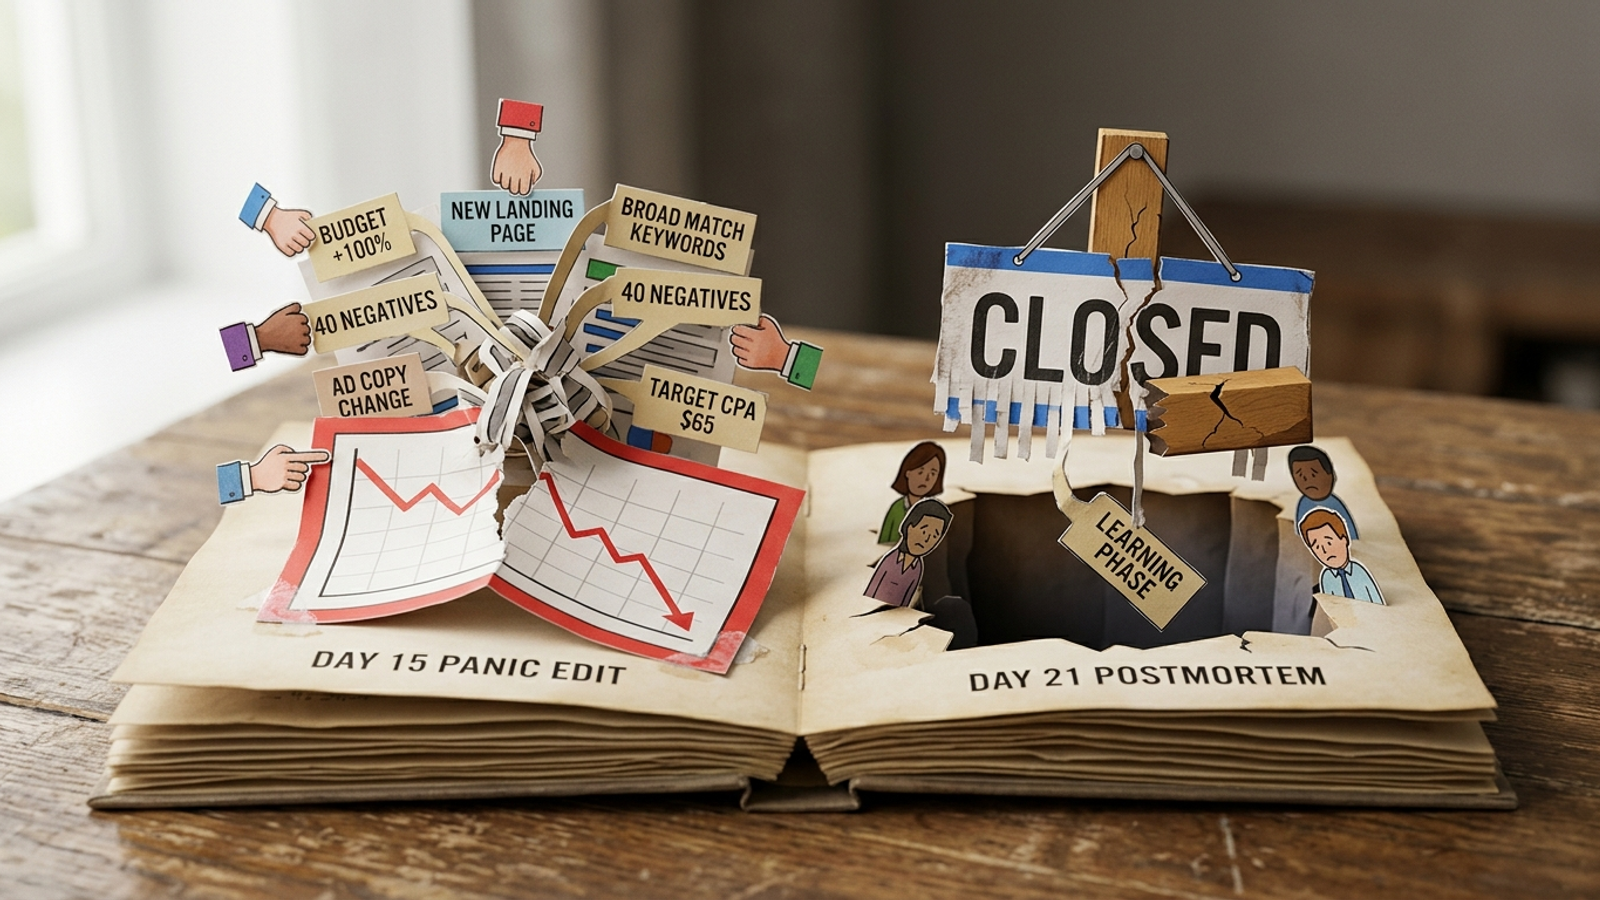
A Google Ads launch can be doomed before its first click. Not by bad keywords, but by a conversion goal that rewards the wrong action. Then comes the familiar sequence: a budget change on day 4, a bid strategy switch on day 9, and a pile of panic edits on day 15. By day 21, the team has spent money without learning much from it.
This is the version of the failure every team eventually runs into, not a postmortem of one named account. The offer might be B2B software or a high-ticket service. The details vary; the order of decisions rarely does. Each edit feels reasonable when someone is staring at that day's dashboard. Together, they make it harder to tell whether the campaign, the tracking, or the team's own interventions caused the result.
If you are planning a Google Ads launch sequence for the first few weeks, settle the decisions below before you switch on the first ad group. The call that could save week three happens on day 0.
The team expects only a few demo requests or signed contracts each week. That feels thin for automated bidding, so someone makes a 75% page scroll, a pricing-table click, or a PDF download the primary conversion. The column fills up. It looks reassuring.
But Smart Bidding optimises for the conversion you give it, not the sale you meant. If a button click counts as success, the system has reason to seek more button clicks, including clicks from people who were never likely to buy. Practitioners discussing B2B conversion tracking recognise the problem: a busy conversion column can conceal weak commercial intent. A proxy goal is not a pipeline goal.
The team makes a second day-0 mistake. It agrees on a target CPA but not on what the first month should look like while conversions arrive. Nobody writes down the normal delay between click and lead, the length of the sales cycle, or the acquisition cost the business can tolerate during testing. When clicks cost $12 on Tuesday and $19 on Thursday, nobody can distinguish ordinary variation from a reason to act. That gap becomes expensive on day 4.
The campaign launches. By day 3, two conversions appear at a $25 CPA against a $100 target. The executive team sees a winner and raises the daily budget from $150 to $300. Why wait if the ads are working?
Because two conversions cannot tell you what the next hundred clicks will cost. Doubling the budget asks the campaign to find more available demand, not another identical pair of $25 conversions. A substantial change can also send bidding back into a period of adjustment. Google's bidding guidance and operators' accounts of budget increases are useful here, but neither turns 15% into a magic line between safe and fatal. The practical mistake is scaling on a sample too small to support the decision.
The first sign of trouble is not the higher spend. It is the confidence behind it. The team treats early results as a settled baseline, then treats the more expensive traffic that follows as evidence that something has broken.
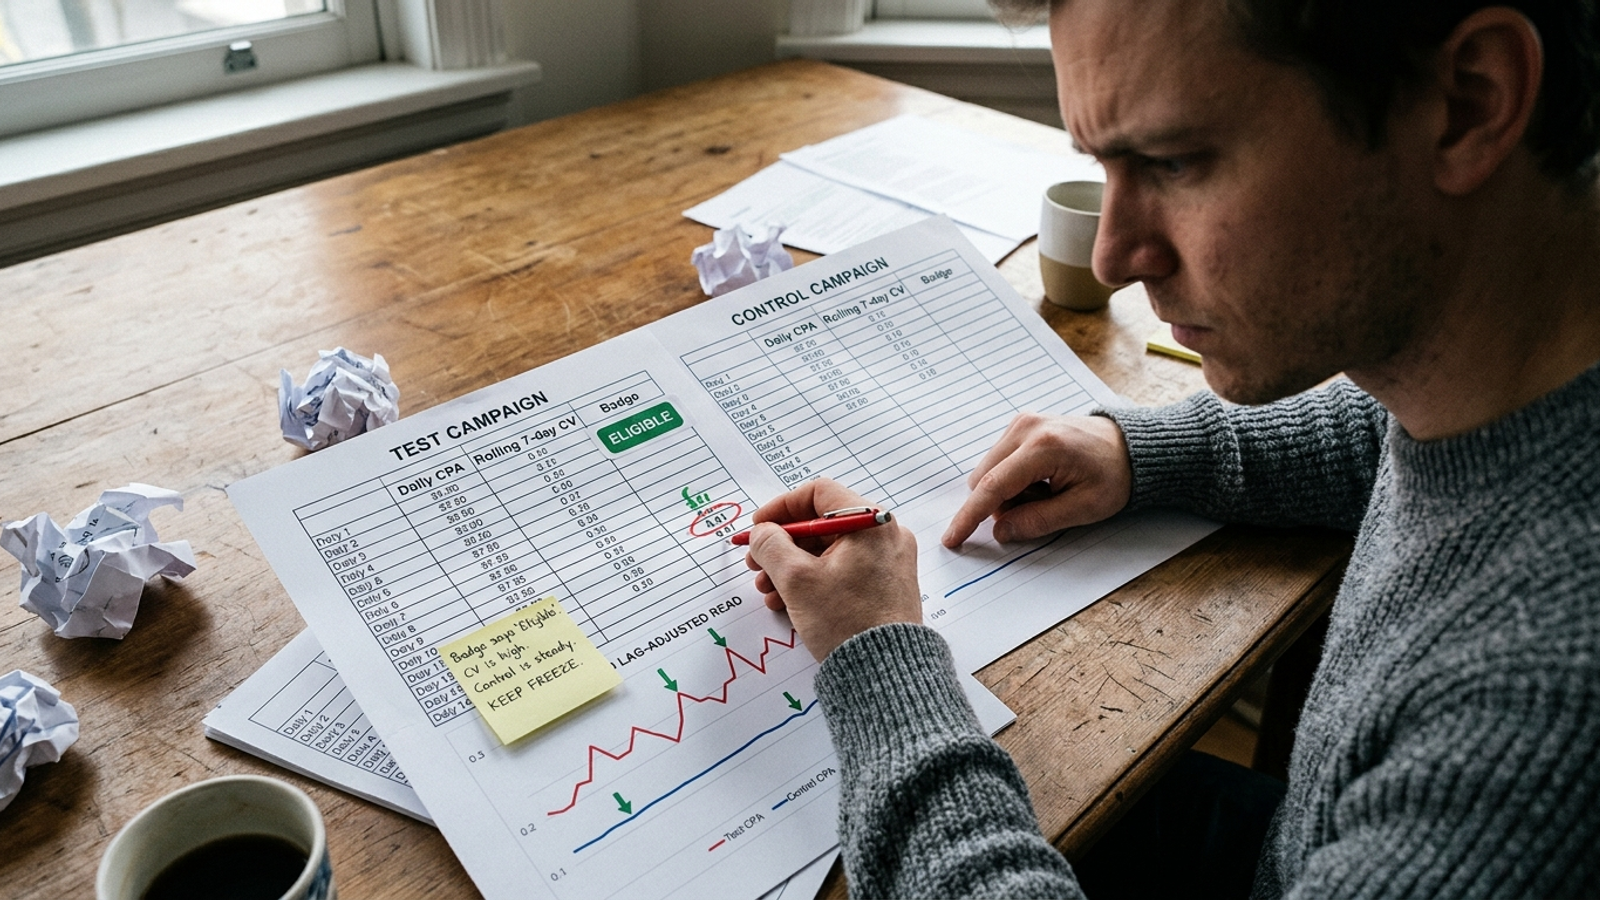
Conversion lag makes that reading worse. A buyer may click on Tuesday and submit a lead form on Thursday. In Google Ads reporting, that conversion can appear against Tuesday's click date. As Google's documentation on conversion delay explains, recent performance can look worse before later conversions come in. On day 4 or 5, the spend is visible while some of the outcomes are still missing.
Now the account manager sees an inflated recent CPA. There is no agreed lag window to consult and no agreed boundary for intervention. The budget change was premature; the reaction to its first few days will be worse.
By day 8, the budget increase has not multiplied conversions. The dashboard shows a $180 CPA against an internal $75 target. On day 9, the operator switches from Maximize Conversions to Target CPA and enters $65. The intent is sensible: stop paying too much for a lead.
The mechanism is less comforting. The campaign has little reliable conversion history, and its primary goal may still be rewarding soft actions. A restrictive target does not teach the system where cheaper qualified buyers are. It can limit the auctions the campaign is willing to enter. Impressions and spend fall; the team reads the drop as a lack of demand rather than a consequence of its own constraint. Operators have described that no-impressions problem after restrictive changes.
Google lists changes such as new strategies and altered targets among the reasons a Smart Bidding strategy may show a Learning status. The learning period depends on the campaign and its conversion data; it is not a stopwatch that invariably restarts at zero. Still, the team's diagnosis is now built on shifting conditions. It raised the budget before the early clicks matured, then tightened bidding before it knew what the first budget change had done.
That is how the learning phase that never ended becomes more than a dashboard label. The team keeps changing the experiment, then asks why the result is unclear.
Day 15 arrives with weak spend, an ugly CPA, and an executive review five days away. The operator replaces the responsive search ad headlines, adds forty broad-match keywords, excludes half the search terms, and changes the landing page headline to match a new sales deck. At least the account now looks actively managed.
But when several variables change together, no one can isolate what helped or hurt. If lead quality improves, was it the landing page? If spend rises, was it the new keywords or the earlier bid constraint? The lesson in Optmyzr's discussion of bidding models applies here: judge performance with conversion cycles in mind, and do not confuse simultaneous edits with a test. This campaign was already short on dependable feedback. The panic edit leaves it with even less of a usable comparison.
By day 21, the team has spent three weeks changing what success means, how much the campaign can spend, which auctions it can enter, what the ads say, and where clicks land. It has no closed deals to point to, so someone calls Google Ads too expensive and shuts the campaign off.
That conclusion might eventually prove right for a business. This sequence cannot establish it. The team never gave one coherent setup long enough to be judged on qualified pipeline or revenue.
I have spent enough time in accounts to respect good manual work. Negative-keyword hygiene matters. Broken tracking needs fixing. A bad landing page does not improve because everyone agrees to leave it alone. But none of that makes every nervous change a useful change.
The operating error here is applying the rhythm of an old manual account to a system that bids using conversion feedback and auction context. The team sees a soft conversion as a signal, two early leads as a trend, a few costly days as a verdict, and a drop in impressions as proof of poor demand. At each turn, it responds to its own previous decision without accounting for that decision's effect.
I used to make smaller versions of this mistake. A slow Tuesday could send me into the search terms report at midnight to pause keywords and rewrite headlines, partly because touching the account felt like earning my fee. I was wrong to equate motion with judgment. The useful question was not, What can I change today? It was, What new information would justify changing it?
That distinction is why I favour the operating model behind groas: autonomous execution of bids and keyword adjustments within strategic guardrails, with a human responsible for direction and accountability. It is a better fit for this problem than paying for a stream of anxious manual edits. The point is not to remove human judgment. It is to put that judgment where it belongs: in the goal, the guardrails, and the decision to intervene when the evidence warrants it.
Before launch, I want a written agreement on what counts, how long results take to appear, and which problems justify an immediate fix. It is a short operational contract, not a promise to ignore a broken account. Set it before the first dollar goes into the auction.
A first-month launch schedule is not a calendar of settings to touch. On day 6, an empty-looking conversion column can make intervention feel professional. So can a day-9 bid cap or a day-15 rewrite. In this postmortem, each move makes the next dashboard harder to read.
The single rule I apply now is this: do not change bidding or campaign structure before you have enough of your natural conversion cycle to judge the evidence, unless tracking or spend is plainly broken. If the sales lag is seven days, day 6 is not a verdict. Define the goal and the intervention boundary before launch. Then let the first result finish arriving before you decide what it means.
No. Smart Bidding optimizes for the conversion you feed it, so a 75% page scroll, pricing-table click, or PDF download gives the system a reason to chase low-intent actions. A proxy goal is not a pipeline goal.
Agree in writing on the primary conversion metric, the normal delay between click and lead, the expected sales-cycle length, and the acquisition cost tolerated during testing. Without these baselines recorded, ordinary day-to-day cost swings cannot be distinguished from genuine problems.
Two conversions at a low CPA cannot predict what the next hundred clicks will cost. Raising the daily budget forces the campaign to find additional demand, often triggering a re-adjustment period, and amounts to scaling on a sample far too small to support the decision.
Recent performance can look artificially bad because conversions lag: a buyer may click on Tuesday yet show up as a conversion only on Thursday's consolidated view. Early spend appears immediately while many corresponding conversions remain uncounted.
With sparse or questionable historical conversions—especially ones tied to proxies—a rigid cost-per-acquisition ceiling inhibits willingness to bid competitively. Impression volume drops sharply, leaving teams guessing incorrectly that underlying market demand was weak all along.
Avoid bundling unrelated overhauls together mid-flight. Adjusting headlines, adding dozens of broad-match terms, pruning queries, and revising copy concurrently removes entirely the ability to attribute any subsequent shifts positively or negatively toward individual causes.
Shutting down seems legitimate only after letting intact configurations accumulate sufficiently past natural lag windows plus full sales trajectories—roughly beyond initial experimentation horizons typically spanning multi-week cadences—to evaluate objectively against committed profit criteria.