A free Google Ads grader can put a failing grade and a five-figure waste estimate on an account before anyone checks whether its leads become customers. I’m tearing down the familiar report popularized by the WordStream Google Ads Performance Grader and echoed by tools marketed as an “AdWords Grader” or Adsgrader: the alarming score, the tidy benchmarks, and the few raw fields I’d actually keep.
The typical exchange is simple. You grant account access, wait for an automated scan, and receive a report with red warnings and a prompt to talk to someone about fixing them. If you run the account, that PDF can turn an ordinary Tuesday into a meeting. The problem is not that every flagged issue is fake. It’s that graders can score what an automated query can count, then present those scores as a diagnosis of business performance. They cannot tell whether a click produced qualified pipeline or closed revenue.
Before the first page: the lead form sets the terms
What the report can see, and what it cannot
Agency teardowns of the WordStream audit model describe its role as top-of-funnel capture for managed marketing services. The mechanics make sense for that job: connect an account, query its recent activity, and turn the results into a readable report. An automated scan can count edits, inspect search terms, and identify missing settings. It cannot read your margins, verify your lead-to-close rate, or distinguish an enterprise buyer from someone looking for a free template just because both submitted a form.
That gap matters on every page that follows. Read the report as a set of prompts to investigate, not a verdict on your media buyer. Start where the report starts: with the grade.
Page one: the letter grade makes the sale
Verdict: filler
The overall grade gets the prime position, often in a red or orange badge. A C-, a D, or a score such as 42 out of 100 looks conclusive. It is not. A single mark compresses settings, activity, and benchmark comparisons into something that resembles a school report card, without showing how those ingredients connect to your cost per acquisition.
That presentation also suits a lead-generation tool. An “A” gives you little reason to book a call; a “D” gives you a problem to discuss. I would not infer from a low grade that someone deliberately manipulated your result. I would ask what the formula rewards. Google’s native Optimization Score likewise rewards adopting its recommendations. A recommendation can be worth reviewing without being the right move for your account.
Consider “Account Activity.” WordStream’s discussion of its grader methodology describes scoring how actively an account is managed. More keyword, bid, or ad-copy changes can look better to the grader. But if a stable Smart Bidding campaign is delivering qualified pipeline at a predictable acquisition cost, leaving it alone may be the sounder decision. A scan sees fewer edits; it does not see the reason for them.
Verdict on the overall grade: filler. Find out which underlying fields pulled it down, then set the grade aside. Chasing a generic template is not the same as improving revenue. That is also the problem with treating a grader score as a campaign fix.
Page two: Quality Score becomes a budget prophecy
Verdict: misleading
Next comes an impression-weighted Quality Score, often paired with an estimate of how much your clicks could cost if that number improved. The calculation gives more weight to keywords with more impressions, producing one account-level figure that is easy to compare with a benchmark. WordStream’s discussion of Quality Score and cost per conversion supplies the appealing premise: improve the score and the economics should improve with it.
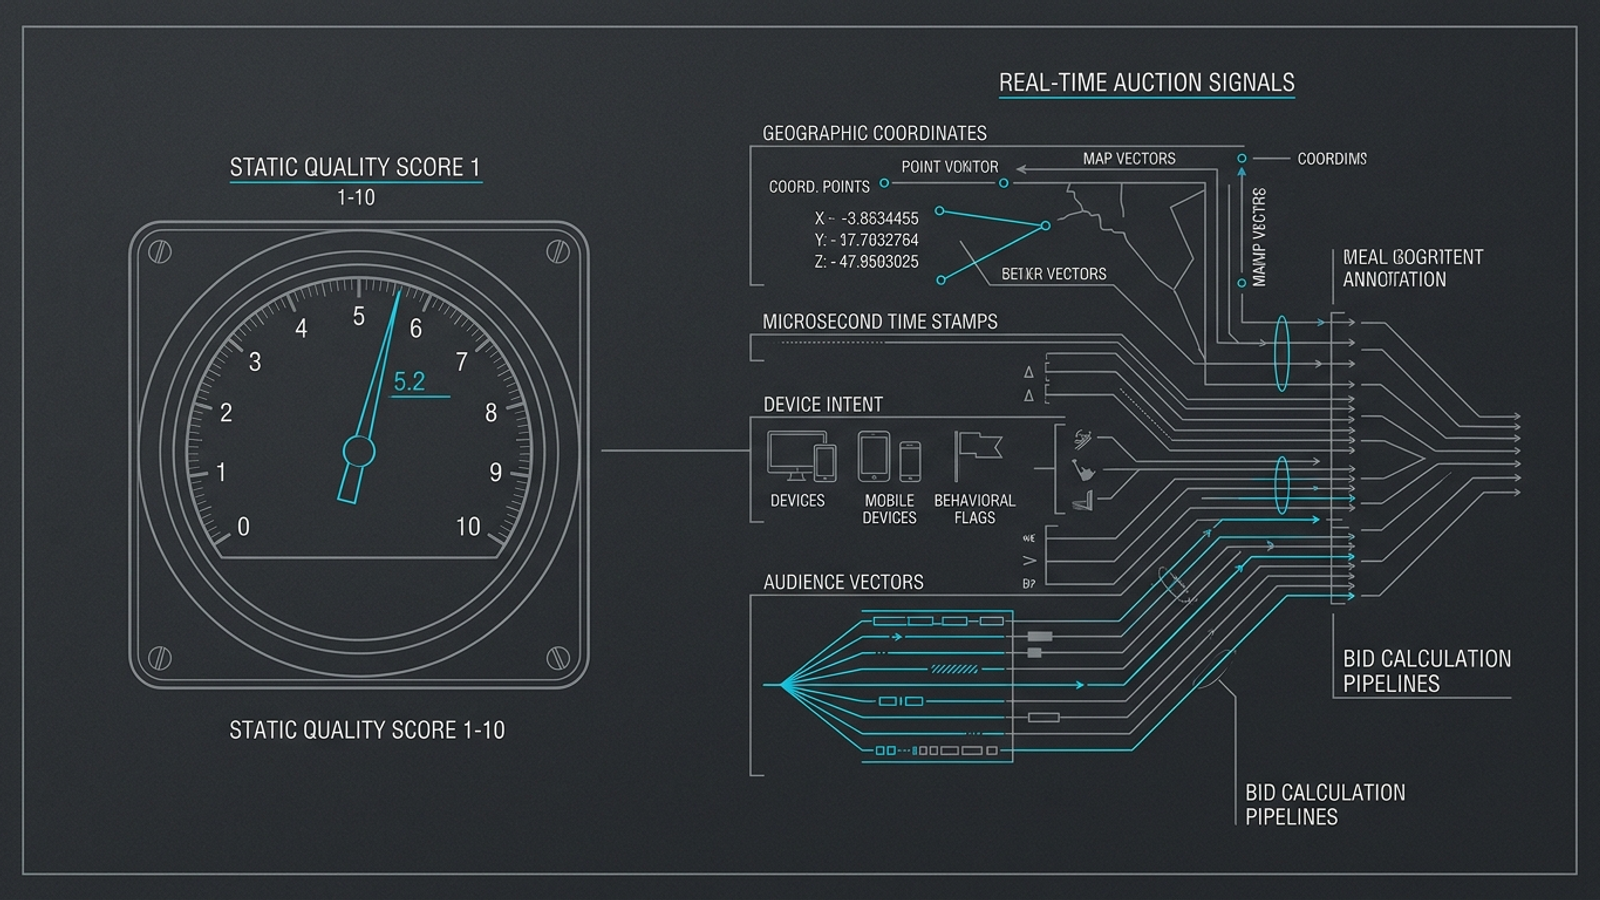
The leap is from a diagnostic proxy to a prediction about your bill. The visible 1-to-10 Quality Score summarizes keyword-level signals; it is not a fixed price tag on every future click. Auctions vary by the search, the person, the context, and the competition at that moment. Smart Bidding makes decisions in that changing environment, not by taking your report’s account-wide average as an instruction.
I still look at Quality Score when an ad group loses traction or click costs jump. Weak ad relevance or a poor landing-page match can be a real problem. But I would not rewrite dozens of ads to move an account average from 5.6 to 7.0 while ignoring which searches produce customers. Exact-match phrasing can make a dashboard prettier without making an offer more persuasive.
Verdict on Quality Score: misleading as a campaign-health grade, useful as a clue within a specific problem area. Check the affected queries, ads, and landing pages before doing the work. Our breakdown of grader scores and what to measure instead goes further on that distinction.
Page three: “wasted spend” gets the biggest type
Verdict: misleading
The report’s most alarming figure is often “Estimated Wasted Spend.” Imagine spending $20,000 a month and seeing a claim that $8,400 went to waste over the last ninety days. A common way to generate that number is to add up spend on search queries that recorded clicks but no conversions in the reporting window. If a query cost $45 across twelve clicks and logged no primary conversion, the whole $45 goes in the waste column.
The arithmetic is neat. The diagnosis is not. A non-brand search may introduce someone who returns later by another route. A phone inquiry may not reach the tracked conversion action. A longer consideration period may extend beyond the report’s window. Discussion of PPC budget-waste audits points to these limits of treating non-converting queries as a complete waste calculation. Some exploratory spend is also how a campaign encounters new search patterns. None of that excuses genuinely irrelevant traffic; it means zero recorded conversions is a reason to inspect a query, not proof that every dollar on it was lost.
This is the number I would be most careful about forwarding without the underlying terms. A large total can make a team look reckless while concealing a mix of poor matches, incomplete tracking, and searches that simply have not paid back yet. Practitioners discussing audit-poaching tactics recognize why that figure makes such effective sales material.
Verdict on wasted spend: misleading. Ask for the query-level costs and the conversion window. Investigate the expensive mismatches; do not treat the total as recovered cash waiting for someone to flip a switch.
The benchmark panel: a race against an unknown field
Verdict: filler
A later panel may compare your click-through rate and impression share with unnamed “industry peers.” Perhaps it shows your 2.4% CTR beside a 4.8% average, then warns that budget limits cost you 45% of available impressions. Those figures look precise. The comparison may still tell you very little.
Brand and non-brand searches behave differently. An advertiser buying searches for its own name can post a much higher CTR than one prospecting on unfamiliar, competitive terms. Pool those campaigns into one industry average, and the non-brand advertiser looks weak for doing a harder job. A benchmark without a comparable campaign mix is not a target.
“Search Lost IS (Budget)” needs the same care. A budget limit can keep you out of valuable auctions, but buying more impressions is only useful if the additional auctions can meet your acquisition target. On broad, competitive terms, I would check the cost and quality of the traffic already arriving before treating lost impression share as an instruction to spend more.
Verdict on CTR and impression-share benchmarks: filler as account-wide grades. Use your own campaign segments and economics to decide whether there is room to grow. An opaque peer average cannot make that call.
The search-terms appendix: one page worth opening
Verdict: conditionally useful
The first place I slow down is the raw search-terms inventory. In a neglected account, it can reveal obvious leakage: a residential contractor paying for DIY searches, a B2B software company matching queries for free courses, or a local service business appearing for job openings. A notice that nobody has reviewed negatives in ninety days is worth checking, too.
The grader can show the terms. It cannot decide their value from a negative-keyword count alone. As negative-keyword audit discussions note, more negatives do not automatically mean less waste. A long list of narrow exclusions may leave the underlying thematic mismatch untouched; an aggressive list can also block adjacent searches that were worth testing. The visible search-terms report is not a complete record of every query, so a scan of it has limits before the grader applies any judgment.
Verdict on search terms and negatives: conditionally useful. Look for recurring, costly themes that plainly do not fit the offer. I would rather add a few defensible exclusions and check their effects than paste in a thousand terms to impress a PDF.
After the appendix: what the report never inspected
Verdict: the missing checks matter most
By now, the report has spent pages on grades, benchmarks, and counts. It has not established whether its conversion data is trustworthy. That is the most consequential omission, because every reassuring CPA figure depends on what the account calls a conversion.
A useful audit starts with conversion tracking integrity: which actions are primary, whether tags fire where they should, and whether reported leads connect to the outcomes the business cares about. Professional Google Ads audit protocols put those checks up front. If a primary tag fires on a generic page load or a thank-you page records an action twice, the account can appear to generate cheap leads that do not exist. A grader reading account data may praise that apparent efficiency. It cannot verify the event against your sales records just by printing a score.
It also cannot judge the offer the way a buyer does. An ad may promise something its landing page barely mentions. A bidding target may favor the wrong sort of inquiry for the business. Those are not punctuation or settings problems; they require someone to trace the path from query to ad to page to qualified customer. That is why a 10-point account audit framework has to examine post-click economics, not merely whether boxes in the account are ticked.
Practical takeaway: validate the conversion before you trust any score built on it. Otherwise, even the report’s apparently good news may be an artifact of the tracking setup.
Overall verdict: keep the evidence, bin the grade
When the grader finishes, I would skip its executive summary and cross out three headline numbers: the overall letter grade, the account-wide Quality Score, and the “Estimated Wasted Spend” total. Each compresses a complicated decision into a neat answer the report cannot support on its own. None tells me whether a campaign produces profitable customers.
I would keep three things from the underlying data, provided the report actually includes them:
- High-cost search queries with no recorded conversions. Read the terms, not the grader’s waste label. Look for clear thematic mismatches such as job seekers reaching a service campaign or consumer searches landing on a B2B offer. Then check the tracking and time window before excluding anything.
- Search Lost IS (Rank) on high-intent terms. If important campaigns lose eligible impressions because of rank, inspect bids and ad relevance. The figure identifies a place to investigate; it does not tell you which lever to pull.
- Device and geographic cost splits. Compare spend and CPA across segments. If mobile takes 65% of the budget while converting at a third of desktop’s rate, that difference deserves a closer look at traffic, experience, and conversion quality.
The grader’s sales pitch usually comes next: here is a list of manual chores, and here is a team that can do them. Some accounts need that work. What I object to is treating the list itself as a strategy, then charging for repeated mechanical maintenance as if every keyword edit were a fresh insight.
At groas, the alternative is continuous autonomous execution on search queries, budget leaks, and bids, with a dedicated strategist responsible for commercial direction and guardrails. That is a stronger operating model than handing a weekly chore list to an agency because a PDF gave the account a D. My overall verdict on the free grader is narrow: keep its raw clues, discard its claim to have diagnosed the business. If one lands on your desk, verify the conversions, inspect the costly queries, and let actual customer outcomes decide what happens next.