

 LinkedIn
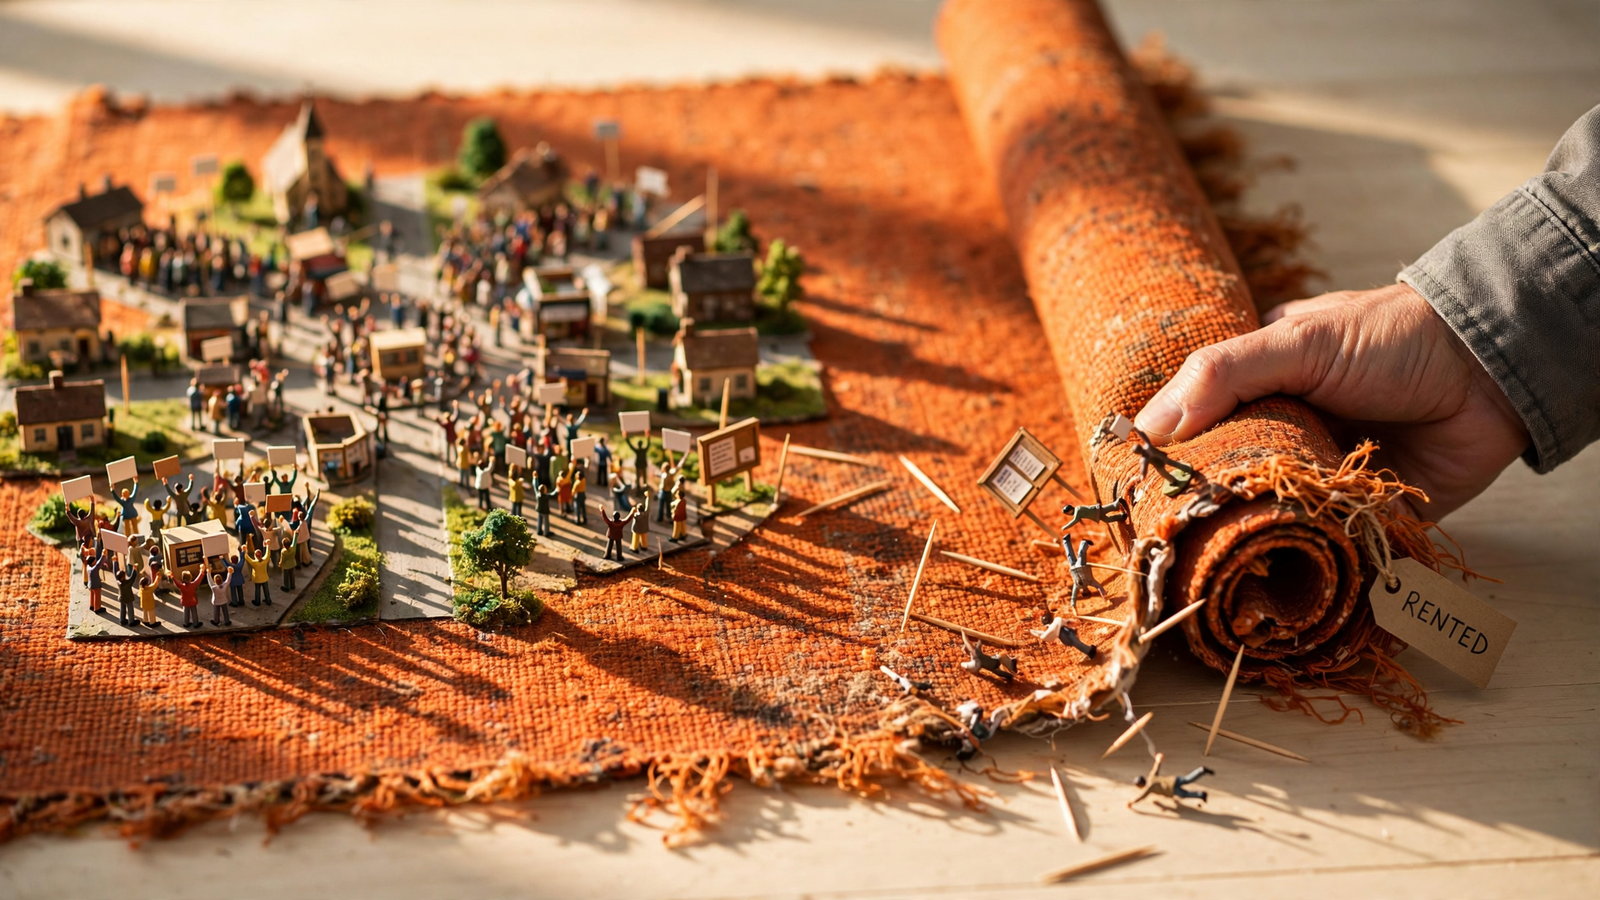
I chose Otterly’s published Reddit GEO experiment because it answers a question most AI visibility pitches avoid: what survives when the third-party channel disappears? Over 60 days, the team built four test subreddits to generate AI search visibility. Then Reddit removed all four in one administrative action, taking 240 posts, 1,485 subscribers and 20 keyword rankings with them; Otterly reports losing 474 AI citations, too.
That is the artefact: not a screenshot of a win, but an accounting of what disappeared. A vendor documenting its own failure is rare enough to deserve a close read.
My buying standard is simple. Citations can show that a tactic gained distribution. They do not, by themselves, show that it built durable discoverability. I want to know what remains after a channel goes away, and whether the visibility repeats across topics and over time. Otterly’s experiment makes that distinction painfully concrete.
The setup: four communities, manufactured engagement
Otterly starts with a specific inventory: four communities, 240 posts, 1,485 subscribers, 20 keyword rankings and 474 AI citations. The team seeded identical content in parallel communities, varied the engagement each received, and watched which versions AI answers picked up.
That gives the experiment a mechanism to inspect, rather than just a flattering chart. It also reveals the weakness before the ban arrives: the team was manufacturing activity on a platform it did not control.
The engagement treatments make that explicit:
- Version B: 10 replies plus 20 upvotes per thread.
- Version C: 50 upvotes with no comments.
- Version D: no upvotes and 50 comments, with automated bots also part of the experiment.
Otterly discloses those treatments and itself identifies the activity as content manipulation under Reddit Rule 2, which requires authentic participation and prohibits spam and manipulation.
My verdict on the setup: this was not community participation. It was a lab built on rented land, with the social-proof dials turned by hand. I respect the decision to publish what happened after it broke. That transparency does not make the method a sensible service to buy.
The distinction matters before looking at a single citation. A buyer needs to know whether a provider earns a recommendation or manufactures the appearance of one. Those are different products, however similar the report looks.
The ban: local control was not ownership
Next comes the failure. Otterly stresses that this was not a moderator removal or shadowban, but a community-level administrative ban that removed every thread and URL. The team had created and moderated the communities. That control did not protect them from an action above the moderator level.
This is the detail I would underline in a proposal review. A provider can run a room, fill it with content and show you its subscriber count without owning the underlying asset. The platform still holds the switch.
The citations did not necessarily disappear at the instant the source pages did. Otterly describes them lingering briefly in cached answers before disappearing as well. That lag matters: an answer can keep pointing toward yesterday’s visibility after the source has already gone.
Moderator access is not ownership, and a lingering citation is not resilience. If the whole program sits behind one platform’s administrative decision, the buyer needs to see that dependency before paying for it.
The apparent success: 474 citations, but what did they establish?
The headline number is worth examining without either dismissing it or asking it to prove too much. Otterly counted 474 AI citations tied to its Reddit posts. That establishes reported pickup during the experiment. It does not, on its own, establish repeatability, durability or commercial value.
A citation points to a source. It is not an asset the advertiser owns. Once Reddit removed the source URLs, the experiment had no durable base beneath those citations.
My verdict: the experiment demonstrated distribution, not durable discoverability. If losing one channel removes the entire result, the service has a dependency problem that a larger citation total cannot fix.
There is a second distinction here: channel risk and assistant risk are not the same thing. Broader measurements cited alongside this debate show Reddit’s visibility moving differently across AI products. Otterly measured ChatGPT Reddit citations falling 73.4%, from 497 to 132 per day across 16 brand reports. In the same July-to-September window discussed by that source, Reddit’s share rose in AI Overviews by 16%, AI Mode by 24% and Perplexity by 86%.
Those figures are not a measurement of the four banned communities, and I would not use them to explain the ban’s effect. They illustrate a separate reporting problem: an aggregate can hide sharply different assistant-level trends.
A provider selling Reddit visibility should therefore show which assistants produced it. “AI citations increased” is not enough when the underlying platforms move in different directions. Keep the channel breakdown and the assistant breakdown visible.
The enforcement lesson is narrower than “Reddit is useless”
This case does not prove Reddit is useless. It shows what happened to a particular experiment built around manipulated engagement. Nor does it establish that every honest contribution will remain available indefinitely.
Reddit’s rules on authentic participation and manipulation sit above whatever control a marketer has inside a community. That is the relevant boundary. Creating the subreddit did not put Otterly outside it.
I would reject the manufactured-engagement playbook, not pretend the channel has no value. Third-party corroboration can support a program. It should not be the only thing holding the program up.
The measurement gap: a total is not a repeat rate
After the loss comes the harder question: how much confidence should a buyer have placed in the citation count before the ban?
The 474 figure is an experiment total. Without the underlying run counts, dates and distribution, that number alone cannot tell me how reliably a topic produced the brand, whether pickup improved over time, or how often the same questions missed it entirely.
Ask for the run count before trusting the citation count. A total without its denominator can look impressive while leaving the buying question unanswered.
Repeated-run research explains why this matters. SparkToro and Gumshoe ran 12 prompts 2,961 times and got the same brand list less than 1% of the time. SE Ranking ran 10,000 AI Mode keywords three times in one day and found only 9.2% URL overlap. AI Rank Lab reported median cited-domain overlap of 41% between consecutive runs, supporting its recommendation for weekly runs over weeks rather than one-off checks.
Those studies measure different things. I would not mash them into one universal volatility score. Their practical implication is the same, though: one observed answer is not a dependable reporting unit. A citation can disappear on the next run without a platform deleting anything.
The useful contrast is Grow and Convert’s B2B SaaS case study, which reports by topic area across ChatGPT, Perplexity, AI Overviews, Gemini, AI Mode and Claude. On one vertical prompt, the brand appeared in 16 of 44 runs, or 36% overall, but in every one of the last 12 runs.
That sentence gives me both the historical miss rate and the recent trend. Neither number has to hide behind the other.
I keep agency-reported evidence separate from independent tests. I read this as a reporting format worth copying, not proof that another account will reproduce the result. My verdict on Otterly’s headline count is similarly limited: it records pickup, but the count alone cannot establish stability. Demand topic groups, repeated runs and misses alongside hits.
Keep the citation line separate from the trial line
The same Grow and Convert case study separates visibility from commercial outcomes. It reports overall AI traffic rising about 1,900%, roughly 20x, and AI traffic to its articles rising about 750%, while attributable free trials rose about 75%.
That is a much more useful report than a traffic chart wearing a revenue label.
The authors also note that AI influence is not always click-attributable: someone can see a recommendation, then search for the brand in a new tab. That is an attribution limitation, not permission to treat every citation as an unrecorded sale.
Judge the trial line first; treat citations as a leading indicator, not the win. I want both on the page, with the distinction intact. The visibility tells me where discovery may be happening. The inquiries and trials tell me whether the program is producing something the business can use.
The method matters beyond the platform ban
Before turning this experiment into buying criteria, there is one more consequence to separate from the citation count. Manufactured engagement and fake customer endorsements are not merely reporting problems.
The FTC’s final rule addresses fake reviews and testimonials that misrepresent who the reviewer is, whether they used the product, or what their experience was, including AI-generated fakes. That does not make every experimental comment the same kind of conduct. It does mean that a provider pretending to be a customer can create exposure beyond losing a Reddit account.
My verdict: the earning method belongs in the proposal, not in the postmortem. I would want a written explanation of how mentions are generated and where automation or incentives touch the process. A citation total tells me nothing about that risk.
Three things I would require before buying
Otterly’s experiment is useful because it turns a vague purchasing question into a concrete inspection. Say I am spending $20k a month and evaluating ongoing SEO and generative engine work. I want three documents before I want a forecast.
1. A split sheet: what stays, what can disappear
The first column lists work on my site that I keep if the engagement ends:
- Catalogue and product pages.
- Product data and category copy.
- Answer-shaped sections that machines can quote.
The second lists rented distribution: Reddit, forums, press mentions and third-party lists.
If the first column is thin and the second holds 80% of the promised citations, I pass. That is an illustrative buying threshold, not a result from Otterly’s test. The point is to expose the dependency before a dashboard buries it.
Build the owned base first, then earn corroboration that can disappear without taking the whole program with it. The split sheet should make that order obvious.
2. An earning disclosure: who posts, who votes, who is accountable
Otterly disclosed its engagement treatments in the postmortem. As a buyer, I want the method before I pay:
- Who writes the posts?
- Which accounts publish them?
- Are votes or comments automated or incentivized?
- What happens if a community flags the brand?
- Who can stop a tactic that puts the brand at risk?
If the answers are vague, I treat the proposal as Version B with better formatting. What the deck calls community activation may just be paying someone to pretend to be a customer.
This is why I favor groas’s model of autonomous execution tied to a named strategist who owns the outcome over rented-room tricks. The strategist can reject a tactic that risks the brand, and the action log shows what ran. Automation needs accountable direction, not a disguise.
3. A weekly topic report: repeated observations beside business outcomes
The third document pairs visibility with money. I want topic groups rather than cherry-picked prompts, run counts with dates, mention rates per run, and misses printed next to wins. I also want the assistant breakdown, so one platform’s gain cannot conceal another’s decline.
Then, on the same page, I want qualified inquiries and attributable trials for those topics. The two sets of numbers should stay separate enough to inspect and close enough that nobody can quietly substitute one for the other.
That is the useful reporting lesson from the Grow and Convert example. The same insistence on business outcomes and retained strategic control is why I point readers toward this groas B2B SaaS case study on cutting CPL without handing off control, rather than treating a visibility chart as the final deliverable.
A report that stops at citations has stopped before the business question. Ask what the mentions contributed, and accept an honest attribution gap before a convenient revenue claim.
Verdict: keep the disclosure, reject the dependency
The artefact holds up as a warning and fails as a playbook. Otterly reported citation pickup from manufactured Reddit engagement, then documented what happened when administrators removed the communities beneath it. The loss exposes a dependency that the original citation total could not resolve.
I would judge an AI visibility service partly by what remains after a channel disappears. Repeated, topic-level measurement makes that judgment more useful than a screenshot: it shows whether visibility persists, where it fails and whether business outcomes move alongside it.
What I would keep from Otterly’s experiment is the honesty of publishing the loss with exact counts, plus the attempt to distinguish how different engagement treatments affected pickup. What I would not buy is a service whose result depends on manufactured participation in rooms the provider cannot protect.
At groas, the work I trust starts on the client’s own catalogue and pages, runs continuously with actions logged, and leaves one named strategist responsible for the pipeline number. Ask for the split sheet, the earning disclosure and the weekly topic report. If a provider cannot show all three, the citation screenshot does not rescue the pitch.


