

 LinkedIn
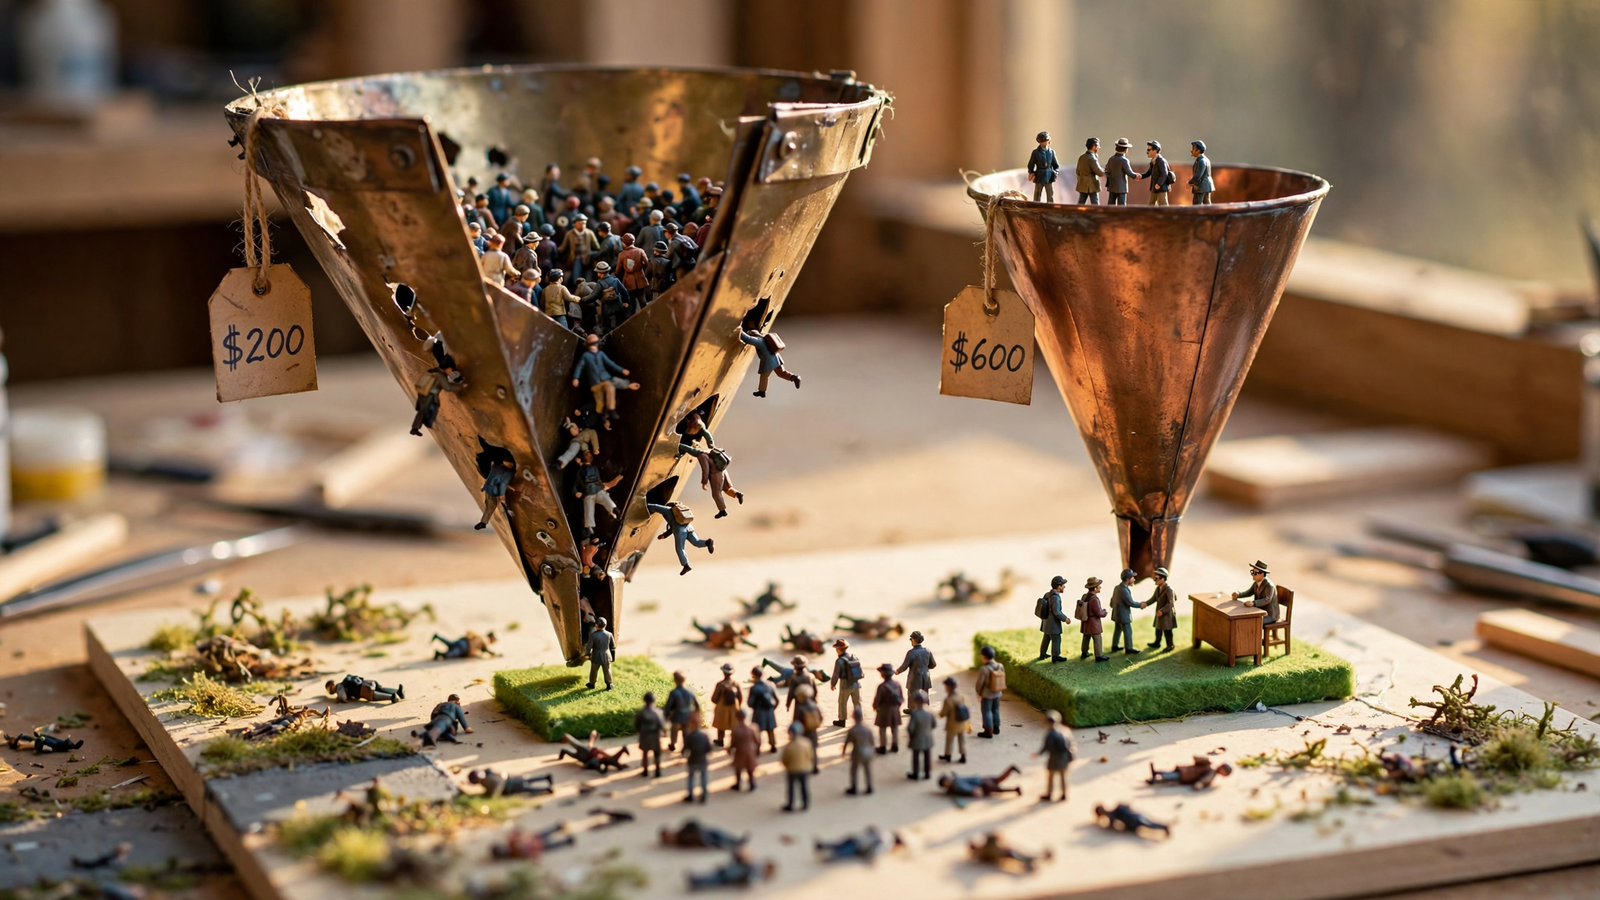
A $200 ChatGPT demo can cost more than a $600 one. If fewer of those cheap meetings become real opportunities, the campaign that wins the dashboard can lose the budget argument.
I used to report cost per demo like it settled the question. I was wrong. In B2B, especially with a long sales cycle, the first conversion is only the first filter.
Take two explicitly hypothetical campaigns, not forecasts. Campaign A books demos at $200 each, and 10% become accepted opportunities. Campaign B books at $600, and 50% become accepted opportunities. A buys cheaper meetings. B buys cheaper opportunities.
Everything that follows rests on one fact: acquisition cost depends on how many prospects progress, not just what the first conversion costs. I want to follow those two campaigns through the funnel before deciding which deserves more money.
Divide demo cost by acceptance rate
Start with ten booked demos from each campaign. The budgets differ; the calculation puts them on comparable terms.
| Hypothetical campaign | Cost per booked demo | Spend for 10 demos | Accepted opportunities | Cost per accepted opportunity |
|---|---|---|---|---|
| A | $200 | $2,000 | 1 | $2,000 |
| B | $600 | $6,000 | 5 | $1,200 |
Campaign B spends more to book each meeting. But half its meetings become opportunities, versus one in ten for A. That difference more than pays for the higher booking cost.
The calculation is simple:
Cost per accepted opportunity = cost per booked demo ÷ booked-to-accepted rate.
For A, that is $200 ÷ 0.10 = $2,000. For B, it is $600 ÷ 0.50 = $1,200. The dashboard crowns A if it stops at bookings. The opportunity calculation favors B.
This is familiar cheap-lead arithmetic: 100 leads at $30 with a 5% close rate cost $600 per client, while 40 leads at $60 with a 20% close rate cost $300 per client. A lower price at the entrance does not guarantee a lower price at the exit.
I keep the example extreme so the mechanism is visible. A loose message can attract curious clicks. Curious clicks can fill calendars. Calendars do not automatically become pipeline.
There is one more limit to respect: B has won the opportunity comparison, not yet the customer comparison. Accepted opportunities still have to close. If the campaigns produce different opportunity-to-customer rates, the ranking can change again.
My first checkpoint is therefore narrow: cost per demo prices a meeting; cost per accepted opportunity prices a chance to sell. Neither is automatically customer acquisition cost.
Match the spending clock to the sales clock
Now add time. The campaign spends this month, but the prospects may not buy until next quarter or the quarter after.
That delay makes an incomplete funnel look like a finished result. After 30 days, A can show ten cheap bookings while B shows fewer, more expensive ones. If neither group has had time to progress, declaring A the winner rewards calendar volume before sales quality becomes visible.
Long waits are ordinary in B2B. Published benchmarks put SMB sales cycles at 30–60 days, mid-market at 60–120 days, and enterprise at 6–9 months, with median demo-to-close around 84 days. Those are context, not a deadline for any particular buyer.
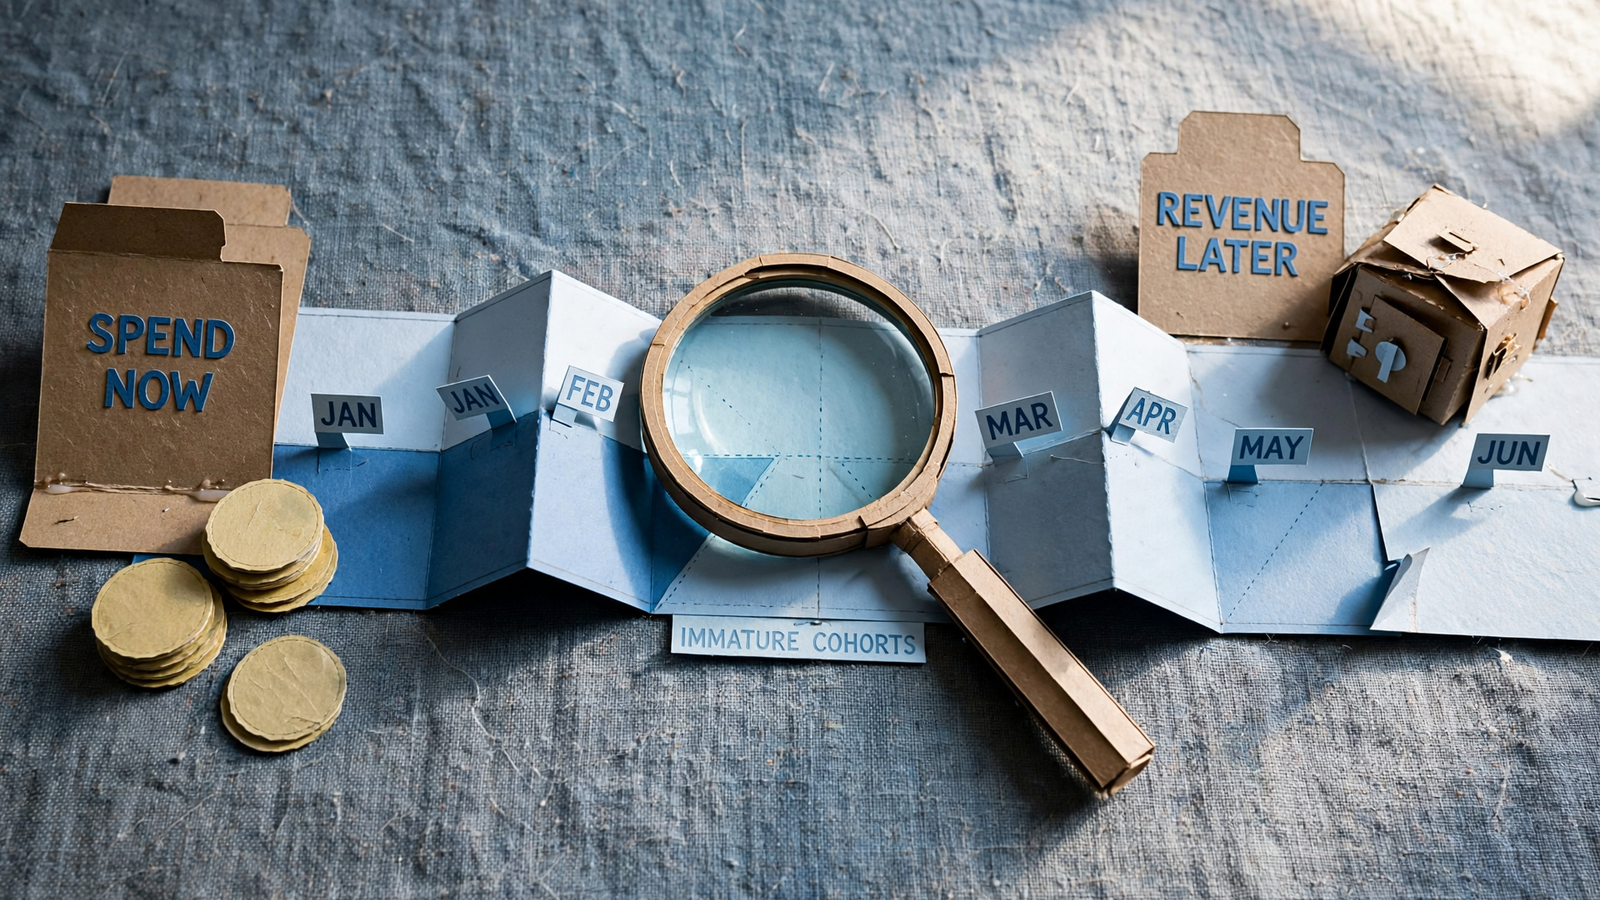
The reporting mistake is to put March spend beside March closed-won revenue and treat them as one group. March spend may belong to prospects who decide in June. March revenue may belong to prospects who clicked in December.
I use click cohorts: groups organized by when their starting click happened. Each group keeps its own spend and subsequent progression. The practical fix is to report by click cohort and label recent cohorts immature.
An older cohort may have bookings, attendance, opportunities, and wins to inspect. A recent cohort may have only bookings. That empty revenue column is unfinished evidence, not necessarily failure.
When the sales cycle exceeds the reporting window, compare cohorts at comparable maturity—not this month’s spend with this month’s revenue.
Track four stages without changing their definitions
To follow A and B properly, I need four distinct stages:
- Booked demo: someone schedules a meeting.
- Attended demo: the meeting actually happens.
- Accepted opportunity: sales accepts the prospect under agreed qualification criteria.
- Closed-won: the opportunity becomes a customer.
Each transition filters the original group. A campaign can book cheaply and lose people at attendance. Another can get people into meetings but lose them at sales acceptance. A third can generate accepted opportunities that rarely close.
That is why optimizing only for form fills can reward form-fillers rather than buyers. The first number improves while the business result deteriorates. Everything looks green, right up until someone asks about revenue.
Before I compare A with B, marketing and sales need the same definitions. If marketing calls every completed meeting an opportunity while sales requires budget, authority, and timing, they are not disagreeing about performance. They are counting different things.
Tracking has to preserve those distinctions too. A booked demo must remain connected to its attendance record, its acceptance decision, and eventually its outcome. CRM and platform windows can differ, records can fail to connect, and imports can lag. A missing connection can make a real sale disappear from campaign reporting.
I would check the chain in this order:
- Can the booking be connected to its starting click?
- Does the attendance status reach the same record?
- Is sales acceptance recorded consistently?
- Can the eventual win be traced back through that record?
Agree the stage definitions in writing, then check that the records stay connected. A precise formula cannot rescue inconsistent inputs.
Attribution records a touch; it does not prove new demand
Even a complete record answers a narrower question than people think. It shows that a deal touched a ChatGPT ad. It does not prove the ad created the deal.
A buyer might ask ChatGPT for options, click an ad, later Google the brand, attend a webinar, and sign after a sales call. Several reports can claim a role in the same revenue. The contact happened. The causal argument is still open.
That matters for both A and B. A cheap booking could come from someone already shopping the category. So could an expensive one. A higher acceptance rate does not, by itself, prove that a campaign created more new demand.
I treat early attribution as a receipt, not a verdict. It helps connect spend with progression. It does not establish what would have happened without the ad.
Keep attributed pipeline in the report, but do not confuse sales acceptance—or even a closed deal—with proof of incremental demand. The funnel model measures progression; it does not answer every causal question.
Improve qualification while revenue catches up
Waiting for mature revenue does not mean leaving the account untouched. I still have three useful places to work: message, fit, and booking friction.
1. Make the ad promise match the landing page
The ad and page need to describe the same offer to the same buyer. ChatGPT ads sit below the answer with a sponsored label and do not change the answer itself. I would not treat the surrounding answer as copy the advertiser controls.
If the ad attracts broad interest but the page serves only enterprise security teams, the mismatch can fill the calendar with people sales rejects. I would fix that promise before celebrating the booking rate.
A cheaper response to the wrong promise is not progress.
2. Test whether qualification improves the economics
A company-size field, current-tool question, or qualification step before the calendar opens can help distinguish fit from curiosity. It can also discourage bookings. That is the tradeoff, not a defect to hide.
For Campaign A, the question is whether fewer bookings produce a better accepted-opportunity cost. If the booking price rises without enough improvement in acceptance, the change has not earned its keep.
Judge qualification changes by what survives them, not just what they remove.
3. Check the path from booking to attendance
A booking that never becomes a conversation cannot become an accepted opportunity through that meeting. I would inspect confirmations and reminders alongside the quality of the original interest.
No-shows do not come with a diagnosis attached. A weak confirmation sequence and weak intent can produce the same empty calendar slot. I want to check both rather than declare the traffic bad—or the reminders guilty—from one number.
Separate failure to attend from failure to qualify. They sit at different points in the chain and call for different fixes.
I would make these changes in small, logged steps: align the message first, test a qualification question second, repair the booking sequence third. Changing everything at once makes the result harder to interpret.
Before increasing spend, I want a readable group of attended demos—say 15 to 20—and sales’ assessment of them. That is a practical checkpoint, not a guarantee that the sample settles the argument. Five cheap bookings in the first three weeks do not earn an automatic budget increase.
Split the weekly report into actions and evidence
The weekly report I ask for has two halves. I refuse the version that merges them, because activity this week and revenue evidence from older cohorts answer different questions.
This week: what changed, why, and who owns it
The first half covers spend and management decisions:
- What changed in campaign settings, ad copy, or pages?
- What problem was the change intended to address?
- Who owns the decision?
- Did spending stay within the agreed approval rules?
Every change gets a plain-language reason. No change without a reason; no reason without a name attached.
This is one place where groas gets it right for long-cycle buyers: actions come logged with the reasoning behind them, rather than arriving as a surprise in a month-end deck. An agency that cannot show its decisions is asking me to pay for access without showing the management.
The action log should explain the work, not merely prove that somebody touched the account.
Cohorts: what the work has produced so far
The second half follows each click month through booked, attended, accepted, and closed-won. Alongside the counts, I want the costs that matter at each stage.
January may be old enough to judge across the full chain. March may still need an immature label. Neither should borrow the other’s outcomes to make a cleaner slide.
For A and B, this view reveals whether B’s stronger acceptance survives into closed-won, or whether A catches up later. It also prevents a recent burst of cheap bookings from outweighing an older cohort’s poor progression.
I use the same approach to judge ChatGPT success through maturing cohorts and closed-won revenue, rather than whichever platform column fills first.
Show what is known, what is still maturing, and which decision each can support.
Decide in advance what earns another dollar
I want decision rules written before the test starts. Afterward, everyone reads the same numbers with different hopes.
My rules follow the funnel:
- Continue cautiously if attendance holds above half of bookings and accepted opportunities stay within the target cost, even while closed-won remains immature.
- Pause and fix qualification if attendance is healthy but acceptance collapses. The meetings are happening; sales is rejecting what arrives.
- Consider expansion when a mature cohort produces accepted opportunities at an acceptable cost, tracking holds together, and closed-won progression does not overturn the case.
The last condition matters. B’s $1,200 opportunity is not automatically a bargain if those opportunities fail to close. An interim metric is useful precisely because it arrives sooner. It does not get promoted to revenue because waiting is inconvenient.
I would also review what a 90-day B2B test costs beyond media before approving month two. A budget decision needs the whole test cost, not just an attractive booking price.
Run the next agency quote through the same math
Say a proposal lands tomorrow promising $250 ChatGPT demos while the current search campaign books at $500. These numbers are hypothetical too. The lower quote is an invitation to calculate, not a reason to switch.
I would ask what acceptance rate the proposal assumes, how many attended demos the agency needs before judging the test, and what its weekly log will show while revenue is blank.
If the answer implies 15% acceptance, ten $250 demos cost $2,500 and yield 1.5 accepted opportunities on average. That is about $1,667 per accepted opportunity.
If the $500 demos have a 50% acceptance rate, ten cost $5,000 and yield five accepted opportunities. That is $1,000 per accepted opportunity.
The cheaper demo just priced itself out at the opportunity stage. I would still check attendance, cohort maturity, and eventual close rates before declaring a customer-acquisition winner. The model tells me which question comes next instead of letting the first conversion end the discussion.
Hire the agency that volunteers that second calculation without being asked. That is the test I lay out in how to hire a ChatGPT ads agency when the sale closes months later.
I keep cost per accepted opportunity near the top of the report, with closed-won progression beside it as the evidence matures. Start there. The $200 versus $600 question stops being about the cheaper meeting and becomes what it should have been all along: what survives the funnel, and what it costs to get there.


