

 LinkedIn
Monday, 9:04 a.m. At a kitchen table, with a laptop open and coffee already cold, I give Claude a Google Ads account to inspect. This is a composite week, not a client diary or a documented product test: the account, decisions and figures are illustrative, drawn from the home-services work I used to manage.
In this scenario, the account spends about $20,000 a month across 14 campaigns. It carries the usual scar tissue of three years of agency tweaks and in-house fixes. Claude gets the repetitive work through groas. I keep approval over every change, including the one I will wish I had questioned harder.
The rules take longer to set than the connection. Approve-first on every write, a $50-per-day cap on budget moves, and a change log with reasons and one-step undo. At 9:11, I type: “Audit this account. Rank the five biggest problems by money at stake.”
The ranking matters. I have sat through enough audits that list 40 best practices and fix nothing.
Before the first change: connect the hands, set the limits
A plain chat window is not an account manager. Without a live connection, Claude cannot inspect the account’s search terms, conversion settings or impression share. It can explain settings and draft headlines. That is useful, but it is not the same job as reading an account and changing it. The usual practitioner answer applies to ChatGPT too.
For this week, the connection runs through groas. I connect the ad account once, then add groas to Claude as a remote MCP server: Customize → Connectors → Add custom connector, paste https://mcp.groas.ai/mcp, and sign in.
Google’s own open-source Google Ads MCP server is read-only. It provides reporting access, not the pauses and account changes this scenario needs. groas supplies the write layer, along with competitor ads and landing pages, Reddit discussions, AI-search visibility data, and SEO data from Semrush and Ahrefs.
Before asking for a single edit, I set three limits:
- Every proposed write needs my approval.
- Budget movement stays within the $50 daily cap.
- Each change needs a logged reason and a one-step way back.
Autopilot stays off. I want to inspect the decisions, not discover them later in a performance chart.
Day 1: five problems, not 40 best practices
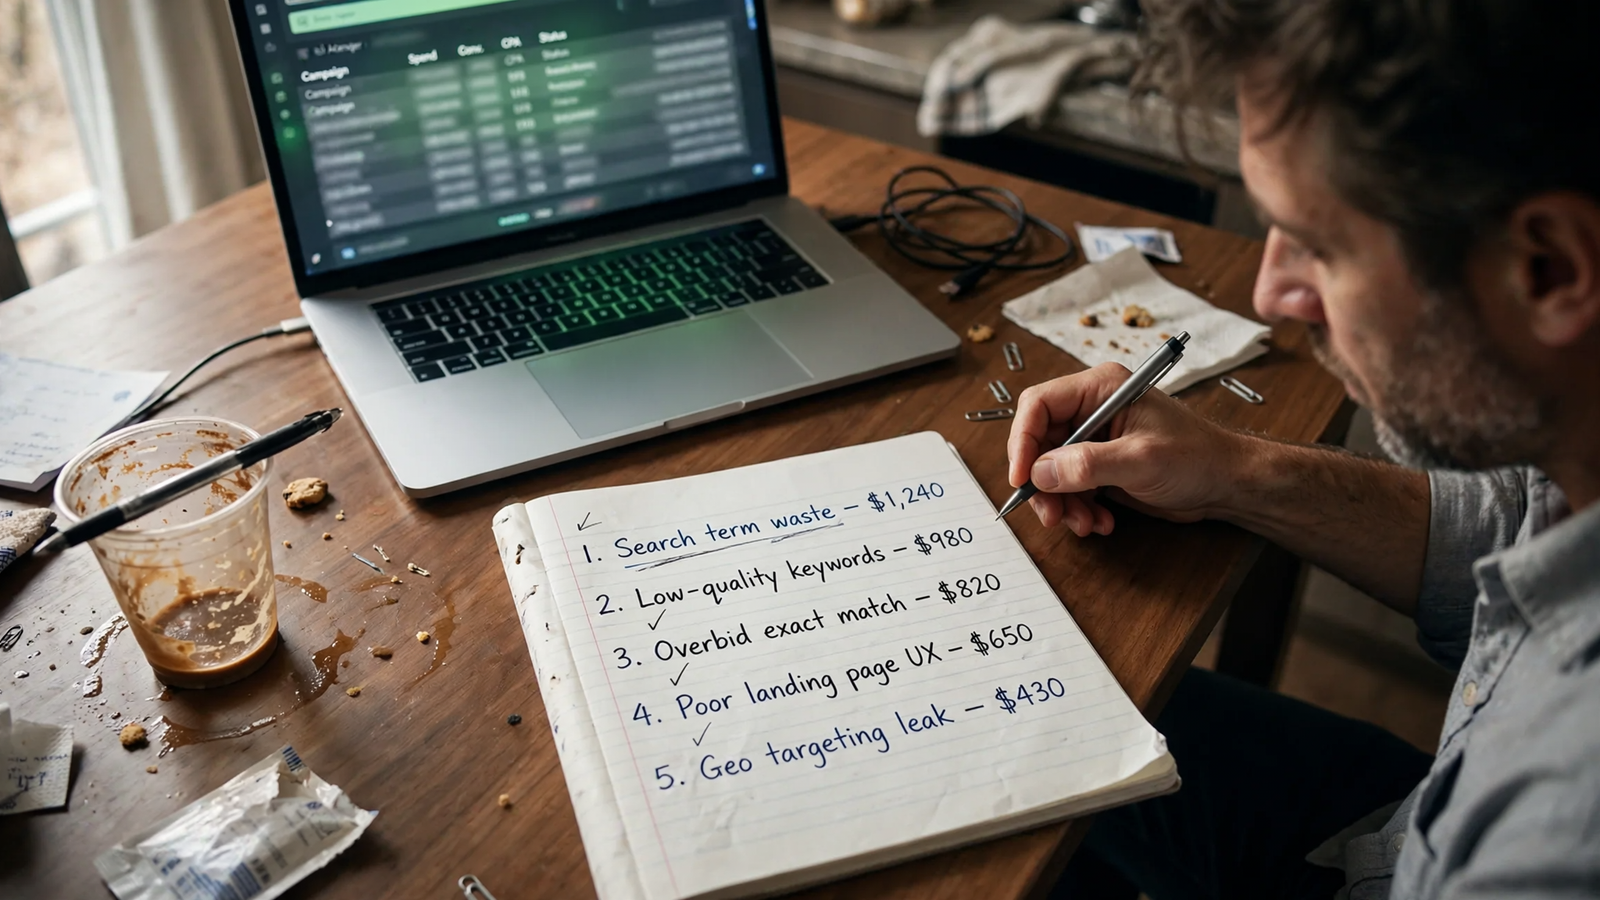
Claude’s audit comes back with five problems, ranked by the money attached to them. Two search campaigns overlap on high-intent keywords. Queries about free help, DIY repairs and jobs consume spend without bookings. The four biggest spenders each have one responsive search ad per ad group. Location bid modifiers have not moved since 2023, although job value has shifted two suburbs over. Conversion settings count page views alongside booked calls.
That last one makes me wince. I used to tell clients their tracking was “good enough.” I was wrong. If the account treats a page view as a useful outcome, Smart Bidding gets the wrong instructions.
Any decent account audit checklist can surface these settings. The useful part is putting them beside spend and deciding what deserves attention first. In this example, the junk-query bucket accounts for roughly $2,100 a month. The overlapping campaigns need a closer look at routing and reporting, not a dramatic claim that the account is bidding its own CPCs up.
I approve the duplicate ad-group pause and hold the more consequential changes for review. Conversion settings feel like surgery, so I reserve Saturday for them. That is not permission to forget them. They stay on the list, with the account’s reported performance treated cautiously until then.
Day 2: 48 negatives, four reasons to say no
Tuesday’s prompt is shorter: “Show me every query that spent over $25 without a booking in 90 days. Group them. Propose negatives.”
Claude reads the search terms through groas rather than waiting for the CSV export I used to download. In this composite, 212 queries meet that filter. Most fall into three buckets: job seekers, DIY fixers, and people looking for free quotes. That last group needs more care than its label suggests.
The proposed list contains 48 negatives: 36 exact-match, the rest phrase-match. The mechanism is not glamorous. A negative blocks matching searches, so budget no longer goes to those queries. Whether that improves the account depends on whether the excluded searches really lack value. A tidy spreadsheet cannot answer that by itself.
I approve 44 and block four. Claude wants to exclude queries containing “cost,” including “emergency repair cost same day.” That is not obviously wasted intent. In home services, someone asking what an urgent repair costs may be deciding whom to call, not looking for a free afternoon project.
I have made that mistake before: negating my way to a cleaner account and a quieter phone.
The grouping earns its keep; the intent judgment still needs scrutiny. The approved negatives go live by lunch. The rejected four stay in the conversation, where I can see why I said no instead of trying to remember next month.
Day 3: a $40 proposal becomes a $30 move
Wednesday, 7:48 a.m. Same table, better coffee. “Where are we losing impression share, and where are we paying for visibility that never books?”
Claude reads impression share beside cost per booked call. One suburban campaign hits its budget cap each afternoon. It also loses impression share to rank, which is a separate problem. More budget does not automatically fix ad rank, and I do not want those two columns folded into one convenient explanation.
Another, broader campaign spends $68 a day while holding 82% impression share on terms that have produced two bookings in 60 days. That gives us a budget-allocation question worth asking, even with the tracking caveats still hanging over the account.
Claude proposes moving $40 a day from the broad campaign to the capped one. The proposal fits the $50 limit. I approve $30.
I have overshifted budgets on a Wednesday and regretted it by Friday. Here, I want a smaller move while I inspect the conversion setup, not a machine-sized expression of my confidence. The cap is a ceiling, not a recommendation. The log records both the proposal and the smaller change I actually approve.
Day 4: the competitor ads make the copy less generic
Thursday is when Claude stops sounding like a spreadsheet. “Compare our top ads with three competitors in this market. Rewrite two headlines.”
groas supplies the competitors’ Google and Meta ads, plus the landing pages and offers behind them. Claude does not have to improvise a market from whatever it remembers. In this scenario, the repeated message is same-day arrival windows and a fixed callout price. Our ads lead with “trusted since 2008.”
Nobody books nostalgia when water is coming through a ceiling.
Claude drafts two responsive search headlines around arrival time and flat pricing. Those are proposals, not permission to borrow a competitor’s promise. The landing-page mismatch is already flagged; I hold the headlines until I can check that the offer and page support them. Only then do I approve publication.
The useful change is not that Claude suddenly develops taste. It has something concrete to compare: their ads, our ads, the offers behind both. That produces a better discussion than “make this more compelling,” which usually produces the same sentence with a louder adjective.
By the end of Thursday, two headlines are live. They have not won anything yet. They have merely earned the right to run.
Day 5: the pause that looks right in the wrong column
Friday afternoon, I type a prompt that is too neat: “Pause anything under target ROAS for 14 days.”
Claude flags a suburban exact-match keyword at 1.1x against a 2.5x target. The proposed reason is tidy: low efficiency, move spend to winners. Within the account’s reported numbers, the recommendation makes sense.
What those numbers miss sits in the CRM. In this composite, the keyword starts a call that leads to three high-ticket jobs later in the week. Those jobs appear as direct business rather than revenue credited to the keyword. Claude cannot make that connection from the Google Ads column alone.
I approve the pause with what I call autopilot-brain. The product’s autopilot is still off. Mine, apparently, is not.
Approve-first only helps when I actually review the decision. The request reaches me, the reason is visible, and I still accept a narrow answer to a broader business question. It is tempting to call that an AI mistake and leave my contribution out of the story. I supplied the blunt rule and approved its result.
The pause enters the log. So does the reason. For the moment, it looks like another sensible piece of account housekeeping.
Day 6: the tracking job I keep putting off
Saturday gets the task I dread: “List every conversion action in this account and tell me which ones should not be primary.”
Claude returns nine primary actions. Among them are two page-view events, a contact-page scroll, and a duplicated call event coming from both the site tag and the call provider. The account is not simply counting bookings. It is counting a collection of things people do near a booking and allowing that collection to stand in for business value.
That explains why the earlier recommendations need care. If the account rewards a scroll, an optimiser can faithfully pursue more scrolls. The resulting report may look healthier without the phone becoming any busier.
Claude proposes demoting seven actions to secondary and retaining booked calls and qualified forms as primary. The proposal waits for approval before anything changes. I review the actions, approve the cleanup, and leave bid targets alone. The CRM attribution mismatch still needs attention; changing several kinds of instruction at once would make the next week harder to read.
This is the least exciting screen of the week. No clever headline, no dramatic budget move, just a list of events and the question of which ones deserve to steer spending. I spend the hour there anyway.
Day 7: the log gives me a way back
By Sunday, booked-call volume looks softer. That is a reason to investigate, not proof that Friday’s pause caused it. I open the CRM and trace the keyword’s calls. The jobs attributed as direct change how that 1.1x figure looks.
I return to the groas change log, find Friday’s pause and its reason, and hit undo once. The keyword resumes without rebuilding it or sending a ticket to an agency. Undo reverses the change; it does not refund the time the keyword spends paused. I still need to understand why the approval fails.
The answer is sitting in the two systems. Google Ads gives Claude one account of the keyword. The CRM gives me another. The pause follows the first account too confidently, and I approve it without checking the second.
Sunday night, same table. I type: “Summarise every change this week with its reason and early effect.”
The log brings back the negatives, the smaller budget move, the two headlines, the conversion cleanup and the reversed pause. It also preserves the decisions not to act: the four rejected negatives and the held tracking question. That is more useful than a chat transcript I have to excavate for the moment something becomes a decision.
In the illustrative Sunday snapshot, junk-query spend is $310 lower for the week. The suburban campaign’s impression share moves from 59% to 71%. The new headlines have 1,900 impressions. None of those figures establishes a lasting improvement, and the impression-share change does not prove that the budget move fixes rank.
The account has a nine-day conversion lag. Seven days cannot settle booked revenue, Smart Bidding performance or the copy test. I ask for early effects, not a victory lap. The sensible entry is: wait for two full booking cycles before judging the outcome.
I have watched humans declare victory on a Sunday that falls apart by Thursday. There is no reason to automate that habit.
Sunday, 10:14 p.m.: leave the log open
What I keep from this composite is the operating shape: hand over the repetitive work without handing over the account. Claude groups search terms, reads reports and drafts changes. groas supplies the connection, the data and the means to act. I set limits, inspect business intent and remain responsible for what I approve.
That is also my answer when someone asks whether Claude can optimise Google Ads through groas. It needs more than a good prompt. It needs account access, a way to make changes, and controls that survive a confident but incomplete recommendation. ChatGPT changes the chat window, not that requirement.
The infrastructure costs $19 a month flat for every account and every teammate on groas Unlimited. That sits awkwardly beside the percentage-of-spend invoices I used to send. It does not buy judgment, though. Friday is a useful reminder of the distinction.
This remains one illustrative account over one composite week, not evidence of a performance gain. If tracking is broken, approvals are blind, or payroll depends on a seven-day turnaround, I would not start by giving an agent more freedom. I would start with the part of the account I keep avoiding.
At 10:14, I close the laptop. Same kitchen table as Monday, clean mug this time. In the other tab, the change log is still open on Friday’s pause, its reason, and the undo.


