

 LinkedIn
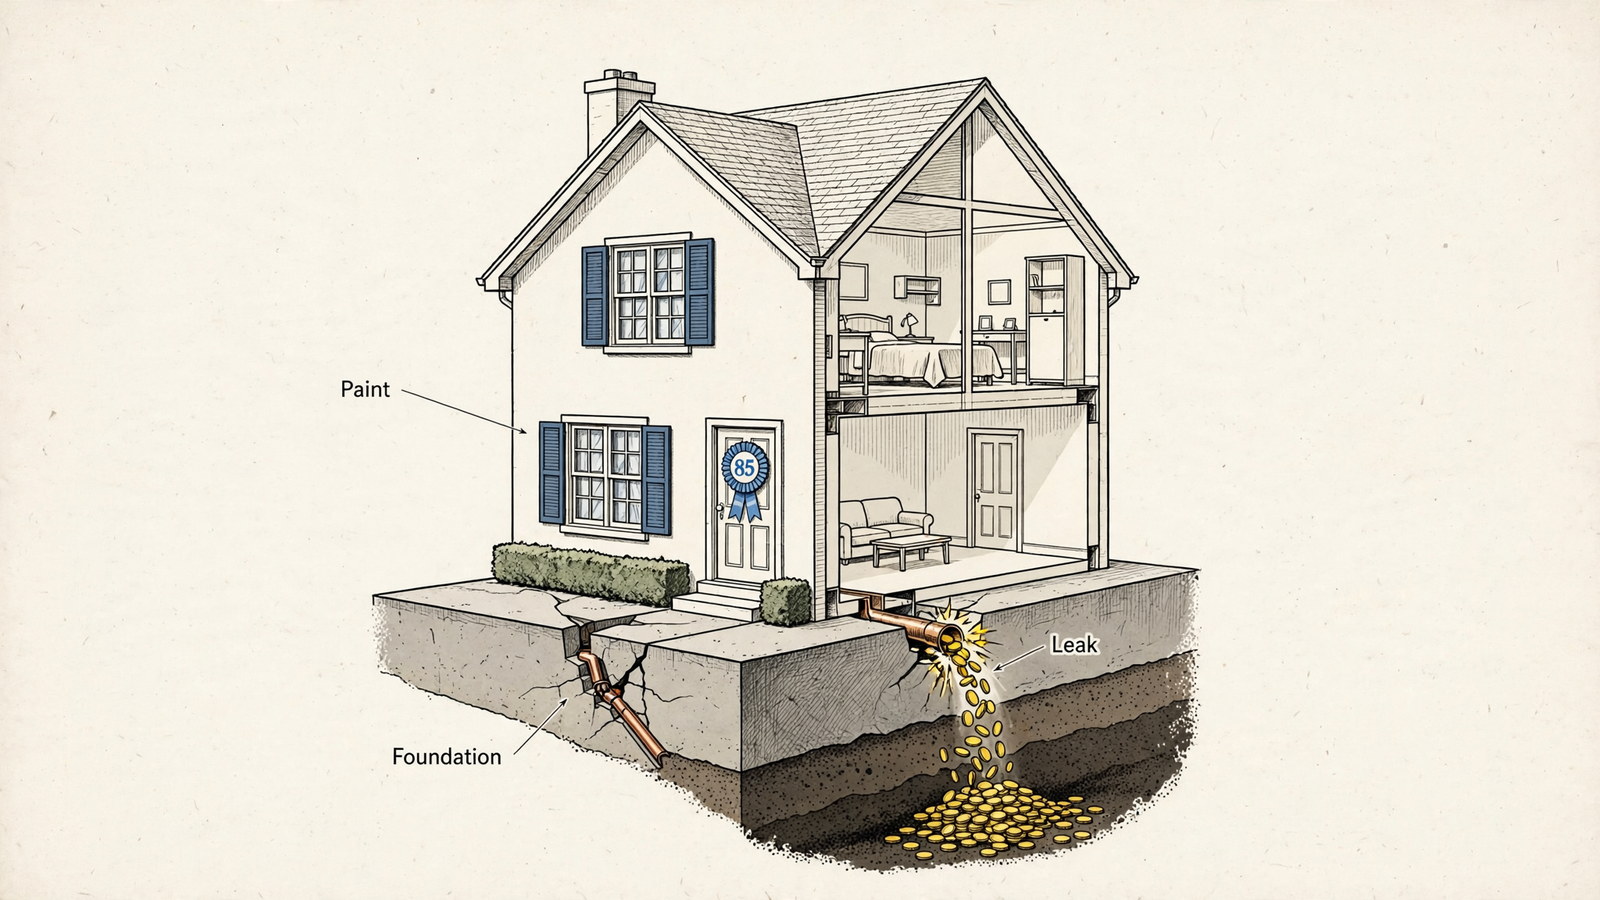
Your Google Ads account can score 85 out of 100 and still lose money. Should ChatGPT give it a grade anyway? Smart people disagree because a fixed score makes audits comparable, while a business diagnosis catches problems that tidy settings can hide. I want the repeatable checks. I do not want them averaged into a universal verdict.
Say you spend $20k a month and change the offer in March: new pricing, new trial terms, tighter qualification on the demo form. The account still looks tidy. Quality Scores sit at 7s. Nothing is disapproved. Before touching anything, you want to know whether the account is healthy.
One camp wants a number: the same checks every time, so a slide from 82 to 71 means something. The other wants to know whether the account still buys customers for the new offer. My verdict: keep the checks, reject the universal grade. Here is the strongest case for each side, and the output I would ask ChatGPT for instead.
The case for a score: make every audit take the same test
The strongest pro-score argument is not that a number captures everything. It is that an inconsistent audit captures whatever the auditor remembers to inspect.
Manual account management involves enough repetitive work without making the audit itself a memory test. A fixed rubric keeps the settings tab from disappearing behind a more interesting search-term problem. It makes omissions visible. It also makes the next audit comparable to the last one.
That is why tools like WordStream’s free Google Ads Performance Grader, which checks a connected account against 10 key metrics and returns an overall score with a report, have an obvious appeal. Its pitch includes 6.4 million free reports generated and $36 billion in spend analyzed. People want the same test applied the same way twice.
Google’s own version follows a similar logic. Optimization Score estimates how well an account is set to perform, from 0 to 100%, using settings, statistics and available recommendations. The strongest defense treats it as a hygiene trigger, not a profit verdict: review the flagged work, decide what matters, and stop neglect from accumulating.
There is a detail critics sometimes skip: dismissing a recommendation also moves the score toward 100%. The number rewards reviewing the list. It does not require applying everything on it.
Comparability is the honest selling point. When two people inspect the same account a month apart using the same checks, they can identify deterioration: impression share slipped, Quality Score distribution moved, wasted spend ticked up. The conversation starts with what changed, rather than whose audit looks more impressive.
PPC Grader extends that pitch with live API analysis across 40-plus signals, an A–F grade and a wasted-spend summary. It also advertises 15–30% CPC savings from Quality Score fixes and 28–38% average waste found. I would not treat those averages as a forecast for your account. The useful mechanism is the repeatable inspection underneath them: same test, same data pull, less storytelling.
If ChatGPT plays this role, I want it to show its work:
- Every rule it scores.
- The threshold it uses.
- The campaign, ad group or search term that passes or fails.
- The evidence behind the finding.
The recommendations also need separate decisions. One useful recommendation taxonomy distinguishes fixes to apply, changes to test on contained budgets, and suggestions to dismiss. Fixing disapproved ads is not the same decision as testing broad match. Raising a budget on an efficiency-capped campaign is not automatically progress.
For an internal checklist, a grade can make that review fast and repeatable. A score earns its keep when I can inspect—and argue with—every point behind it.
The case against a score: tidy settings can hide a broken business signal
The strongest objection is not that checklists are useless. It is that the final number can make unequal problems look interchangeable.
A conversion-tracking failure and an untidy account structure do not deserve equal attention just because both lose points. One undermines the evidence used to judge everything else. The other may be housekeeping.
An audit of 2,167 accounts reported that 42% had no conversion tracking and only about half of the remainder tracked something meaningful. Among well-tracked accounts, it reported that 61% of spend went to search terms that never converted. Those are different failures requiring different decisions. Compressing them into one mark makes the distinction harder to see.
Take an illustrative account showing a 4.2 ROAS and a score of 86. The CRM then reveals that half the “conversions” are unqualified form fills from the old offer. The neat dashboard has not answered the business question. It has displayed the wrong answer neatly.
Google’s conversion troubleshooting guidance points to concrete checks: conversion status, firing verified with Tag Assistant, and Primary versus Secondary settings. These belong before any confident performance judgment. Score the account without verifying the inputs and the decimal places are decoration.
The changed offer creates another problem. In the opening scenario, suppose the trial falls from 14 days to 7, prices rise 30%, and the demo form starts rejecting small teams. Historical CTRs and conversion rates now describe an offer the business no longer sells on those terms.
The settings may be unchanged. Their commercial meaning is not.
A critique of Optimization Score makes the underlying distinction: alignment with Google’s preferred setup is not the same as alignment with margins, CPA ceilings or capacity. A tight-CPA campaign can score lower while a more expansive setup scores higher. Following recommendations toward 100% can mean more reach, budget and automation without better efficiency.
That is the flaw in treating the score as the answer rather than a pointer to questions. Compliance is not profit. Verify what the account measures before grading how it performs.
Put both methods against the same changed offer
To settle the debate, I would give both methods the same account and the same date range.
The score-led pass examines Quality Score distribution, impression share, CTR by campaign and account activity. It supplies the repeatable checks its advocates rightly want.
The diagnosis-led pass asks a different set of questions:
- Which conversion actions still record the intended outcome?
- Which search terms take the money?
- Does that traffic still fit the new offer?
- Which findings are established, and which need verification?
That is the distinction between surface audit findings and structural diagnosis. The score tells me the house is painted. The diagnosis checks the foundation.
I would start ChatGPT with this instruction:
Audit this account without changing anything. Separate measurement faults, wasted spend and untested opportunities. Rank the findings by likely business impact. Show the evidence and uncertainty for each, including the campaign, date range and conversion action where relevant. Flag missing evidence rather than filling it in.
Connected through groas, ChatGPT can read live account data instead of relying on a generic checklist. groas Unlimited includes that connection and every feature for $19 a month, flat for the team. The advantage is not another grade. It is the ability to question a finding against the account behind it.
Connection does not make every answer correct. A WordStream check of five AI tools on 45 PPC questions found about 20% of 225 answers wrong, including advice about retired features such as Enhanced CPC. I still want the campaign, date range and conversion action behind a claim, and I would recheck the math.
The difference becomes obvious when priorities collide. A single 78 cannot explain why, in an illustrative audit, $4,300 went to old search terms with no recorded purchases after the price rise, while a flagged “opportunity” asks for more budget on a campaign constrained by margin.
The underlying checks can uncover both findings. The composite number cannot tell me which deserves Monday morning.
That is why the useful sequence starts with verifying conversion tracking, then reviewing 90-day search terms by cost and separating brand from non-brand. The work happens below the grade. I need the checks to produce an order of operations, not an average.
My verdict: ask for a ranked diagnosis, not a universal grade
For an advertiser deciding what to fix after an offer change, I take the diagnosis side. The deciding consideration is simple: does the audit connect its findings to what the business now values?
A universal grade does not answer that. Knowing whether the same $20k still buys qualified pipeline after the price rise does.
I would keep the repeatable checks, including the seven signals of an actually healthy account, but refuse to let ChatGPT flatten them into one mark. Ask for four things for each finding:
- Issue: what is wrong or worth testing?
- Evidence: what account data supports it, and what is missing?
- Business consequence: what money or outcome is at risk?
- Next action: what should happen before anything else changes?
A money estimate is useful when the evidence supports one. A made-up estimate is just another score wearing a currency symbol.
Here is what that ranked output could look like. These are illustrative findings, not results from a reported account audit.
1. Measurement faults: establish whether the numbers are usable
Finding: Demo requests drop from 34 to 3 per week after March 12. The conversion action HubSpot - Demo shows No recent conversions. A separate Tag Assistant check shows firing on only one of two form variants.
Consequence: The conversion record is incomplete. Reported CPA and bidding decisions cannot be trusted until the fault is understood.
Next action: Fix and verify tracking before touching bids. The 10-point audit framework puts that deeper inspection ahead of surface findings.
The account data identifies the warning; the Tag Assistant check supplies additional evidence. I would not let ChatGPT claim it performed that check unless the result is actually available to it.
2. Wasted-spend candidates: connect the traffic to the new offer
Finding: The top 12 search terms by cost since the price change account for $4,300, contain cheap or free tool, and show zero recorded closed-won outcomes.
Consequence: The account is spending on traffic that may no longer fit the offer. That needs attention before a cosmetic score improvement.
Next action: Once measurement is verified, review those terms for exclusion or isolation. Keep the evidence attached to the decision; zero recorded wins is not permission to stop thinking.
3. Untested opportunities: keep possibility separate from proof
Finding: Non-brand impression share is 31%, there is no lost-to-budget flag, and the Shopping feed is approved.
Consequence: There may be an opportunity to investigate. Those facts alone do not establish profitable scale.
Next action: Identify what supports the opportunity, then test on a contained budget rather than treating more spend as the default fix.
That is an audit I can use. Measurement first, waste second, tests third. No score. Just order.
Keep diagnosis read-only until the decision is made
The prompt says “without changing anything” for a reason. A diagnosis should not quietly become an editing session while I am still checking its evidence.
When ChatGPT proposes a fix through the connected account, I want confirmation before execution. The ChatGPT plus groas workflow supports that approval step, with changes logged alongside their reasons and undoable in one step. After approval, I would check that the reason log matches the decision and that the account reflects it.
Campaign name. Date range. Conversion action. If a claim lacks the evidence needed to support it, I treat it as a draft, not a finding. No approval, no change, no mystery edits.
A score still has one narrow job inside a business: a private tripwire. Publish the rubric, keep the same 10 checks, thresholds and date ranges, and an internal move from 71 to 78 can show drift or repair. It does not establish that this account’s 78 beats another account’s 74.
A free grader can inspect a connected account and return a useful checklist. The groas connection at $19 a month for the team serves a different job: live account data plus competitor and Reddit context in the same ChatGPT thread, giving the diagnosis more to work with than a mark on a dashboard.
For the advertiser deciding where the next dollar goes, that is my ruling. Keep every check that can survive inspection. Reject the universal grade. Ask ChatGPT for the ranked diagnosis, fix measurement before moving money, and leave the score where it belongs: a private tripwire, not the verdict.


