How to Automate Brand Visibility Reports Across AI Assistants
October 5, 2026
•
6
min read
Your AI visibility score went from 31 to 38 this month. Your competitor sits at 64. Nobody on the call can tell you what that bought you.
I have sat in that meeting before. In 2015 the number was called impression share. The deck was cleaner back then, but the sales pitch was identical: a percentage that moves, a green arrow, and no connection to CPA or booked work. I used to report it myself. I was wrong to let it carry that much weight.
It is the same vanity metric with a new haircut. Charging a monthly retainer to deliver it is the part I cannot let slide.
Here is what an AI visibility score usually measures, stripped of the branding. You pick 15 or 50 or 100 prompts. A tool runs them across ChatGPT, Gemini, Perplexity, maybe Claude. It counts how many answers mention you. That becomes your visibility score: a percentage drawn from the responses to your tracked queries. Change the prompts and you change the score. That is not a rounding error. That is the product.
Impression share measured something different: the percentage of eligible ad impressions you actually showed for. But it played the same role in the meeting. Share slipped from 72% to 64%? We need budget. Share went up? Our optimizations are working. Sales could stay flat through both versions of that conversation. I know because I sat on the agency side of the table and watched CPA climb while the share number looked healthy. A visibility measure is not a performance result, however attractive the arrow beside it looks.
Pick category prompts and you might score 12. Add ten branded prompts with your name in them and you might score 47. Nothing changed about your business. You just graded your own homework. That is why I want to see the prompt bank before I care whether a vendor puts you at 32 and your competitor at 68. It is a count of a sample someone built, not a count of the market. Tracker help docs spell out the ingredients: visibility, position, citation and sentiment components, computed over sampled prompt outcomes. Pipeline is not in the recipe.
AI answers also wobble from run to run. Ask the same question Tuesday and Thursday and you can get different wording, different sources, sometimes a different winner. One check is noise. A month-long trend is more useful, but only if you keep the prompt list and schedule fixed. Otherwise the arrow may be measuring a change in your test. Most monthly reports do not make that distinction easy to see. They show you the arrow and let you assume somebody earned it.
Then comes the rest of the page. A sentiment dial that says 72% positive. A trend arrow. A share-of-voice bar where you are a sliver and someone else is a block. It looks like analysis. Mostly, it is decoration. A critique of vanity metrics names these AI numbers directly: brand mentions in AI answers, share of voice in chatbot replies, total AI impressions. Its test is more useful than the dial. Can you name what caused the change? Does it change a decision? Can you connect it to revenue? A score on its own answers none of those questions.
I learned that lesson the expensive way with impression share. High share did not guarantee sales. Chasing it could push bids up, bring in loosely related queries and send CPA the wrong way. The AI version invites the same mistake. People celebrate a rising mention rate while traffic sits flat because a mention and a click are different things. Being named is not being chosen. A citation is not a customer.
The model updated. A competitor published three pages. Perplexity shuffled its sources. Your score drops six points and the report calls it a visibility loss, followed by a paragraph about “optimizing your presence.” You changed nothing. Your site changed nothing. The sampled answers changed.
That movement may be worth investigating. It does not prove that your vendor missed a fix last month or found one this month. First, show me the same prompts run on the same schedule. Then show me which answers changed. If the report skips those steps, the arrow is not an explanation. It is a reason to schedule another call.
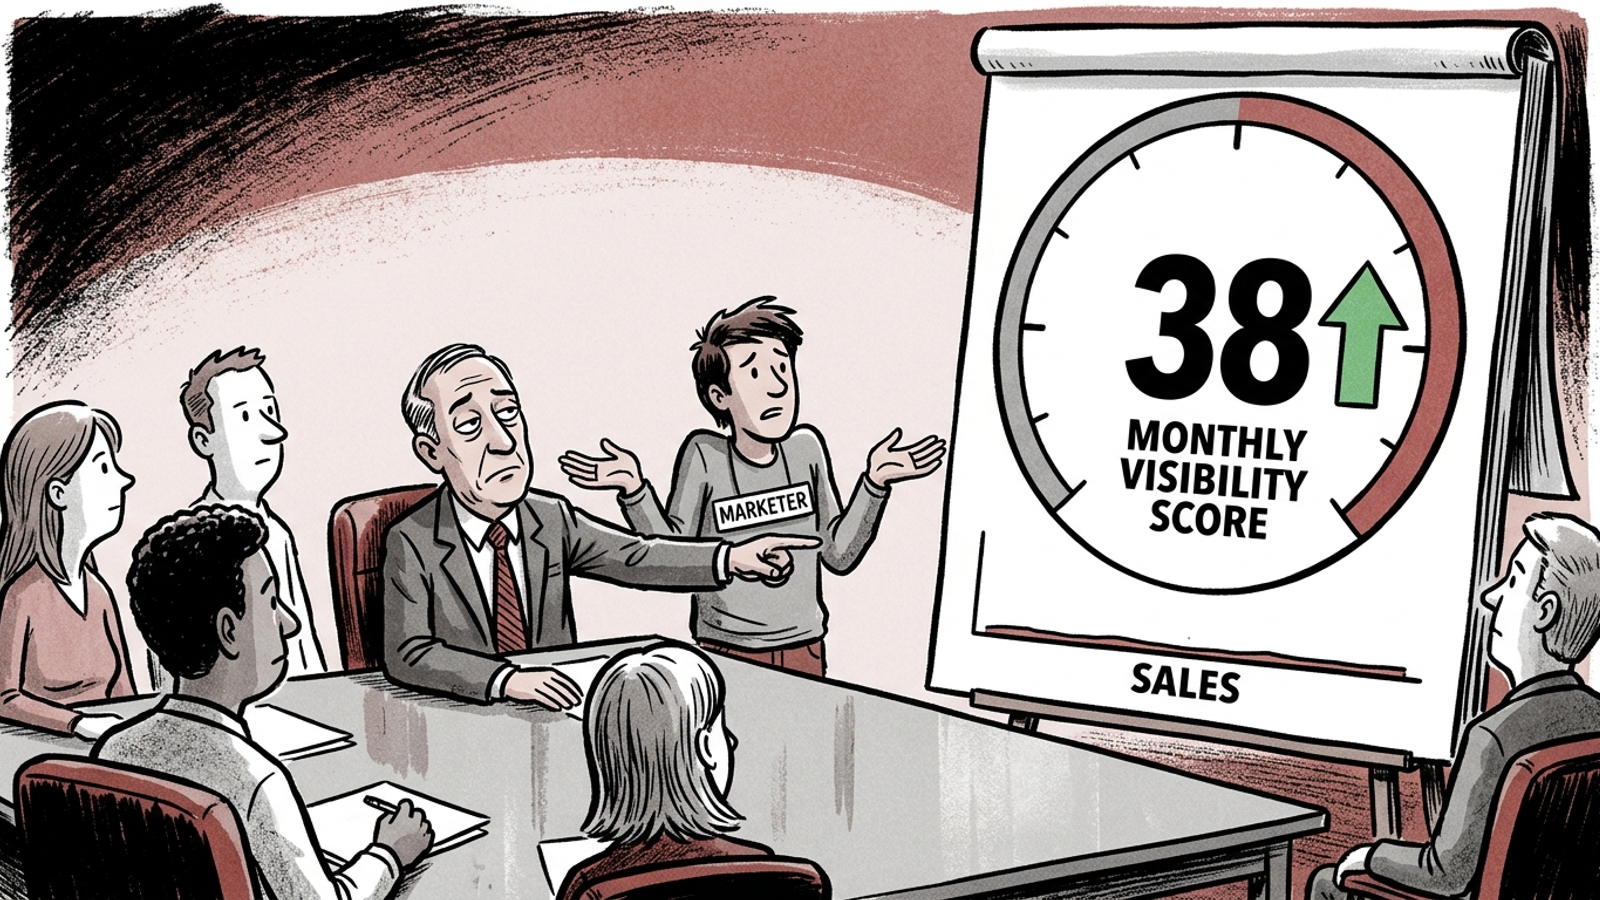
Paying monthly to be told you are invisible is a strange purchase when you say it plainly. Lite tracking starts at $29 a month for 15 prompts, Standard at $189 for 100, and Premium at $489 for 400, with Claude, Gemini and Google AI Mode as paid add-ons. Say you spend $20k a month on ads and someone sells you a $189 report saying your AI visibility score is 28. What did you buy? A count from a selected sample. The software can produce that count; it cannot, by presenting it, claim the work of changing the result.
This is where the old agency trick returns. The report ends with recommendations. Add an FAQ page. Build topical authority. Improve E-E-A-T. I received those same lines when I managed accounts, and I wrote a few of them when I was too busy to do the work. What the deck calls synergy, I call two people doing the same job: one writes the recommendation, and the other is supposed to execute it. The second person is you, after hours, with no time.
I am not offended by a tracker charging for tracking. I am offended when tracking is packaged as management. If the monthly deliverable ends at “your score fell,” the vendor has identified a chore and handed it back to the person paying the bill. A recommendation is not an action log. No amount of formatting closes that gap.
Automating the report is sensible. I tell small teams to try it before they pay someone to narrate a dial, because “visibility” tends to collapse three different questions into one word: are you mentioned or cited, are people clicking through, and are AI bots crawling your pages? A sampled mention score addresses part of the first question. The others need their own evidence. Putting a larger number on the first does not make the other two disappear.
Start with what costs nothing: the search, analytics and server-log data you already have. Look for traffic and leads before you call a mention an outcome. Then run your own prompt bank: ten to 30 buyer questions across ChatGPT, Gemini, Perplexity and Claude on a fixed weekly schedule. Mix brand, category, comparison and pre-awareness problem questions. Freeze the list for a month. If you edit it halfway through, mark the break instead of drawing one smooth trend line and calling it progress.
When you want the checks scheduled, an n8n workflow can read prompts from a Google Sheet, send them to ChatGPT, Gemini and Perplexity, and write the brand checks back. Bring your own API keys. At roughly $5 to $14 per 1,000 Perplexity Sonar requests on top of tokens, 25 prompts run weekly cost low single-digit dollars per month. That is useful automation. It is still a count, not a content edit, a crawl fix or a new customer. Do the cheap measurement cheaply. Save the serious fee for someone who does the serious work.
Automating the count is fine. Paying for the count alone is the waste. If someone wants a monthly fee, I want a report that connects the sample to actions and those actions to business results. Here is my filter. If a line is missing, I ask why before I pay.
Item three reveals whether the report is attached to any work at all. Item five is where that work goes to die next month. I used to tell clients a monthly summary was accountability. I was wrong. Accountability is a timestamped list: page changed, prompt retested, citation won or lost, reason attached. If a vendor cannot show that list, you did not hire monitoring with follow-through. You hired a narrator.
The engine I work with now logs every action with its reasoning in plain language. I hold that up because it is the minimum I want from anyone taking a management fee. Not a paragraph about what ought to happen. What happened, when it happened and why.
There is a mechanical reason the log matters in AI search. Bots do not always read a site the way a person with a browser does; scripts and design can obscure the material you meant them to find. That is why groas focuses on making a business readable, citable and recommended rather than handing it another dashboard and a list of chores. A mention without work on the pages and citations behind it may disappear on the next run. The report should be attached to that work, not the other way around.
Here is my rule. Automate the count for dollars a month. Pay real money only for the work attached to it: a fixed prompt list, a fetch log, an edit log, a traffic tie and a named owner for next week. groas gives clients a weekly breakdown of what changed, why, what happened next and where the strategy goes. That is the right order. Change first. Explanation second. Score a distant third. If a vendor leads with the score, they are selling you the exhaust and keeping the engine.
Stop paying to be told you are invisible. Pay to become citable, or do the cron job yourself and keep the $189.
This will not work for everyone. If you sell to five local zip codes and your buyers still call from the map pack, run the baseline and the frozen sheet and stop there. If you compete nationally on advice queries where an AI answer names three brands and the rest vanish, the mention rate matters. Use it as a tripwire for fixes: pages bots can parse, citations they can use, answers they can repeat. Buy the work that moves those inputs. Score-chasing without it is rent on a dial.
The author argues it plays the same role impression share did in 2015: a percentage that moves with a green arrow but no connection to CPA or booked work. Both can look healthy in a meeting while sales stay flat.
Yes. Pick category prompts and you might score 12; add ten branded prompts containing your own name and you might score 47, with nothing about the business changed. That is why the prompt bank should be shown before a vendor's score is worth caring about.
Model updates, competitors publishing pages, or Perplexity shuffling its sources can change the sampled answers without anything on your site changing. A month-long trend is only meaningful if the prompt list and schedule stay fixed; otherwise the arrow may be measuring a change in the test itself.
Not on its own. A mention and a click are different things, and people often celebrate a rising mention rate while traffic sits flat. Being named is not being chosen, and a citation is not a customer.
The software produces a count from a selected sample of prompts, and trackers can charge anywhere from $29 a month for 15 prompts to $489 for 400, with some AI models as paid add-ons. A count alone cannot change the result, so paying a management fee for it is paying to be told you are invisible.
Run your own prompt bank of ten to 30 buyer questions across ChatGPT, Gemini, Perplexity and Claude on a fixed weekly schedule, freezing the list for a month. An n8n workflow can read prompts from a Google Sheet and write the brand checks back; 25 prompts run weekly cost low single-digit dollars per month in API fees.
Five lines: which prompts changed and why, which pages AI bots fetched (from logs), what work was actually done, which cited answers sent traffic or leads, and what happens next with a named owner and deadline. If the deliverable ends at 'your score fell,' you have hired a narrator, not monitoring with follow-through.
If you sell to five local zip codes and your buyers still call from the map pack, run a baseline with a frozen prompt sheet and stop there. The mention rate matters more if you compete nationally on advice queries where an AI answer names three brands and the rest vanish.