One lucky ChatGPT screenshot tells you about as much as one good day in a Google Ads account. To find out whether AI answers recommend your business, use a fixed set of buyer prompts, run them repeatedly, and measure your share against competitors.
“How can my business measure brand visibility across ChatGPT, Gemini and Google AI Overviews?”
Start by putting aside your standard 500-keyword SEO export. Buyer situations matter more here than a list of keyword variations. Build a fixed panel of roughly 30 to 50 conversational prompts from sales call transcripts, support tickets, and bottom-of-funnel questions where customers evaluate alternatives. If you want the full protocol for assembling that panel, read our guide on how to measure AI search visibility without trusting one screenshot.
Then keep the prompts frozen. If you rewrite a question halfway through the month, you cannot tell whether a change in visibility came from the answer engine or from your new wording. A prompt panel is useful precisely because it lets you compare like with like.
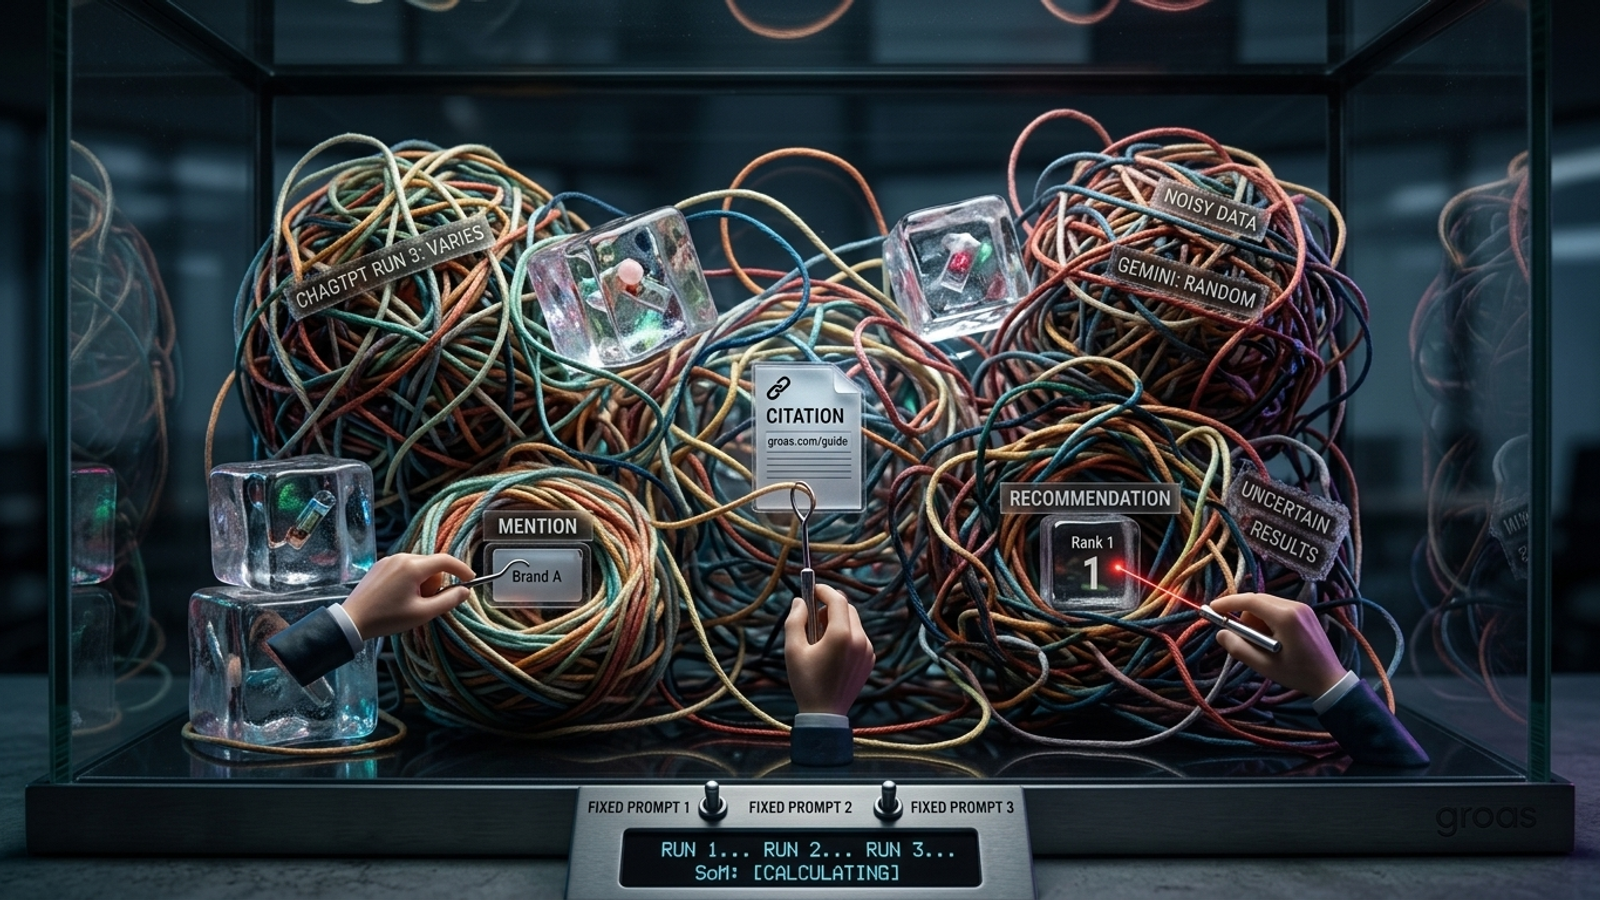
Next, stop treating every appearance as the same event. In our testing and in enterprise LLM visibility research, three distinctions matter:
- Mention: The answer names your company in running text without linking to your site.
- Citation: The answer links to a specific URL as support, often in a reference drawer or footnote.
- Recommendation: The answer evaluates your product against the buyer’s criteria and puts it on a shortlist.
A mention may tell you the model associates your name with a category. A citation tells you which page it surfaced. A recommendation tells you whether you made the buyer’s shortlist. If citations are missing, inspect whether your pages can be crawled and their information extracted. If recommendations are missing, inspect what reviews and comparison pages say about you. Roll all three into one appearance rate and you lose the diagnosis.
“Why does the same prompt give a different answer every time I check?”
Because you are measuring a variable answer, not reading a fixed database entry. A traditional search ranking can move, of course, but a generative answer can name different companies across runs of the same question. As Graphite’s discussion of AI randomness explains, a single manual query gives you one noisy observation.
Say your brand appears in about 40% of answers to a buyer prompt. One check still returns a simple yes or no. Neither result tells you much about the underlying pattern. Run the identical prompt repeatedly; ten separate runs are a more useful starting point than one, not a certificate of statistical certainty. Record what appeared in each answer rather than saving only the screenshot that made everyone happy.
That run-level variation is why I would rather track a tight panel of 50 buyer prompts repeatedly than 500 prompts once each. Live search results can change, and the answer you get can change with them. Nick Lafferty’s analysis of AI visibility metrics makes the case for paying attention to variance between runs; Cloro’s sample-size modeling shows how easily a short streak can mislead you. If each of three independent checks had a 50% chance of showing your brand, the chance of seeing no appearances across all three would still be 12.5%. In my PPC days, I did not delete an ad group after three zero-conversion days on tiny volume. I waited for more data. Do the same here.
“How can a small business automate brand monitoring in AI search in-house?”
You can build a workable monitor with a Google Sheet, a scheduled script, and somewhere to store the answers. But watch what you are actually testing. A team can send its prompts to a basic model API, log the text, and call the spreadsheet an AI visibility report. If that setup does not use live web retrieval, it may not reflect the answers a buyer gets in a consumer product with search enabled.
The distinction matters. A prompt sent to a model without browsing tools can draw on its existing knowledge; a consumer answer using web retrieval may also draw on current pages and display citations. As practitioners discussing AI visibility monitoring have noted, those are different things to measure. If you need to know whether buyers see your current product page or a competitor’s recent comparison, do not quietly substitute one for the other.
If your team has the technical capacity, an in-house pipeline can follow three steps:
- Run your fixed buyer prompts through the consumer experiences you intend to measure, using scheduled browser sessions where appropriate.
- Store the raw answers and source URLs so you can revisit what appeared, not just a score derived from it.
- Classify each appearance as a mention, a citation, or an explicit recommendation, while recording when your brand is absent.
The hosting bill can be modest. Maintenance is the expensive part. Interfaces change, bot defenses interrupt automated sessions, and a scraper that worked last week can fail today. I have watched sharp growth leads turn into full-time scraper mechanics, spending eight hours a week fixing selectors and blocked sessions instead of improving conversion funnels. If maintaining the monitor takes more time than acting on its findings, your cheap setup is not cheap.
“What is the best software to automate AI search visibility reporting without hiring an agency?”
I would not pick one by its proprietary 0–100 score. When practitioners compared commercial AI visibility tools, the same brand received sharply different scores from different platforms. That should make you ask what each platform measured, not which number looks better in a board slide.
Synthetic prompt sets, weighting rules, and run frequency can all change the result. In paid search, I would never accept a campaign-health score that hid the search terms and bids behind it. Demand the same visibility into the inputs here. Before you pay for a monitoring tool, ask:
- Can I upload and freeze my own prompt panel? If you cannot control the questions, you cannot reliably compare them with the questions your buyers ask.
- How many runs per prompt are included? One weekly answer per question leaves too much room for run-level noise.
- What experience does the tool query? Find out whether it measures consumer answers with live retrieval or a backend model call without search.
- Can I export the raw answers and citation URLs? You need the underlying evidence to investigate why a competitor appeared and you did not.
Even a tool that passes those tests is still a monitor. Quattr’s breakdown of enterprise AEO tools separates products that log visibility from systems that act on what they find. Think of monitoring as a smoke detector: it can alert you when a competitor displaces your brand, but it will not clear a crawler block, repair product information, or change the pages an answer cites. Buy telemetry if you need telemetry. Do not mistake it for execution.
“Should I track my brand name or my category questions?”
In paid search, branded campaigns can make an account look wonderful. Someone searches for your company by name, clicks your ad, and converts. The reported ROAS looks excellent, but the prospect was already looking for you. I have seen that kind of reporting obscure the harder question: who is winning buyers who have not chosen a company yet?
AI visibility has the same trap. Ask ChatGPT, “What does [Company Name] do?” or “Read reviews for [Product Name],” and you will probably see your brand. It looks good on a slide. It tells you little about whether you appear when an undecided buyer asks for options.
Put unbranded category questions at the center of the panel: “best automated inventory management for multi-warehouse Shopify stores,” “enterprise alternatives to Zendesk with flat pricing,” or “how to stop ad click fraud on Google Search.” Those are the prompts where the buyer needs a shortlist, not a description of a company they already know.
Keep a small secondary set of brand-name questions to catch false pricing, dead products, or other inaccurate answers about you. But put roughly 85% of your core tracking panel on commercial category questions where you compete with two to five peers. That is where recommendation share tells you something useful about potential demand.
“What number do I report to my boss?”
Do not lead with “we appeared in 45% of AI answers.” On its own, that number conceals who else appeared and how the answer presented them. If your brand shows up in 45% of answers while a competitor shows up in 90% and repeatedly gets the top recommendation, your dashboard can improve while your position in the shortlist gets worse.
Report Share of Model, or SoM, alongside recommendation rate. Using the approach described in MaxAEO’s brand visibility methodology, divide your brand’s mentions by all category-brand mentions across the same prompt cohort. If 50 buyer prompts produce 200 total brand mentions over a week and 50 are yours, your mention share is 25%.
Watch the denominator. Suppose your mentions rise from 20 to 25, but total category mentions rise from 100 to 250. Your share falls from 20% to 10% despite the increase in your raw count. That is the number I would put next to the trend line, with separate counts for citations and recommendations. It does not explain every buyer outcome, but it stops a growing appearance count from hiding a faster-growing competitor.
“Once I can see the gap, who fixes it?”
This is where many AI visibility projects stall. Learning that Gemini cites a competitor more often, or that ChatGPT leaves your product off a buying shortlist, gives you a diagnosis. The report does not make the repair. In paid search, if an audit shows mobile buyers dropping out at checkout, you do not admire the chart every Monday. You change the page and check what happened.
Yet businesses can spend thousands a month on monitoring dashboards and deposit the findings in Slack, where nobody has the time or remit to act. An agency may offer a monthly content retainer and a couple of generic comparison posts. That is a poor fit when the work could involve a crawler block, unclear product information, weak third-party coverage, or a paid-search opportunity you can pursue while the organic gap remains.
The useful handoff is from detection to an owned action. Identify the prompts where you lose the shortlist. Check the cited pages and the answers’ claims. Then assign the work: fix a technical access problem, improve the page that should answer the buyer’s question, address the comparison gap, or use paid search to reach relevant demand while organic visibility catches up. Measure the same frozen prompts again afterward. Otherwise, you bought a recurring description of the problem.
“How do we close the gap between detection and execution?”
That is the question I wish people asked before buying another visibility score. I spent years managing search campaigns, and the lesson stuck: measurement earns its place when it changes what you do next. A score drifting from 42 to 46 is not a decision. Knowing which buyer questions exclude you, which competitors appear instead, and who will act on the difference is.
At groas, we built an autonomous growth engine around that handoff. Specialized models execute campaign, content, bidding, targeting, and visibility work across paid and organic search, while a named human strategist sets direction and guardrails and remains accountable for outcomes such as attributable revenue and cost per acquisition. That is a better use of the data than paying for a dashboard that documents your absence or a retainer that waits for the next monthly check-in. Measure AI answers like a PPC test. Then put someone, or something, in charge of doing the work the test reveals.
Frequently asked questions
What is the difference between a mention, a citation and a recommendation in AI answers?
A mention means the answer names your company in running text without linking to your site. A citation means the answer links to a specific URL as support, often in a reference drawer or footnote. A recommendation means the answer evaluates your product against the buyer's criteria and puts it on a shortlist, which is the strongest signal.
Why should I keep my AI visibility prompts frozen?
If you rewrite a question halfway through the month, you cannot tell whether a change in visibility came from the answer engine or from your new wording. A frozen panel lets you compare like with like. Build a fixed set of roughly 30 to 50 buyer prompts from sales calls, support tickets and bottom-of-funnel questions, then leave them unchanged.
Does an AI visibility tool actually fix the problems it finds?
No. A monitoring tool can alert you when a competitor displaces your brand, but it will not clear a crawler block, repair product information, or change the pages an answer cites. Treat it as telemetry, then assign the repair work to people and re-measure the same frozen prompts afterward.