
 LinkedIn
The hero says get featured in Google AI Overviews. The plan underneath mostly sells a better view of not getting featured. I picked a composite AI visibility feature page for this teardown because its six familiar tiles make that gap easy to see: visibility score, prompt tracking, competitor share, recommendations, content optimizer, and schema checker. It is not one vendor’s page. It is the page I keep seeing with a different logo on top.
I read each tile into one of two columns: changes what Google can lift or shows you that it didn’t. On this page, the second column is at least three times longer. That is the test I would bring to any tool promising AI Overview visibility. Does anything on its feature list touch your actual pages?
The hero promises a citation; the page sells six tiles
The composite opens with an answer-box screenshot and a few reassuring logos. Scroll past the hero and the tiles arrive: an AI Visibility Score, prompt tracking across engines, competitor share of voice, actionable recommendations, a content optimizer, and technical health or schema checks. The pricing table comes later. That is where get featured starts to look a lot more like get measured.
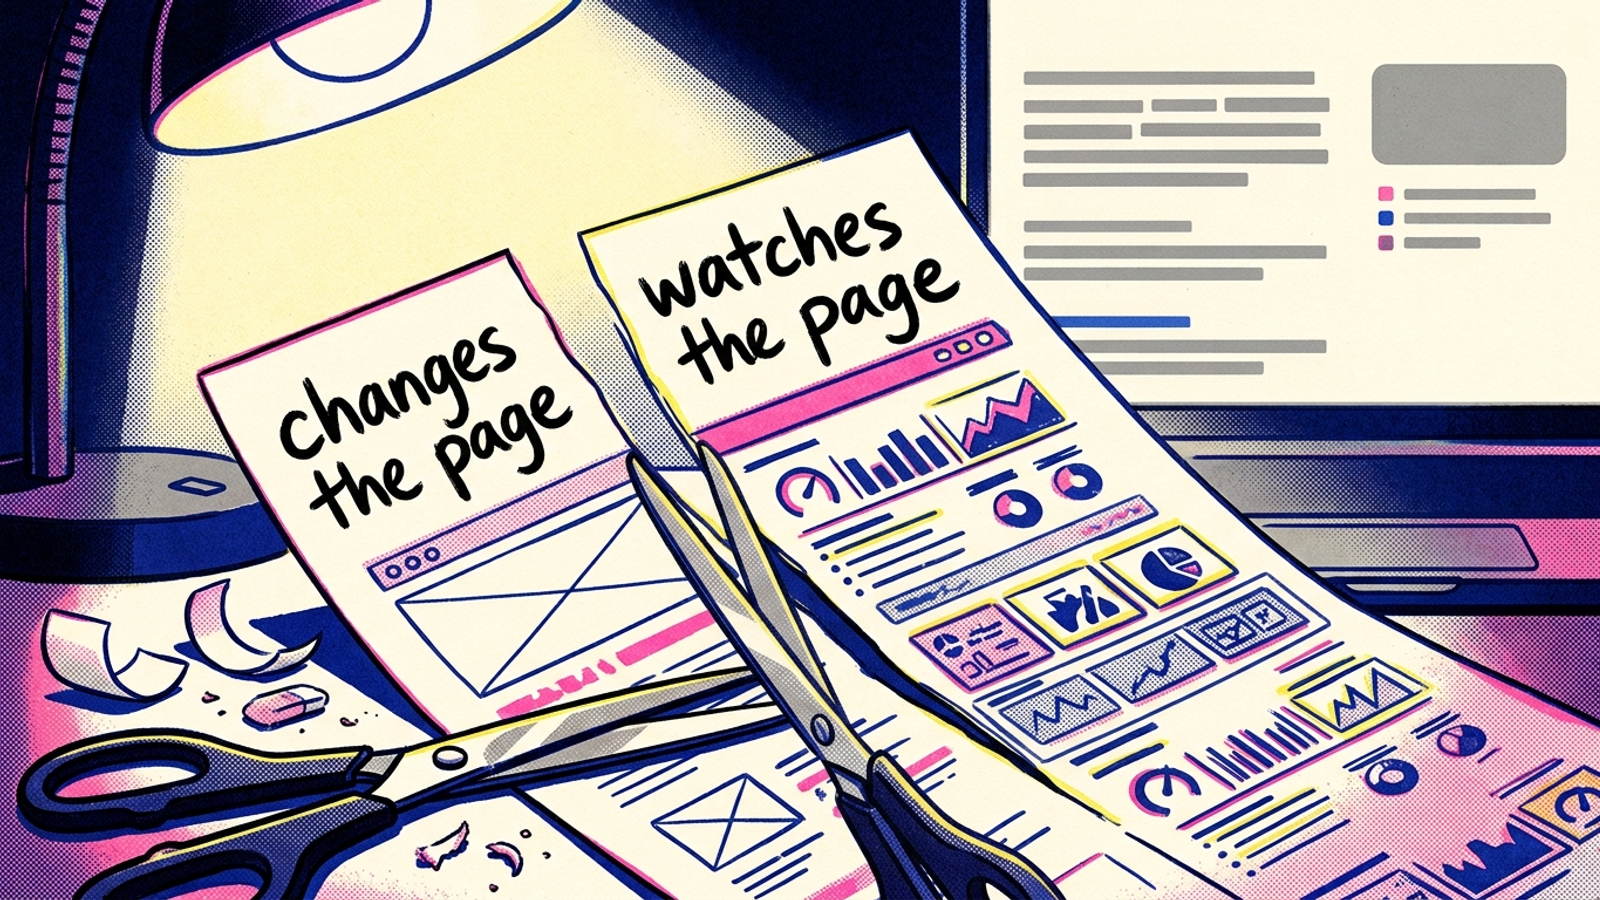
Monitoring plans run about $29 to $489 a month, metered by prompts and engines. The work that includes content and authority costs agency money. You can see the monitoring model in the plan limits: Profound lists $99 Starter for ChatGPT only and $399 Growth for three engines; Peec lets you pick three of six engines, with Claude kept for Enterprise; and Otterly includes four engines, with Gemini, AI Mode, and Claude as paid add-ons.
I used to tell clients to start cheap and upgrade. That advice misses the point here. A cheaper monitoring tier buys fewer engines watched, not more pages fixed. Before comparing prices, count what the plan lets the vendor touch, not what it lets the vendor count.
The test behind the teardown: can Google lift a passage?
Before the first tile, one distinction matters. A page must be indexed and eligible for a plain Search snippet; there is no extra AI requirement beyond that. From there, Gemini breaks a query into sub-queries, retrieves passages rather than whole pages, and stitches together an answer from typically three to five sources with inline links. If your landing page has no passage that can stand alone as an answer to one of those sub-queries, a prettier dashboard cannot supply one.
That is also why rank and citation are different reports. An Ahrefs study of 863,000 SERPs found that only 38% of cited pages ranked in the top 10 for the same query; about 31% sat at positions 11 to 100 and another 31% outside the top 100. Improving a rank average does not, by itself, show that Gemini can lift a better passage. Keep one question in mind as we scroll: did the feature change something Google could use, or did it record the answer you missed?
Tile 1: AI Visibility Score counts citations; it creates none
First comes the big number. Say your score is 42, up four points this week, with a green arrow doing most of the emotional work. Behind it sits a sample of tracked prompts and the engines included in your plan. The vendor counts where your domain appears in answers or nearby links, then rolls those observations into a score. A buyer guide advises you to press vendors on sampling because single-pass scores can present noise as signal. Run the same prompts again and answers can change.
That does not make the score useless. It can tell you where to look. But the number cannot tell you which sentence to replace on a landing page, and a rising score is not a published improvement to that page. Verdict: column two. The score records whether a passage got lifted. It writes no passage. Use it as a signal to investigate, not as evidence that the tool did the work.
Tile 2: Prompt tracking maps the work but does not do it
Next is a table of prompts, each marked yes or no for ChatGPT, AI Overviews, Perplexity, and whichever other engines you pay to watch. Of the monitoring tiles, this is the one I would keep. Prompt choice decides what you notice. AI Overviews show in about 16% of desktop searches and appear most often on longer, multi-word queries. The same guide notes that Reddit takes 21% of citations, YouTube 18.8%, and Quora 14.3%. A tracker following only ten head terms can miss the longer questions where a landing page has a shot.
Read the engine labels carefully, though. A mention in another engine’s answer is not an AI Overview citation. The useful output here is a shortlist: which question-form prompts matter, where your page is absent, and which page you should inspect next. That is valuable input. It is still input. Verdict: column two. Prompt tracking tells you what to fix first; it fixes none of it.
Tile 3: Competitor share shows whose passage won
Then comes the stacked bar. A competitor owns 34% of your tracked prompts; you own 9%. It is an excellent chart for making a renewal conversation feel urgent. Its honest use is narrower. If the same rival wins the same five prompts week after week, open the cited page and inspect the passage Google keeps pulling. Buyer guides rightly pair competitor benchmarking on the same prompts with citation tracing to the exact page pulled. Without that page-level link, the bar is mostly trivia.
Imagine a home services landing page that answers a question three screens down while a rival puts its answer near the top. The share chart can expose the gap. It cannot move your answer, cut it into a standalone block, or publish the change. Someone still has to make that edit. Verdict: column two. Knowing who got cited never becomes a citation for you. Keep the chart only if it points to a passage you can inspect and improve.
Tile 4: Actionable recommendations are briefs, not execution
This tile sounds like work: add an FAQ block, shorten the introduction, earn mentions on trusted sites. Ask who does those things. As one pricing breakdown explains, monitoring flags gaps and surfaces prioritized recommendations that you must act on in-house or outsource. Another buyer guide puts it plainly: knowing you are not mentioned is a diagnosis; a tool that stops at a dashboard is a monitoring tool.
The distance between diagnosis and publication is where a good recommendation can sit untouched. One execution-platform writeup describes teams sitting on data for six to eight weeks while diagnosis took days and approvals took weeks. I would rather see one approved page change than another prioritized queue. The recommendation has to name the page, identify the passage, and lead to an edit someone can ship. Until then, verdict: column two. A recommendation you still have to staff is a brief, not execution.
Tile 5: A content optimizer belongs in column one only if the edit ships
This is the tile I read twice. A content optimizer can change a passage Google lifts, but can is carrying a lot of weight. The useful version does more than grade prose in a sidebar. It produces a 40- to 80-word answer-first unit, one idea per 75- to 225-word passage that can stand alone, with lists or tables where they help and question-form H2s. Where a claim needs weight, it can add a cited statistic or quotation. That structure fits with the Princeton GEO study finding a 30% to 40% visibility lift from cited statistics and quotations.
I would check the output, not the feature name. Does the optimizer publish to your CMS, or at least hand you a finished block ready to paste? Then it has produced something that can change the page. Does it merely score your draft and suggest that an answer should appear earlier? Back to column two. A suggestion may be good; the tool has not made the change. Verdict: column one only when it produces an edit that gets published. Touch the page or it did not happen.
Tile 6: Technical checks matter when warnings become fixes
The last tile lists 47 passed checks and three warnings: missing FAQ schema, a slow mobile score, a blocked script. These may be real problems. A warning, however, is still one step removed from a citation. Article, FAQ, and HowTo schema, along with about, mentions, and sameAs, can remove friction for a parser but will not earn a citation on their own. A clean, valid page with nothing quotable is still a weak source. A plain page with a clear passage can be useful without a wall of markup.
So I want the report to say more than issue detected. Was the fix applied? On which page, and when? Was the page checked again afterward? Those questions separate a crawler from a service that clears an obstacle. Verdict: a flag is column two until someone ships the fix. The line worth paying for reads: fix applied, date, page.
Now read the plan limits against the hero
We have reached the pricing table. Go back to the hero for a moment: get featured. Now read the limits: track 50 prompts, three engines, weekly refresh. One promises an outcome; the other specifies a monitoring allowance. The gap is easy to miss because every tile has a useful-sounding name. It is harder to miss after sorting the verbs.
Monitoring plans sit at $29 to $489 a month because they meter prompts and engines. Full-service programs run $9,000 to $15,000 a month or more because they include content, schema, and off-site authority work. Those are different things to buy. A monitoring plan can help you choose work. Do not mistake its prompt allowance for a commitment to do that work. If the limit is on how much the vendor watches, ask what, if anything, the plan changes.
What I would keep from the feature page
Two capabilities survive the sort as execution. First, a rewrite that ships: not a grade or a suggestion, but a finished answer block with a question-form heading, a direct answer up top, and a sourced statistic where one belongs, published to the landing page rather than stranded in an approval queue. Second, a technical fix that ships: an identified obstruction cleared or useful markup added, with the page checked again afterward. If a feature neither changes a passage nor clears the path for Google to use one, it is not execution.
I would also keep prompt tracking, but give it its proper job. It is a map for choosing targets, not a machine that puts a page into an Overview. I pay for that input only when it points the work somewhere useful. I laid out which tool capabilities can help a business get featured in AI Overviews and which only report on visibility in more detail. groas belongs on the execution side of that distinction: it writes and publishes page blocks, applies technical fixes, and builds corroborating mentions instead of handing me a PDF of recommendations to staff myself. It is the distinction behind my comparison of DIY checks, visibility trackers, and done-for-you AEO: the last option changes the pages that the first two inspect.
Verdict: keep the map, buy the work
Count the verbs on any feature page. Track, measure, monitor, alert, benchmark: reporting. Rewrite, publish, fix, ship: execution. Earn may be the goal, but make the vendor show you the page work behind the word. On this composite, the reporting column is much longer than the execution column. That is why the hero can say get featured while the plan limits say monitor.
My keep list is short: prompt-level tracking to pick targets, a content optimizer whose edits get published, and technical checks tied to applied fixes. Everything else has to justify its place by leading to one of those actions. If nothing on the list touches your pages, the tool is watching the answer, not changing it.