

 LinkedIn
You sell prefabricated garden workspaces. Your buyer wants to know why the shed office is freezing by November and the Wi-Fi drops every time it rains.
Same problem. Different vocabulary. Say your product is an installed backyard office pod: insulated, heated, wired, craned over the fence in a day. That might solve the buyer’s problem, but your category name is not where their search begins. I used to tell clients the fix was better category pages. I was wrong. The fix starts earlier, with the words buyers use before they learn your label.
That is the connection I use groas’s Reddit research and AI-answer data to make: find the language buyers use, observe which pages help answer those questions, and give my AI the language and evidence to build something useful.
The gap is bigger than a keyword report suggests. For most of October 2024 to February 2026, 65% to 85% of US ChatGPT prompts could not be matched to any keyword in a 27B+ keyword database. A blank keyword report does not mean nobody has the problem. One analysis of new-category offers illustrates the distinction with I manage a 12-person remote team missing deadlines, rather than best project management software.
Everything that follows starts there: buyers can describe a situation without knowing what to call the solution. Different questions then need different evidence. Before I ask an AI to write a page, I want to know both.
One product, four questions, four different jobs
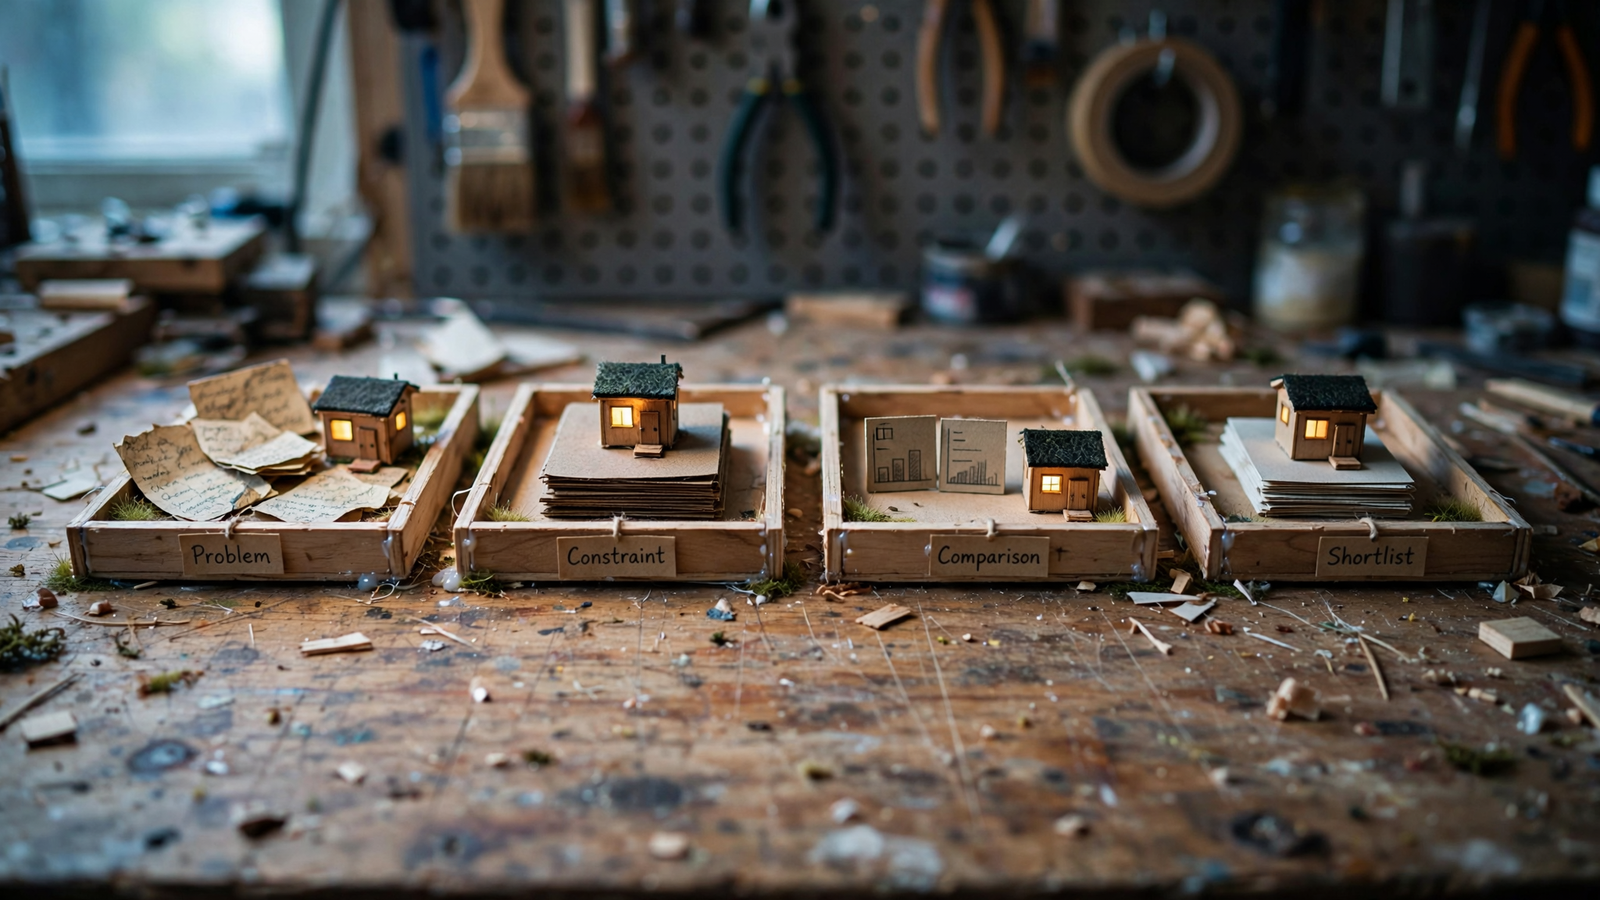
Stick with the backyard pod because it keeps the mechanism visible. The buyer does not need your category vocabulary to know they are cold. Over a few weeks, that same buyer might ask:
- Problem: “How do I heat a shed office in winter without running up the bill?”
- Constraint: “Can you put a wired office in the garden without planning permission in the UK?”
- Comparison: “Garden office pod vs shed conversion vs extension, cost and insulation.”
- Shortlist: “Who installs insulated garden offices near Manchester?”
Those questions share a buyer and a budget, but not much vocabulary. The first two never use your phrase prefabricated garden workspace. They describe a shed, heating, wiring and planning permission. If your site only uses the coined label, retrieval can miss it because the engine never searches that label.
The buyer described the situation. You filed it under another name.
I ran into this for years in Google Ads before I saw it in AI answers. I used to tell clients to tighten exact match around the category term, then watched Search Terms fill up with longer, messier phrases that converted better at lower CPC. The same blind spot shows up when keyword tools report zero volume for new-category terms even though problem-language demand exists. The demand lives in sentences, not just head terms.
Write the buyer’s sentence first and your category name second. If you cannot describe the offer in four problem-first phrasings without your own jargon, start with translation, not another category page.
Each question determines what counts as useful evidence
Now look at what an answer has to contain. The four questions are not interchangeable ways to ask for a pod recommendation:
- Heating the shed needs instructions: watts per square metre, condensation control, what actually failed in February.
- Planning permission needs a rule and its boundaries: height limits, permitted development, when approval is required.
- Pod versus conversion needs costs and insulation compared side by side.
- An installer shortlist needs business facts: service area, what gets installed, lead time and price range.
Different evidence makes different pages useful.
This also explains why getting cited is not the same as getting recommended. In one test, informational what is and how does prompts had an 89.3% citation rate but only an 18% mention rate. Comparative best, vs and recommend prompts reached a 43.3% mention rate, about 2.4 times the informational rate.
Most appearances in that analysis sat in between: 61.7% were ghost citations, cited as a source without being named in the text.
A heating guide can supply a useful passage without making its publisher the recommended installer. Helping answer the question and earning the recommendation are different jobs. Decide which job a page is meant to do before judging its appearance in an answer.
A useful heating guide does not prove you can install the pod
Your heating guide can appear for the first prompt and disappear for the fourth without anything being broken. The heating answer needs a clear method the assistant can quote. The installer shortlist needs supplier facts: where you install, how the unit gets craned in, what the base work requires, lead time and price band.
One page proves you understand the problem. Another has to establish that you can do the work. I learned this running PPC when a how-to guide pulled cheap clicks for months and never produced a quote request, because it never said who did the work or where.
Ranking alone does not settle this either. Ahrefs found only 12% of URLs cited by assistants ranked in the Google top 10, while Semrush found ChatGPT cited pages ranking at position 21 or lower almost 90% of the time.
Specific, retrievable passages matter. In one 200-prompt test of Perplexity answers, small niche sites tied or beat Forbes at 10 queries each. In the same analysis, Nimble received 15 citations and Insightly 13, compared with Salesforce’s 7. A familiar brand name did not automatically win the source slot.
For the pod business, I would separate the requirements: an extractable how-to page for the problem, a factual business page for the shortlist, and independent corroboration of the work. One category page should not have to impersonate all three.
Your business facts and other people’s experiences are not substitutes
Your site supplies the offer facts: service area, installation method, what is included and price band. Independent reviews and Reddit discussions supply other people’s experiences. Those are different kinds of evidence.
In a study of 200 B2B buyer prompts, Perplexity averaged 9.5 citations per answer across 750 unique domains. Reddit appeared in 96 of the 200 prompts, or 48%, ranking first in CRM, email, project management, analytics and support.
For the pod seller, though, Reddit is useful as a language source before it is a citation source. Threads contain the complaint, the attempted workaround and the reason that workaround failed. That is much more useful than a category term on its own.
I would use Reddit to capture conversational queries, recurring complaints and the reasons behind a search. Five threads about freezing shed offices might turn up phrases such as:
- “Condensation running down the walls.”
- “Wi-Fi extender died in the cold.”
- “Council complained about height.”
Those phrases give the page something concrete to answer. The workflow is unglamorous:
- Search a seed keyword and use the Communities filter.
- Search
site:reddit.comwith patterns such ashow do I,doesn't workorfrustrated. - Log the thread title, context and pain points.
- Cluster the verbatim phrases to guide headings and answer-first paragraphs.
That is the Reddit research routine stripped of the mystique. Collect the complaint and its context, not just a phrase to paste into a heading.
Observe ChatGPT and Perplexity separately
Buyer language gives me questions to test. It does not tell me in advance which source either engine will use.
Run the same four pod prompts in ChatGPT and Perplexity and the source lists can differ. Across five engines, pairwise source overlap was only 16% to 59%, while brand overlap was 36% to 55%. Engines disagreed more on sources than on brands.
One might cite your heating guide. Another might cite the Reddit thread where buyers describe the same condensation fix in their own words. Combining those observations into one score hides the distinction I need to understand.
For each run, I keep five fields:
- Exact prompt text
- Engine
- Cited URL
- What the answer actually said about the business
- Observation date
Then I repeat the set a week later before changing a page. One answer is a sample. Two matching answers are the start of a pattern, not a platform law.
The full routine is in my test for comparing ChatGPT and Perplexity citations without grading your own homework. It matters for the same reason a Google ranking does not guarantee a citation: ranking alone does not tell me what an assistant retrieves and uses.
Keep the prompt, engine and observation together. Otherwise, a handful of answers can start looking suspiciously like a universal theory.
Build the pages the questions require
At this point, the model gives an SEO and AI search provider a concrete build sequence. I want four things, in order:
- Buyer-language pages. Build around the distinct problem phrasings the research reveals. Put the buyer’s sentence in the heading and first 100 words; introduce your category name second, as the label for the solution. For the pod seller, the winter-heating question comes before the brochure vocabulary.
- Clear offer boundaries. State where you work, what you install, what it costs in a band and what disqualifies a buyer. Say you spend $20k a month on ads while your site hides the price band and service area. You are paying to attract questions your own pages leave unanswered.
- Technical access. Make the pages fetchable and parseable. No blocked renders. No essential answer buried only in video. A useful explanation cannot help if the assistant cannot read it.
- Credible independent mentions. Your own installation page describes the offer. Other people’s accounts can corroborate the work in the places buyers already discuss the problem.
This is not four ways to repeat the category name. It is a sequence from the buyer’s problem to the evidence needed to choose a supplier.
Where groas fits, and what the business still has to supply
I use groas for the part that needs machine patience. It watches Reddit threads and AI answers around the clock, pulls the phrases buyers use, and hands that language to the AI I already work in: ChatGPT, Claude or another agent connected over MCP.
That connects the two halves of the process. Reddit research supplies the buyer’s wording. AI-answer observations show which sources appear for those questions and how the answers talk about the business. My AI can then work from that material rather than inventing another polished variation of prefabricated garden workspace.
The business still has to supply what no tool can invent:
- Service area by postcode
- Installation method and what is included
- Price band and lead time
- What disqualifies a buyer
groas supplies the research and infrastructure; the business supplies the truth about its offer. Without those facts, better wording is still just better wording.
groas Unlimited costs $19 a month, flat, for unlimited teammates, ad accounts and websites. Every change is logged with its reason and can be undone in one step. Autopilot stays off until I switch it on.
What nobody can guarantee is the citation itself. Any provider promising a recommendation in ChatGPT is selling certainty the engines do not offer. I want a process I can inspect, not a promise I cannot test.
Test the model on a different product
Try a new case: heated mats that melt snow on domestic driveways. Your label is radiant snow-melt system. The buyer writes: “Driveway ices over, scared my mum will slip, council grit never reaches our close.”
The product changes. The reasoning does not:
- Problem prompt: “How do I stop a sloped driveway icing without gritting at 6am?” That needs a method page in the buyer’s words.
- Constraint prompt: Questions about running cost per storm, power draw and whether the mats work under a car need clear boundaries.
- Comparison prompt: Mats versus gritting versus full driveway heating needs a side-by-side comparison.
- Shortlist prompt: Choosing a supplier needs mat sizes, installation time, price band and delivery area.
I would start with those sentences, observe the answers separately in each engine, and build the four pages around the jobs they need to do. The label can follow once the buyer recognises the solution.
That stops one category page being asked to do four jobs. Buyers already told you the keywords. Reddit kept the receipt.


